
What is the GitHub Enterprise Server 'replica' node and how does it differ from a cluster node?
Select an answer to reveal the explanation.
Short Explanation
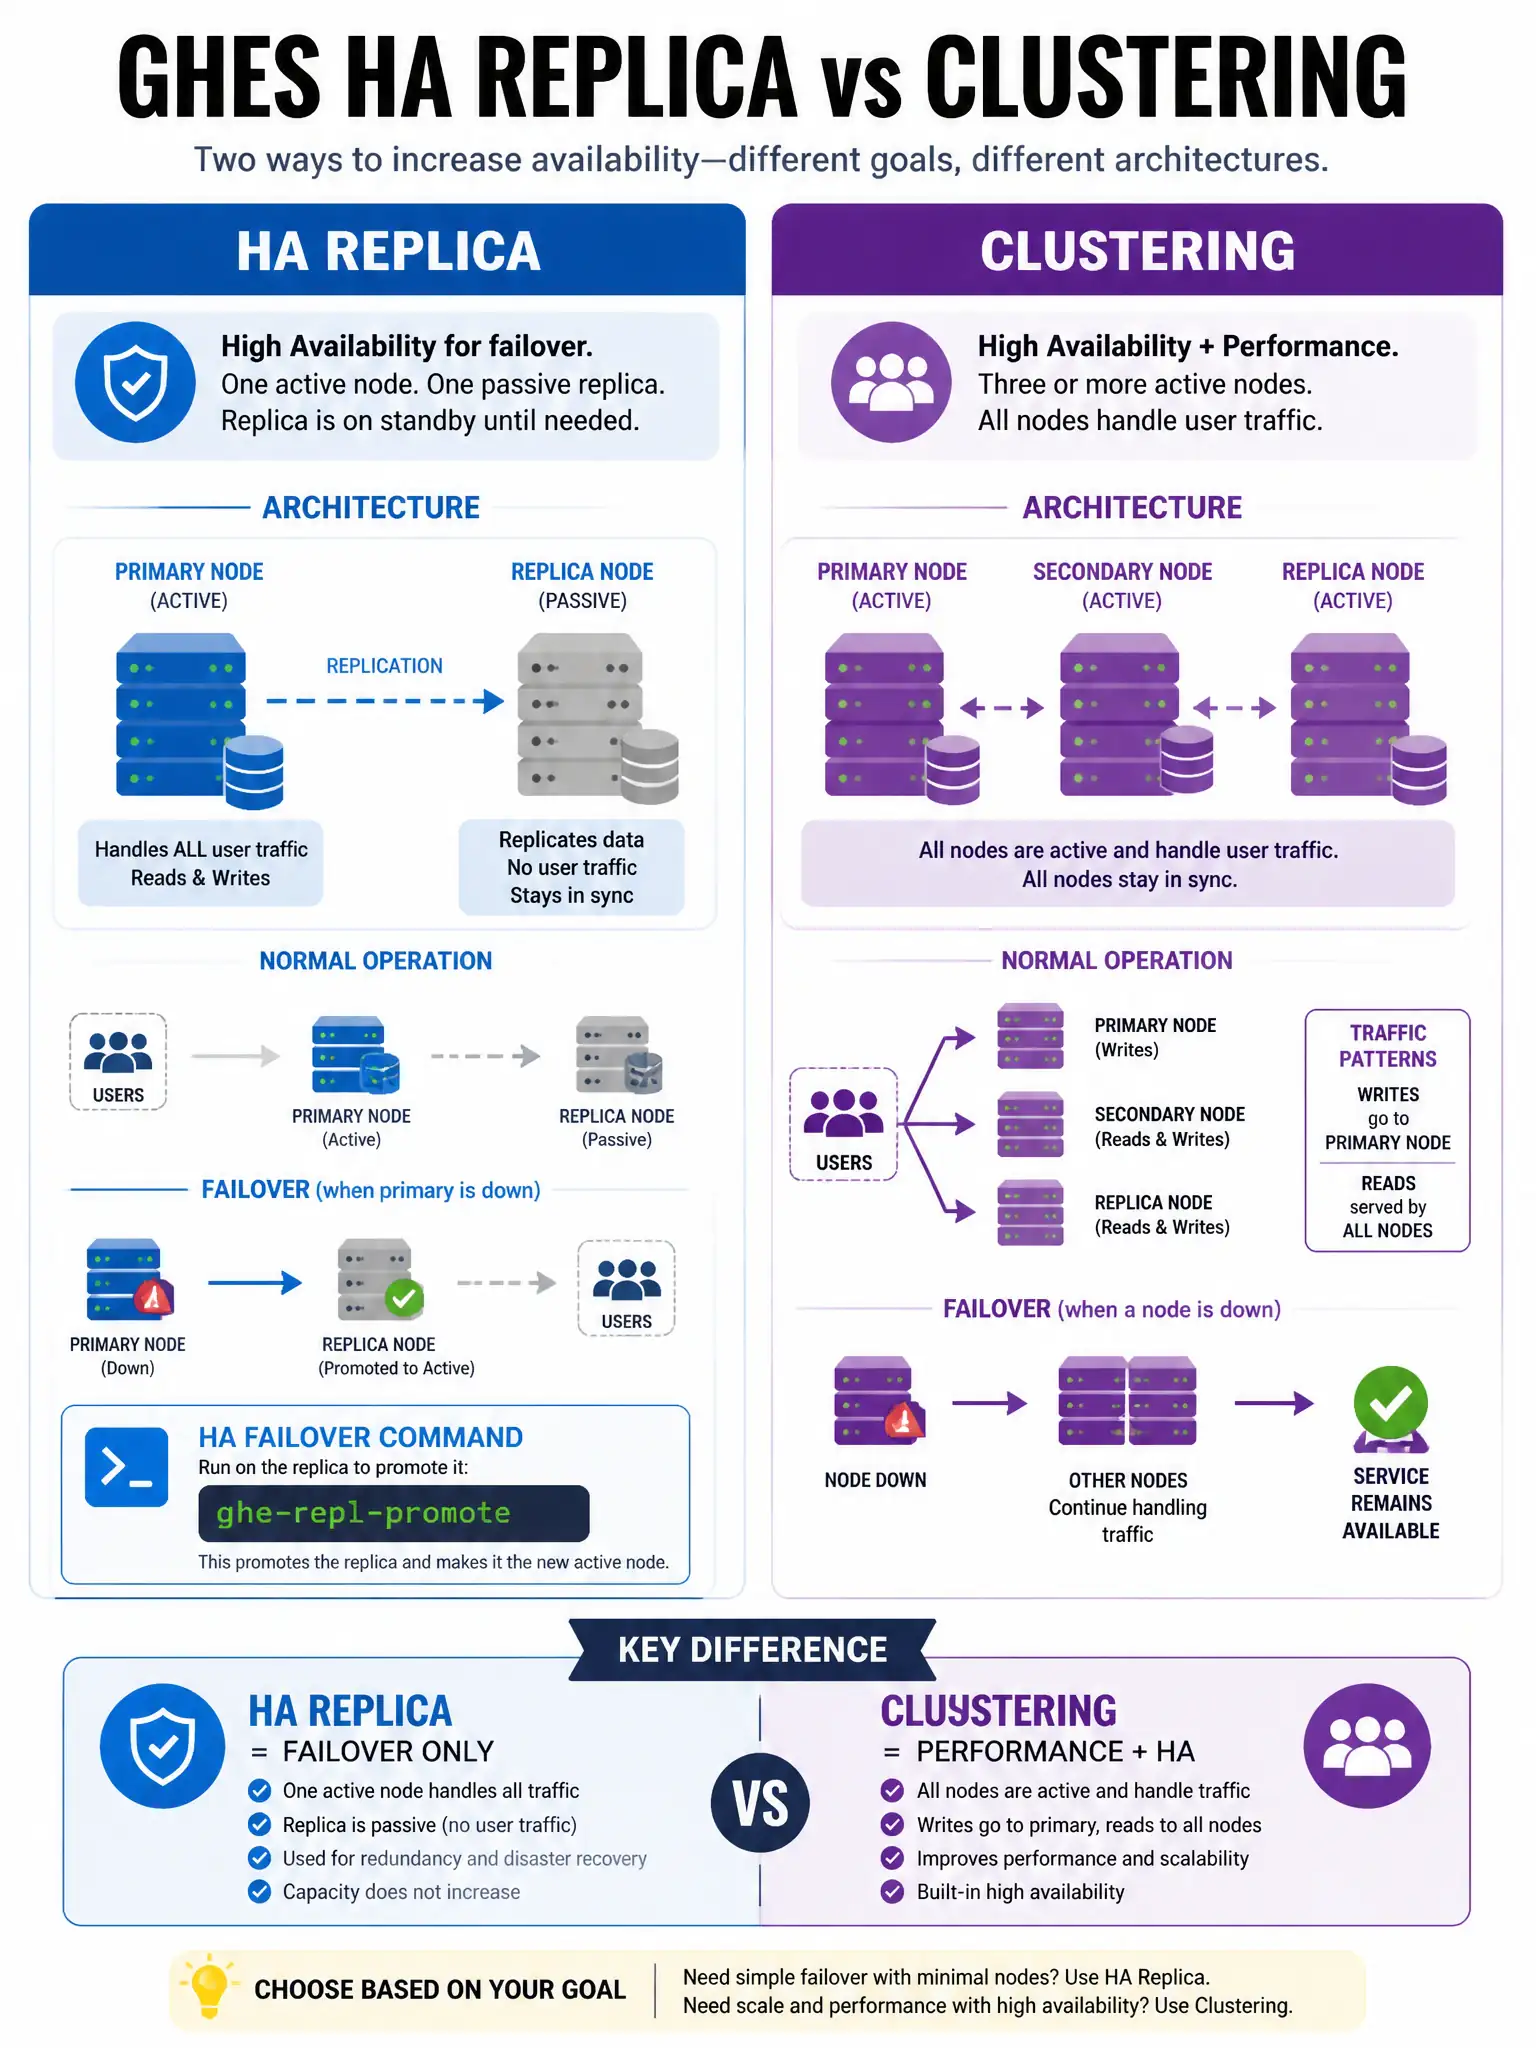
The replica is your hot standby. It mirrors the primary in real time but stays dark, and you promote it only if the primary fails. Cluster nodes are different because they actively serve traffic together.
Full Explanation
In GitHub Enterprise Server High Availability (HA), a replica node is a passive standby that continuously receives replicated data from the primary via streaming replication. It does not serve user traffic under normal conditions, but it can be promoted to primary if the primary fails using ghe-repl-promote, and it provides geographic redundancy when placed in a different datacenter. This differs from cluster nodes, where multiple active nodes collectively serve traffic. HA uses two nodes total: one active primary and one passive replica. Clustering uses three or more nodes all serving traffic, with writes to the primary and reads possibly distributed. HA is a warm standby for failover; clustering is active nodes for performance and resilience. A replica is not a full read-write copy handling all traffic, because it is passive until promoted. It also does not always serve read-only production traffic, because normal user traffic is not served by it. It is not only a backup target, because it can be promoted and serve traffic after failover.