
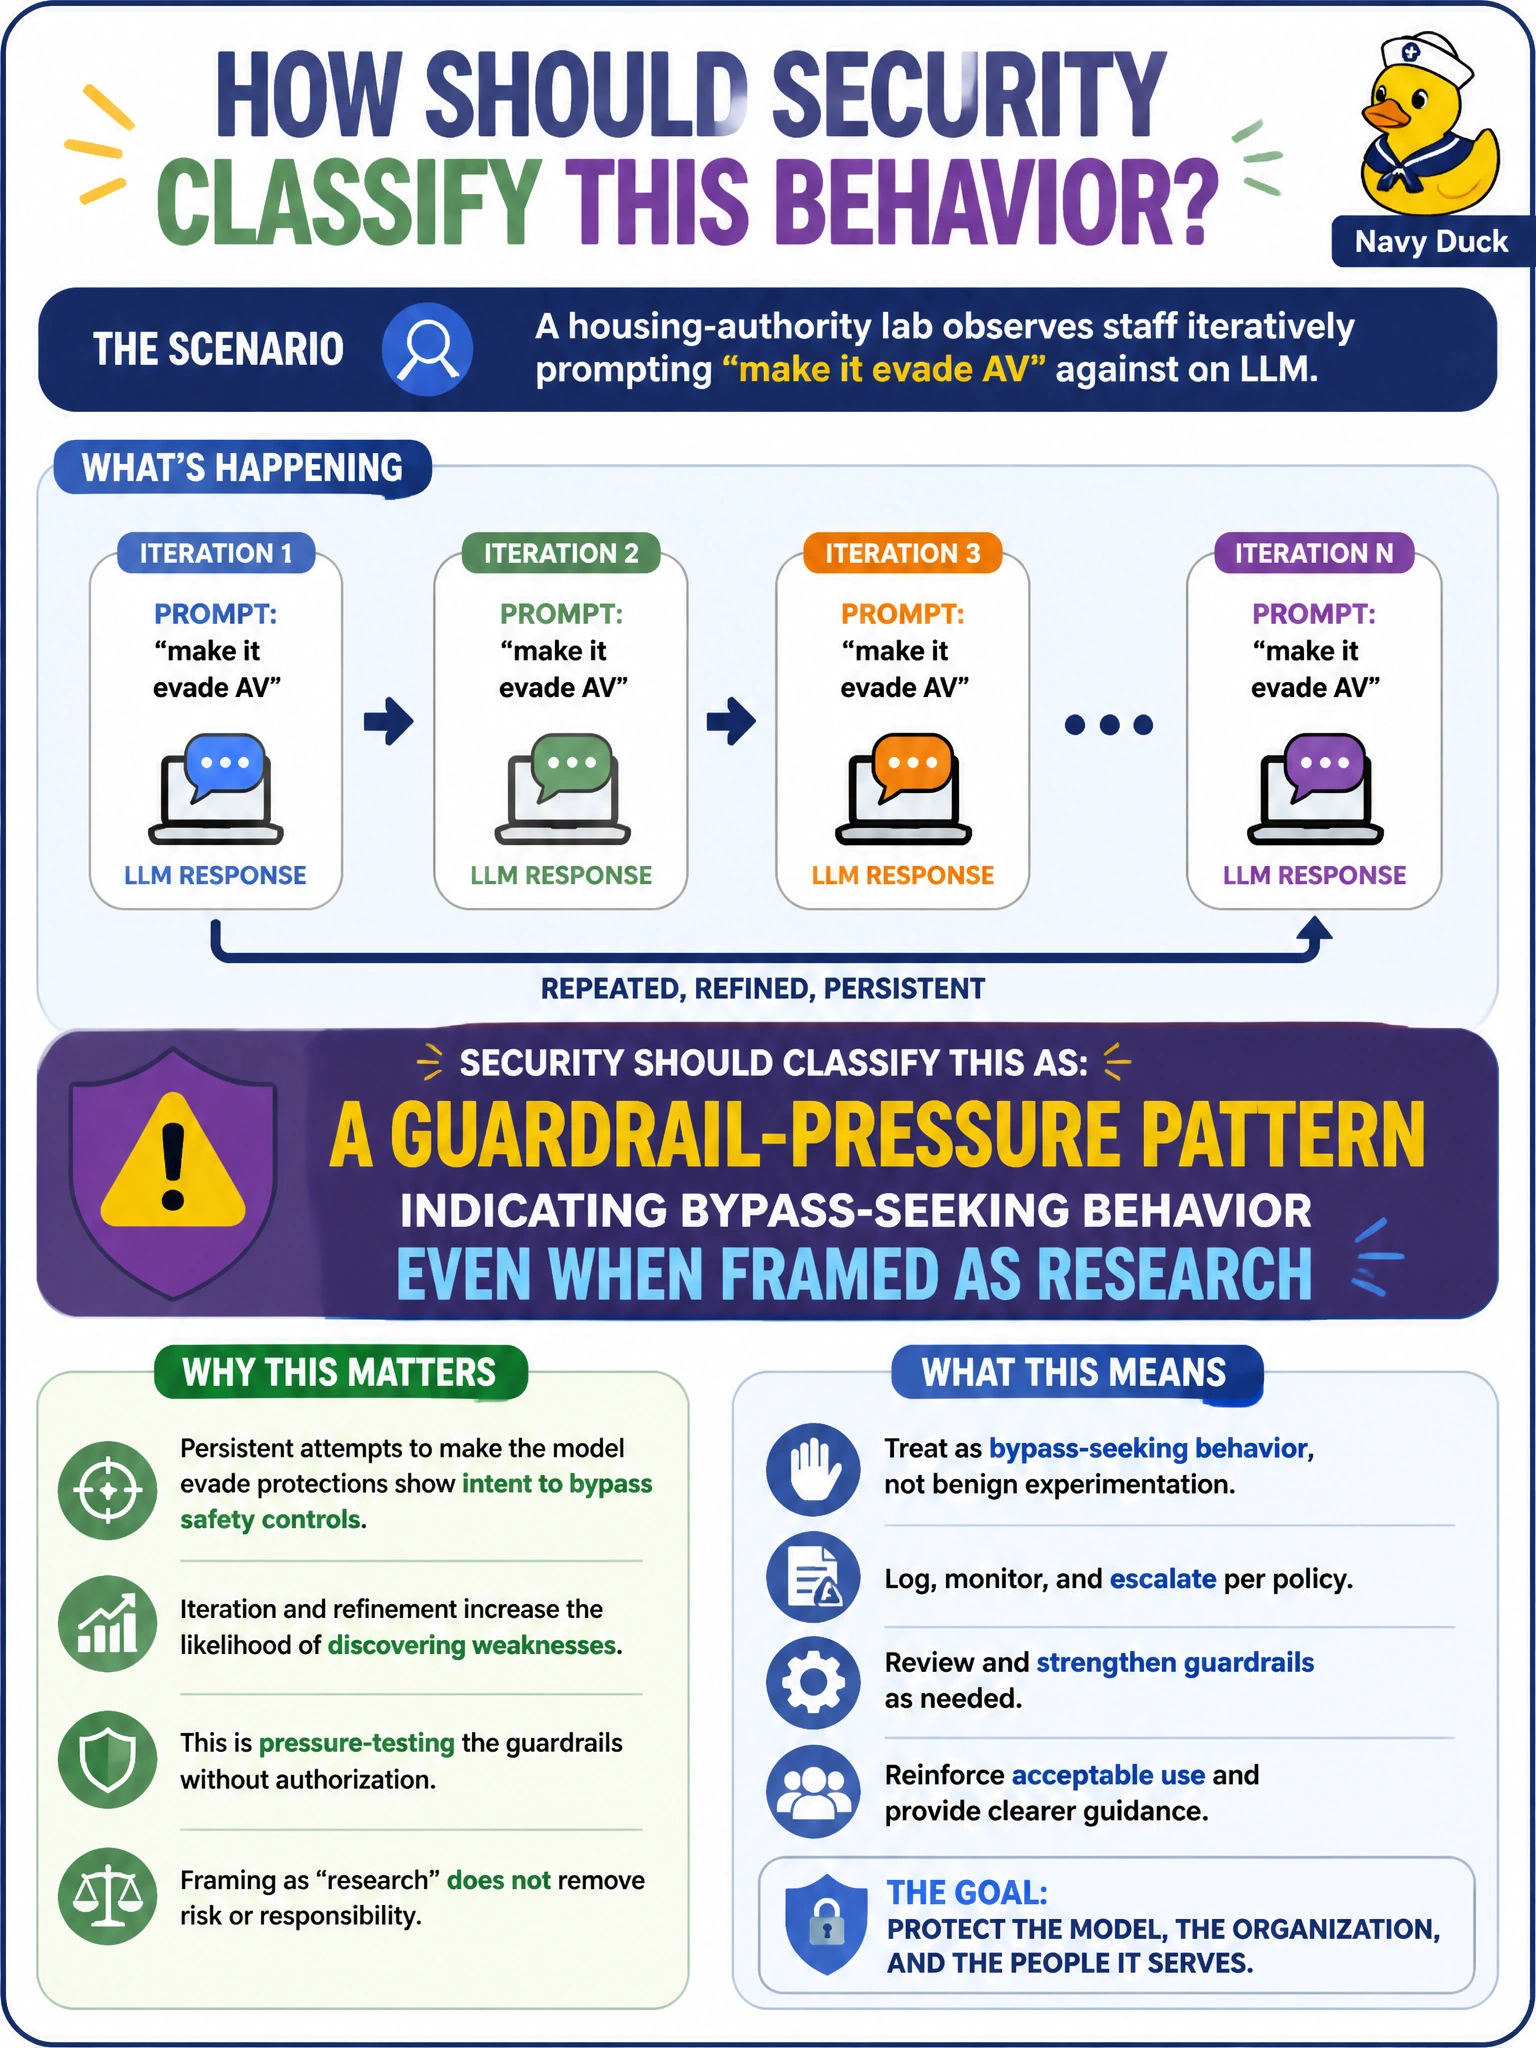
A housing-authority lab observes staff iteratively prompting 'make it evade AV' against an LLM. How should security classify that behavior?
Select an answer to reveal the explanation.
Short Explanation
Repeating 'make it evade AV' is leaning on the model's safety fence until it wobbles—research costume optional. Housing-authority security should flag that guardrail pressure, not put it on the help-desk chore chart.
Full Explanation
Housing-authority labs that observe staff iteratively prompting 'make it evade AV' against an LLM should classify that behavior as a guardrail-pressure pattern indicating bypass-seeking—even when framed as research. Repeated evasion coaching attempts probe model refusals and seek harmful offensive assistance. Security taxonomy and AUP enforcement should flag the pattern, coach or escalate the user, and route any legitimate testing need into an authorized offline lab with ROE rather than unconstrained chatbot sessions.
It is not proof that housing-authority endpoints need no antivirus; asking for evasion does not justify removing AV. It is not a required daily help-desk task. It is not unrelated to LLM security guardrails—the prompts specifically pressure those guardrails.
Exam caveat: iterative 'evade AV' prompting is bypass-seeking guardrail pressure, not a mandate to disable AV or a harmless unrelated activity.
Operational check: monitor housing-authority AI logs for repeated evasion/jailbreak phrasings, auto-warn or block, and require ticketed authorization before any AV-evasion research on approved lab models that never receive production exclusion lists or live tenant data.