
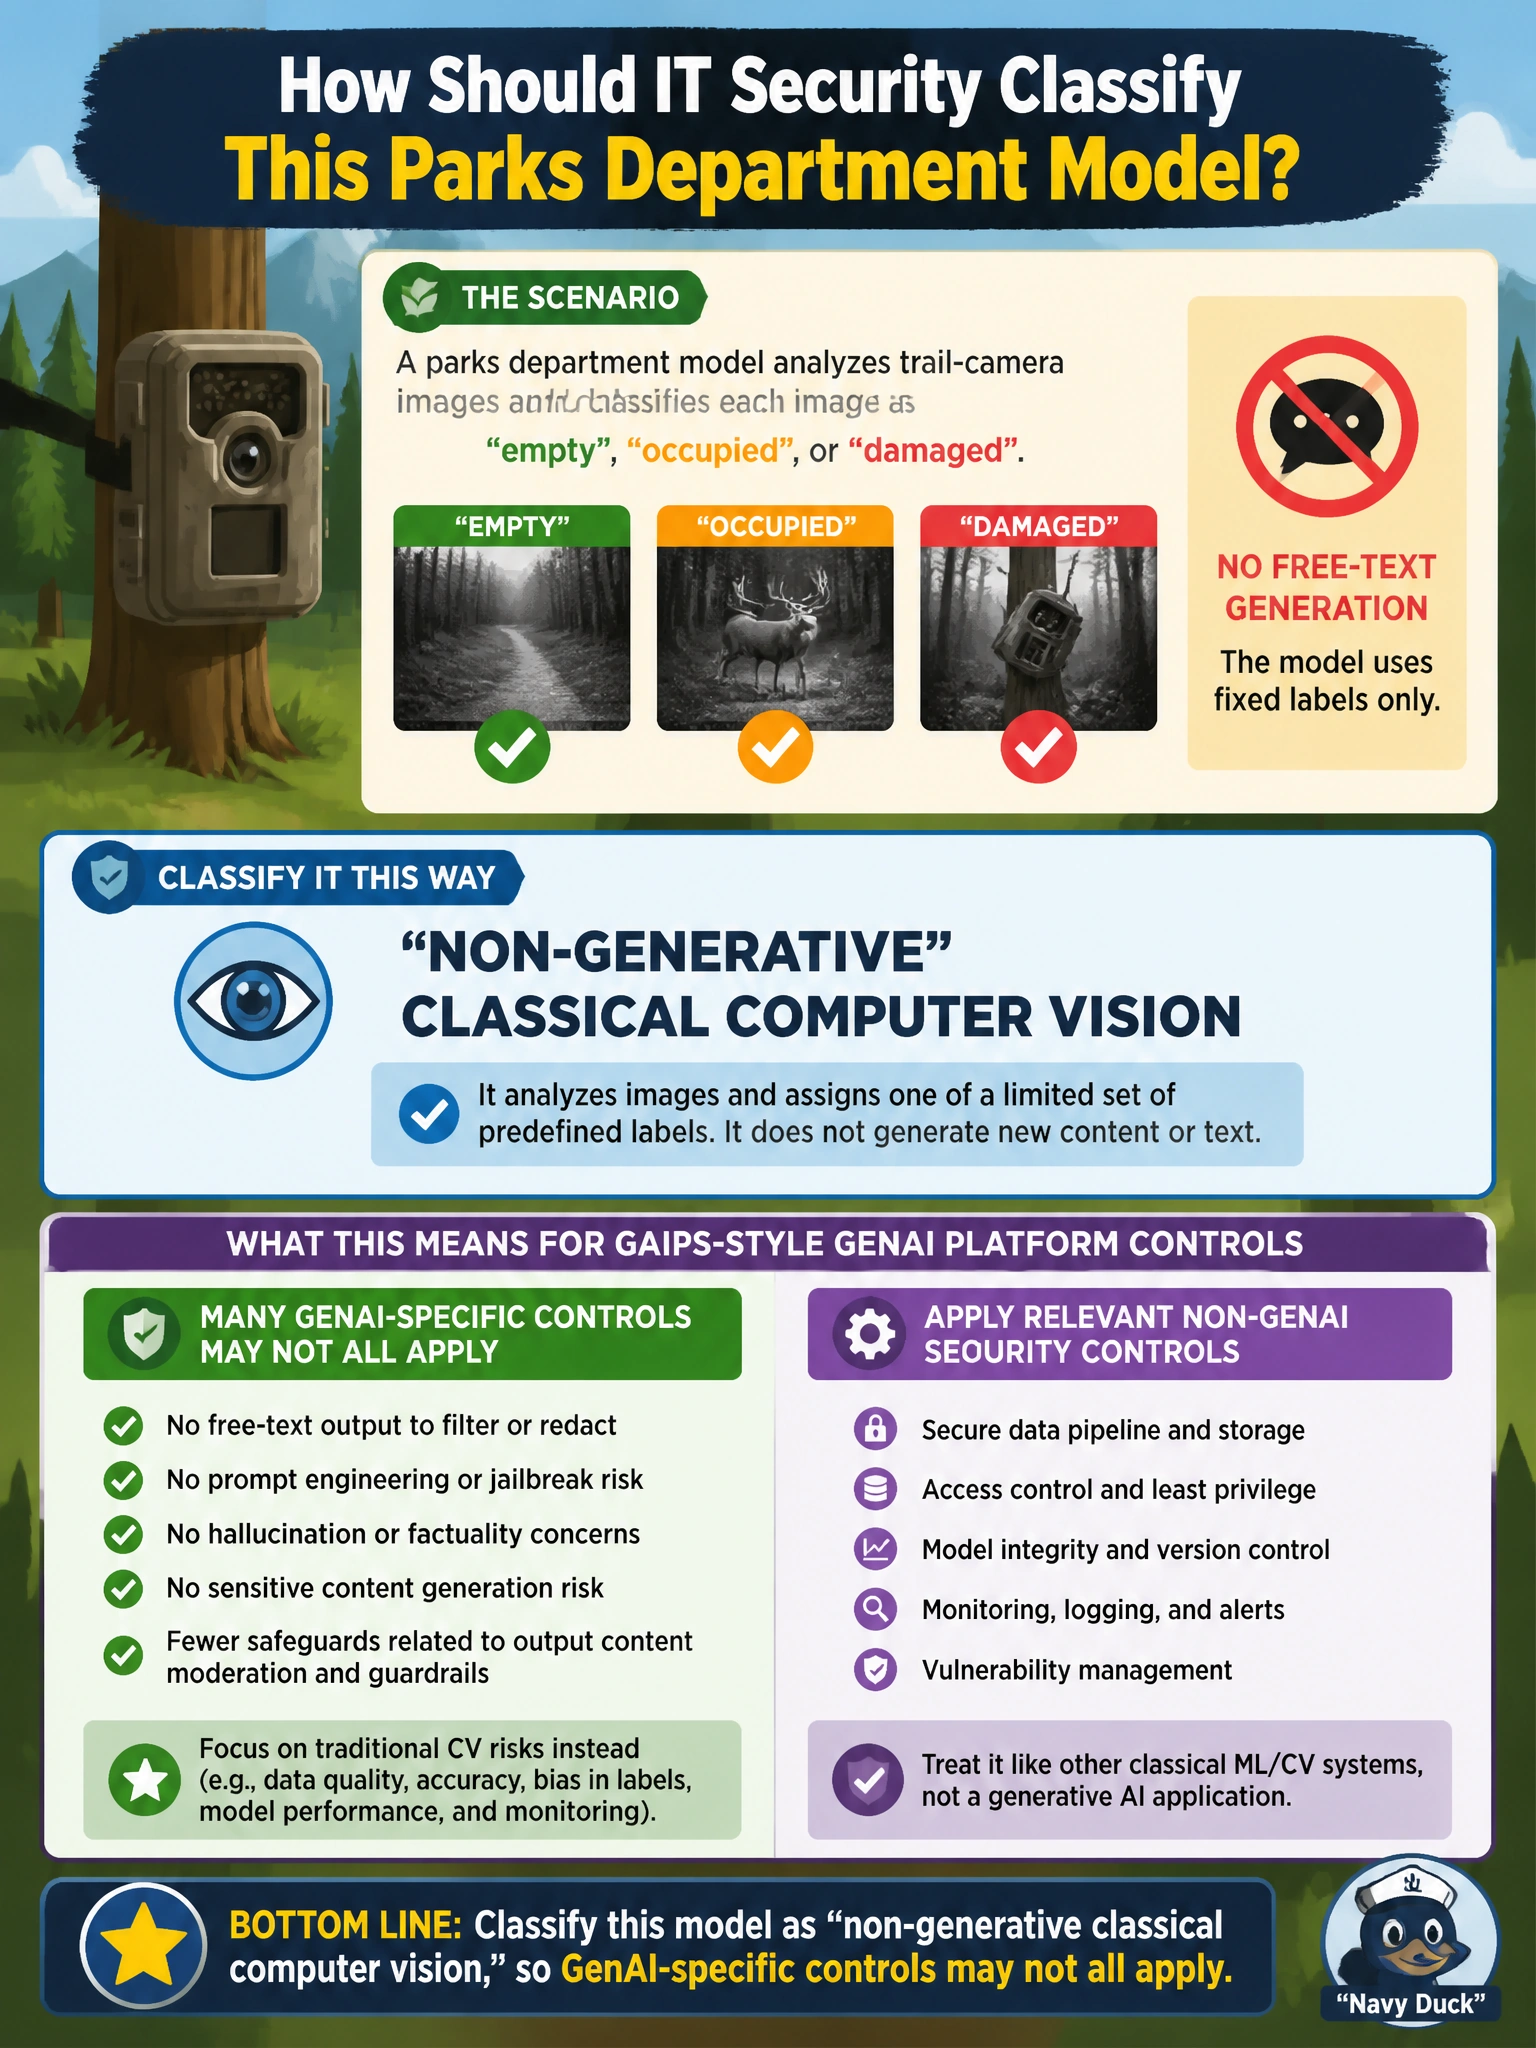
IT security reviews a parks department model that only classifies trail-camera images as empty, occupied, or damaged with fixed labels and no free-text generation. How should they classify it before applying GAIPS-style GenAI platform controls?
Select an answer to reveal the explanation.
Short Explanation
If the model just picks empty / occupied / damaged and never writes new prose or images, it is classical CV wearing a neural net, not GenAI. Do not slap every LLM control on it just because someone said 'AI.' Match the control set to whether the system actually generates novel content.
Full Explanation
Generative AI systems produce novel text, images, audio, or other content beyond a closed label set. A parks department model that only assigns trail-camera frames to fixed classes—empty, occupied, or damaged—and never generates free text is classical computer vision (discriminative classification), even if it uses a neural network. Before applying GAIPS-style GenAI platform controls, security should classify the system correctly so controls match the risk: prompt injection, hallucination, and decoding policies may be irrelevant or only partially relevant to a fixed-label classifier.
Calling it a generative LLM because any neural network "invents pixels" confuses learning algorithms with generative behavior; classification outputs a label, not novel content. Treating it as a multimodal agent because cameras imply tool use overstates agency—sensing plus fixed labels does not equal tool-using GenAI agents. Labeling it a RAG system because images sit on disk mistakes storage for retrieval-augmented generation; RAG retrieves content to condition a generative model, which this classifier does not do.
Exam caveat: the same camera pipeline could later add generative captioning or an LLM triage agent; reassess when capabilities change. Also, classical CV still needs privacy, retention, and adversarial-example controls—declining GenAI-specific controls does not mean "no security."
Operational check: inventory model outputs (labels only versus generated language); map which GAIPS controls apply; keep separate standards for CV versus LLM apps; document why prompt-injection testing is out of scope if there is no free-text instruction channel; and revisit classification if staff later bolt on a generative explainer. Parks IT should avoid checklist theater that forces LLM controls onto non-generative systems.