
Why would a data scientist report the F1 score instead of just reporting precision and recall separately?
Select an answer to reveal the explanation.
Short Explanation
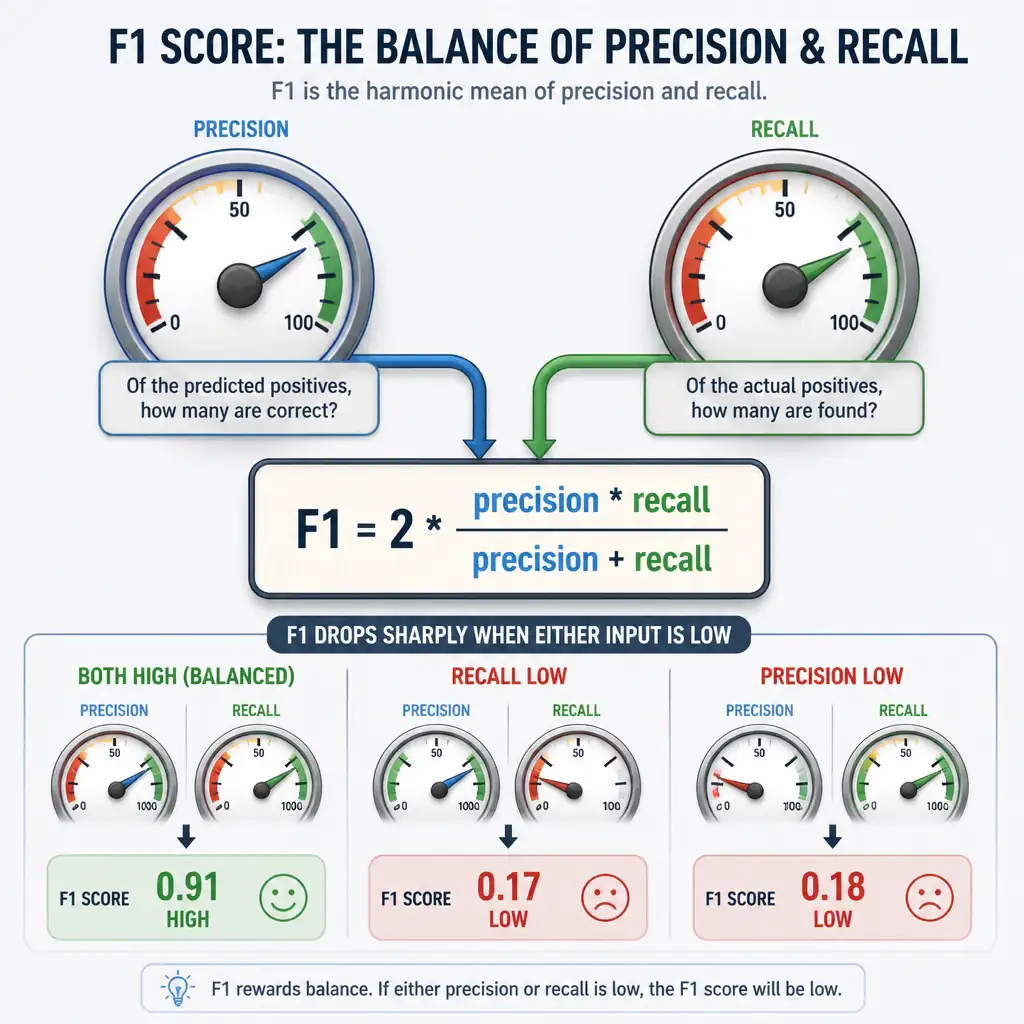
Sometimes you don't want to juggle two numbers and eyeball which model is 'better overall' when one has great precision and mediocre recall and another is the reverse. That's where F1 comes in — the harmonic mean of precision and recall, squeezed into one score. It's a harmonic mean, not a plain average, because harmonic means punish extreme imbalance harder: if either precision or recall is really low, F1 drops hard too, even if the other is sky-high. That keeps a model from gaming the score. That's the correct answer. It's not just multiplying the two together — wrong formula. It doesn't eliminate the confusion matrix — you still need those counts to compute precision and recall first. And it has nothing to do with training speed or epochs — that's a separate convergence concern.
Full Explanation
The F1 score is defined as the harmonic mean of precision and recall, calculated as 2 (precision recall) / (precision + recall). It exists to summarize both precision (how trustworthy positive predictions are) and recall (how completely actual positives are detected) into a single number, which is especially useful when comparing models or thresholds where one metric is high and the other is low, and a single interpretable score is needed to judge overall balance rather than examining two separate values side by side. The harmonic mean is deliberately used instead of a simple arithmetic average because it penalizes extreme disparities between the two values much more severely: if either precision or recall is very low, the harmonic mean pulls the overall F1 score down sharply, even if the other metric is close to perfect, whereas an arithmetic mean would be misleadingly inflated by the high value alone.
Claiming that F1 is simply precision multiplied by recall is incorrect because a raw product has no straightforward interpretation as a balanced score. Claiming that F1 replaces the need for a confusion matrix is incorrect because F1 is derived from those same confusion matrix counts. Confusing F1 with training convergence speed relative to epochs is incorrect because that is a training-efficiency concept separate from classification-quality metrics like F1.
A useful memory aid is that F1 is 'precision and recall's compromise score': it rewards models that do reasonably well on both fronts and heavily punishes models that sacrifice one to inflate the other. Variants such as F-beta scores generalize this idea further, letting practitioners weight recall or precision more heavily depending on which type of error (false positive or false negative) is more costly in a given application, such as medical screening favoring recall or spam filtering favoring precision.