
What is the primary objective the Adam optimizer is trying to achieve during training?
Select an answer to reveal the explanation.
Short Explanation
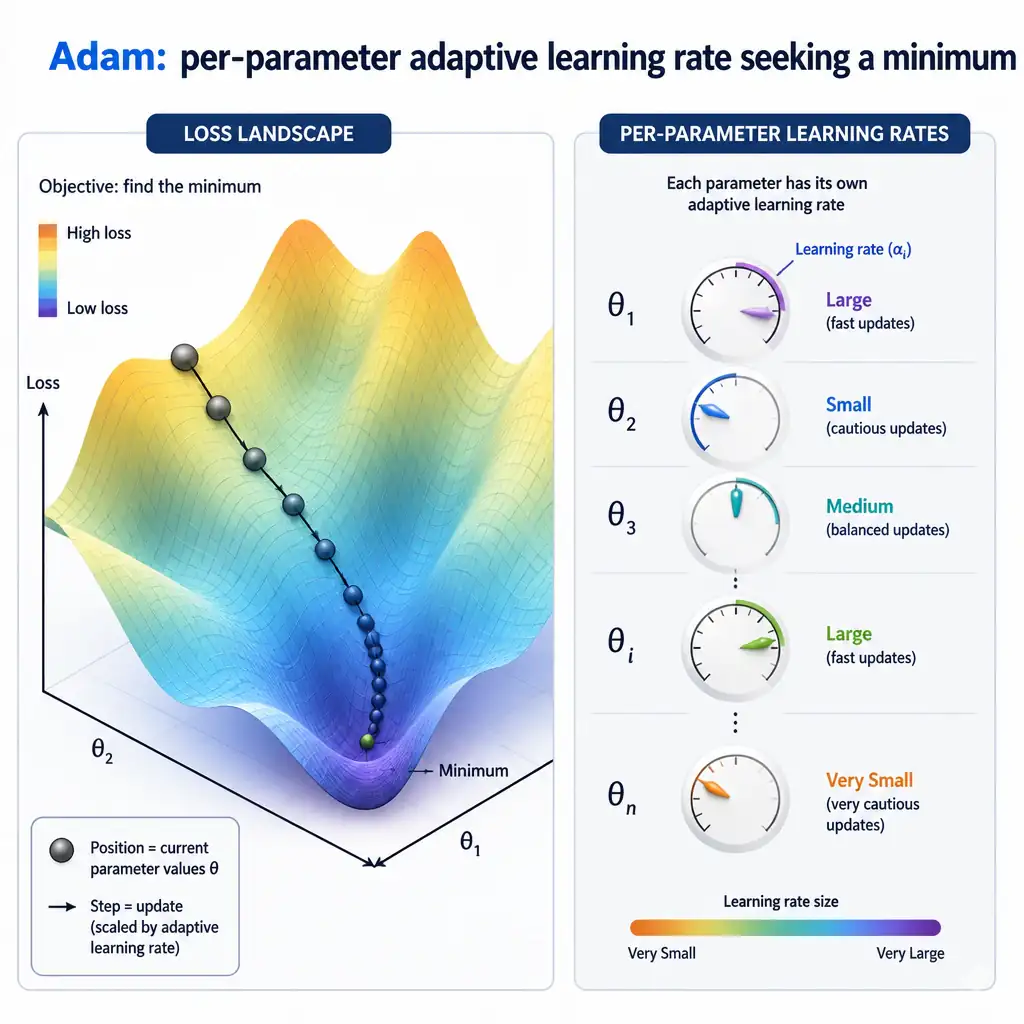
At its core, Adam has one job: help the network find a minimum of the loss function efficiently, by giving each parameter its own adaptive learning rate instead of forcing every weight to use the same step size. Some weights need bigger updates, others need to tread carefully, and Adam figures that out on the fly using running averages of gradients and squared gradients. That's the correct answer. It doesn't guarantee the global minimum — nothing in deep learning can promise that on non-convex loss landscapes, you can still get stuck in a local minimum or saddle point. It doesn't make validation sets obsolete either — you still need one to catch overfitting. And it's still a gradient-based method built on backpropagation, not a replacement for it.
Full Explanation
Adam's primary goal, like all gradient-based optimizers, is to iteratively adjust a model's weights to minimize a loss function. What distinguishes Adam is how it pursues that goal: rather than applying one single global learning rate uniformly to every parameter, Adam computes an adaptive, per-parameter learning rate by combining a decaying average of past gradients (for directional smoothing) with a decaying average of past squared gradients (for magnitude scaling). This lets parameters that have historically received large or noisy gradients take smaller, more cautious steps, while parameters that have received small or infrequent gradients take relatively larger steps, generally leading to faster and more stable convergence toward a minimum than plain SGD with a single fixed rate.
Claiming that Adam guarantees finding the global minimum is incorrect because no gradient descent variant can guarantee this on non-convex loss surfaces; Adam can still become stuck in local minima or saddle points. Claiming that Adam eliminates the need for a validation set by preventing overfitting is incorrect because Adam has no built-in mechanism to detect or prevent overfitting. Claiming that Adam replaces backpropagation with a gradient-free method is incorrect because Adam is a gradient-based method that computes updates directly from backpropagation gradients. The correct answer accurately describes Adam's actual mechanism: its per-parameter adaptive learning rate is exactly the tool it uses to pursue efficient minimization of the loss function.
A good mental model is that Adam's mission is 'efficient descent with per-parameter common sense': instead of treating every weight identically, it tailors the step size to that weight's own gradient history, which is precisely why it has become a default choice for training deep networks across many domains, from computer vision to NLP.