
What is the main advantage of mini-batch gradient descent over full batch gradient descent when training on a large dataset?
Select an answer to reveal the explanation.
Short Explanation
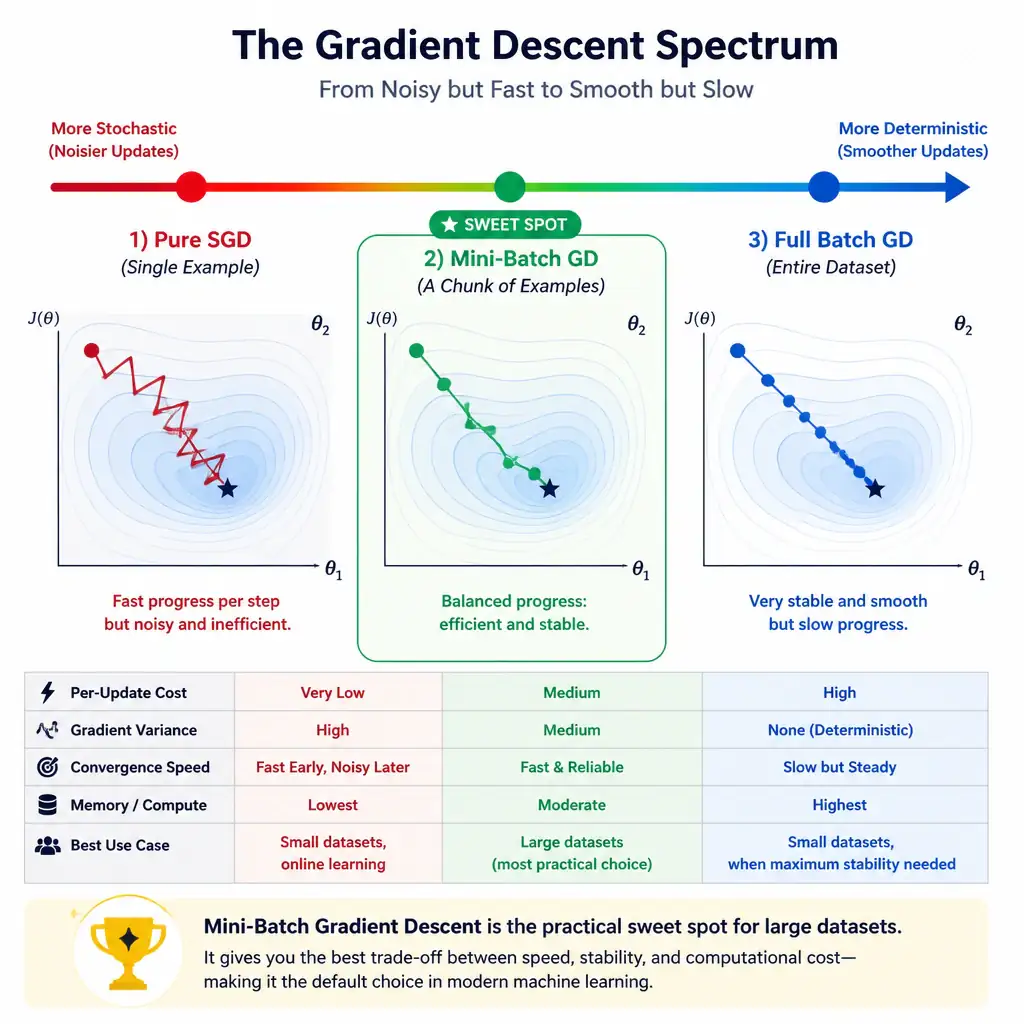
Think of mini-batch as the sensible middle ground. Full batch gradient descent gives you a rock-solid, stable gradient estimate, but you have to crawl through the whole dataset just to take one step. Pure SGD (one example at a time) is fast and cheap per step, but wildly noisy. Mini-batch splits the difference: process a chunk of, say, 64 or 128 examples, get a reasonably stable gradient, and update way more often than full batch would let you. That's the correct answer — efficient on big data, balancing SGD's speed with batch's stability. It doesn't guarantee the global minimum, nobody does with non-convex neural network loss surfaces. It doesn't get rid of the learning rate — you still need one, in fact schedulers still tune it constantly. And you still absolutely want to shuffle your data between epochs to avoid learning spurious order effects.
Full Explanation
Mini-batch gradient descent divides the training set into small batches (commonly 32, 64, 128, or 256 samples) and updates the model's weights after processing each batch rather than after a single example (as in pure stochastic gradient descent) or the entire dataset (as in batch gradient descent). This gives two compounding benefits on large datasets: first, computing the gradient over a batch of examples produces a noticeably more stable estimate than a single-example gradient, smoothing out the erratic update path typical of pure SGD; second, because updates happen far more frequently than full-batch training, the model makes meaningful progress without waiting to traverse the whole dataset, and batches can be vectorized efficiently on GPU hardware.
The claim that mini-batch guarantees convergence to the global minimum is incorrect because no gradient-descent variant guarantees this on non-convex loss surfaces; all variants can settle into local minima or saddle points, and mini-batch is no exception. The claim that mini-batch eliminates the need for a learning rate is incorrect because mini-batch still requires a learning rate to scale each weight update — if anything, tuning the learning rate matters just as much with mini-batches as with any other variant. The claim that mini-batch removes the need to shuffle the training data is incorrect because shuffling before each epoch remains a best practice; without shuffling, batches would repeatedly contain the same groupings in the same order, which can introduce bias and hurt generalization.
In practice, mini-batch gradient descent (usually just called "SGD" in deep learning frameworks, even though it processes batches rather than single examples) is the default training strategy across nearly all modern deep learning because it delivers the best practical tradeoff between computational efficiency, memory usage, and gradient stability.