
A readiness reviewer checks the charter-desk assistant before its go-live date and finds the Model Serving endpoint is created and healthy, but queries return no retrieved clauses at all, even for questions that clearly match content in the source table. What is the most likely gap in the deployment, given that the chain code is unchanged from a working notebook test?
Select an answer to reveal the explanation.
Short Explanation
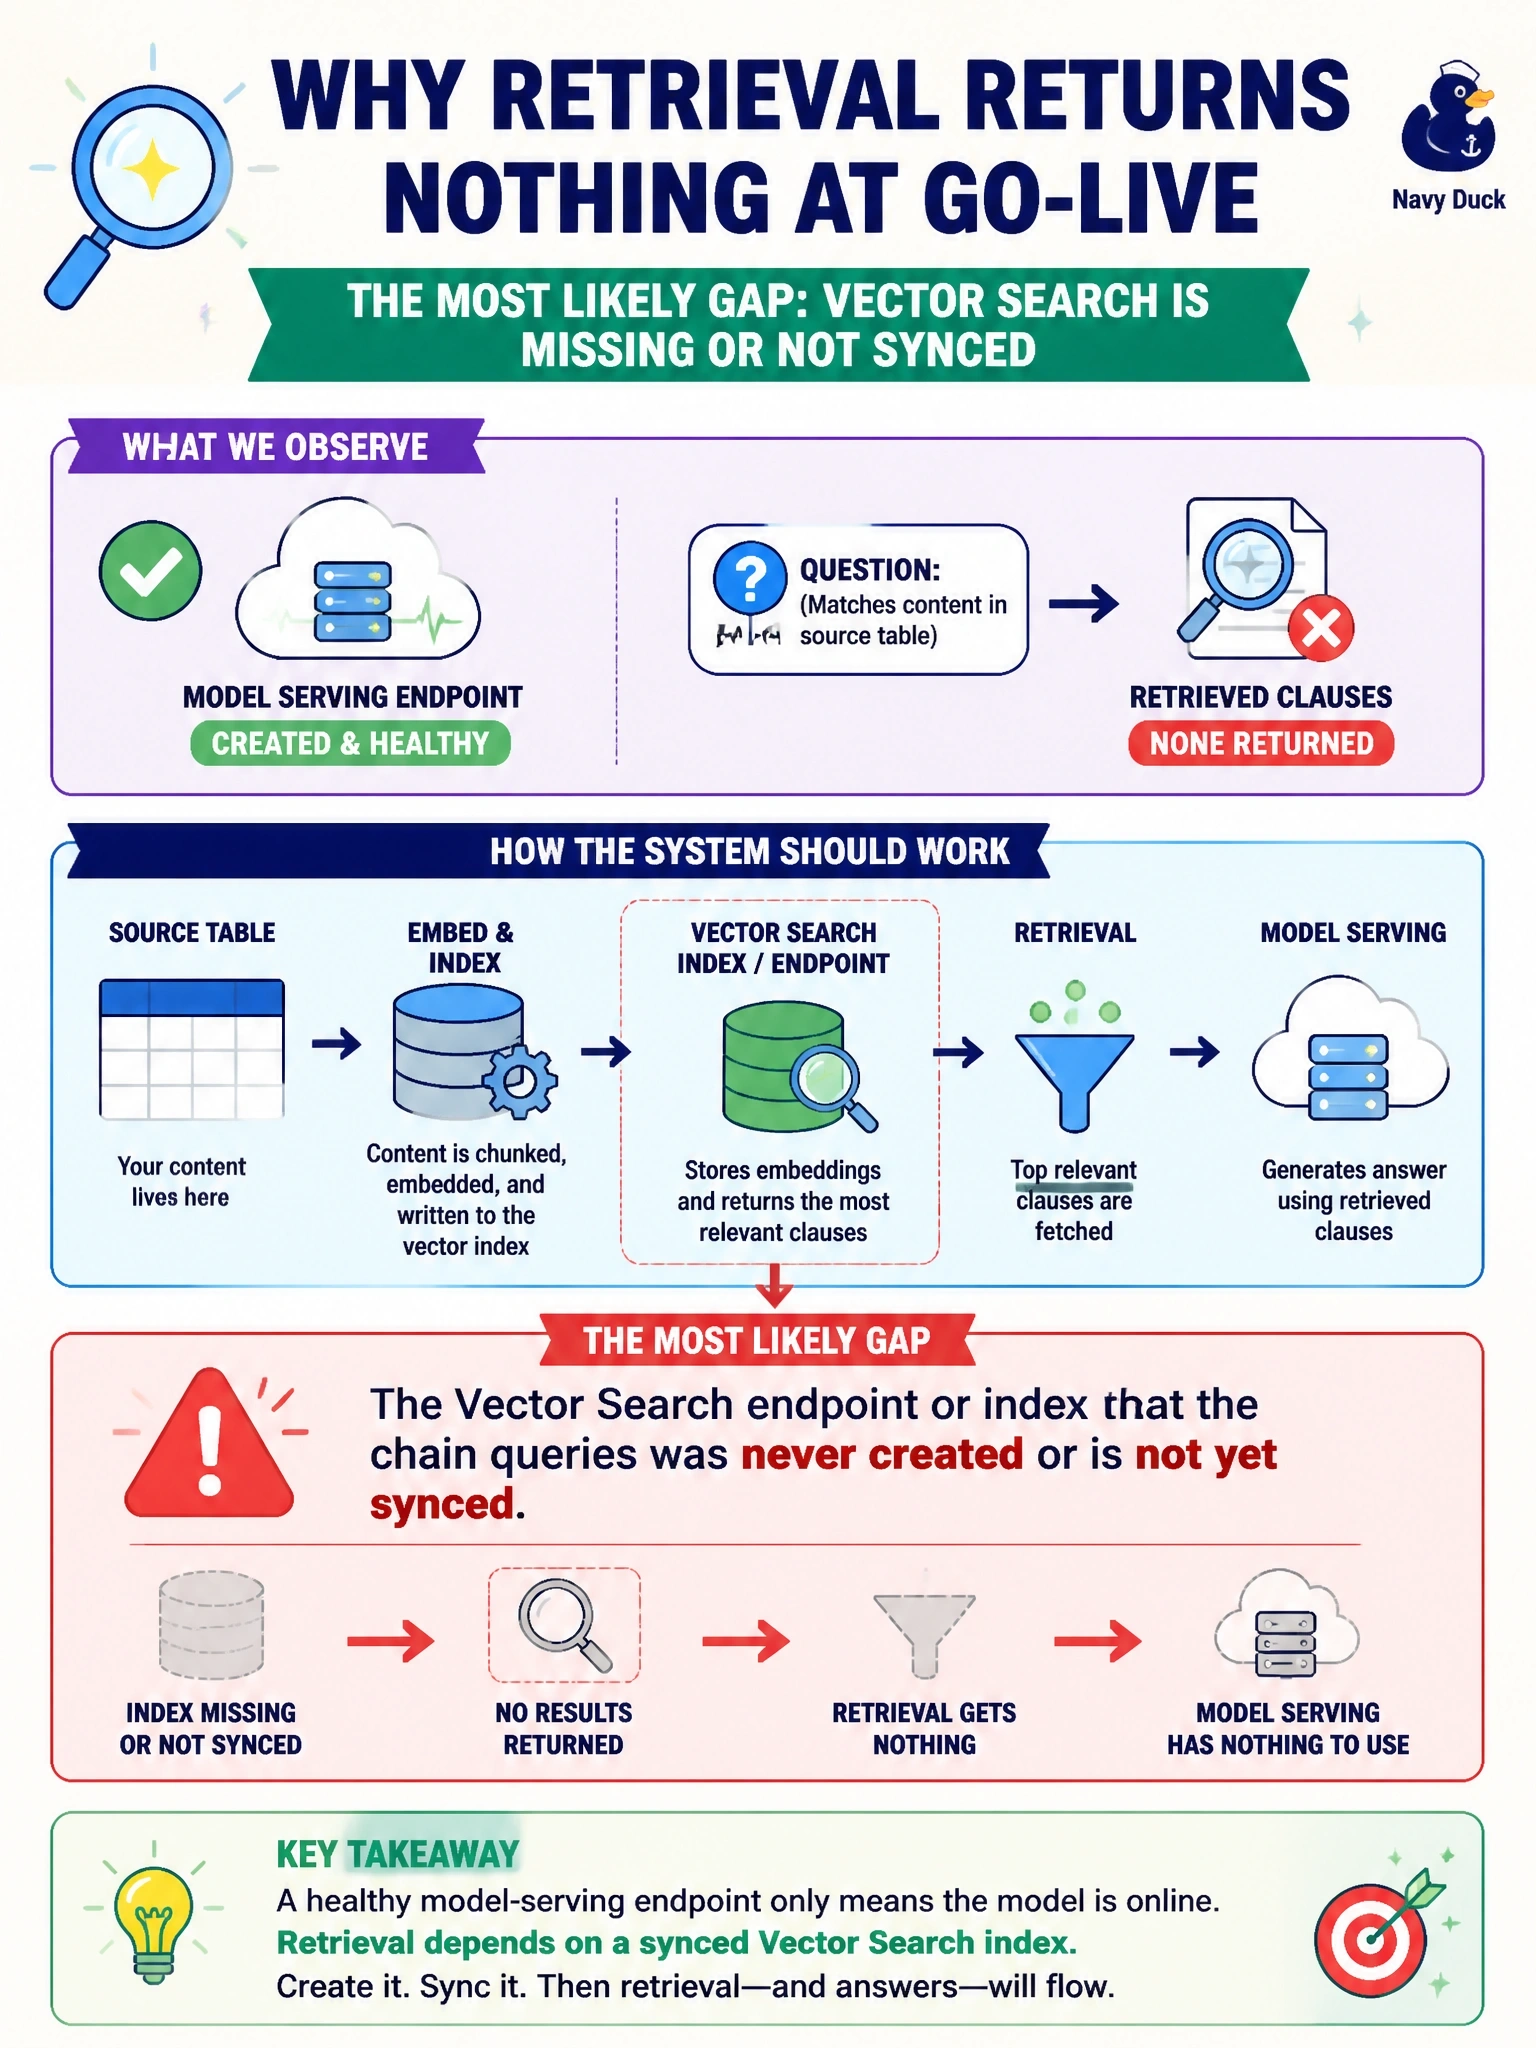
A healthy Model Serving endpoint just means the chain is running — it says nothing about whether the retrieval half of the pipeline was ever stood up. Empty results from clearly matching content point straight at a missing or unsynced Vector Search endpoint or index, not at anything wrong with the model layer.
Full Explanation
A RAG chain has two independently deployed pieces: the Model Serving endpoint that runs the chain, and the Vector Search endpoint and index the chain queries for retrieval. A healthy Model Serving endpoint only confirms the chain code is loaded and executing; it says nothing about whether the separate Vector Search infrastructure exists or has finished syncing. Empty retrieval results despite content that clearly should match are the classic symptom of the Vector Search endpoint or index not having been created yet in this environment, or a Delta Sync index that has not completed its initial sync, which is exactly the kind of gap that a notebook test (often run against a fully synced dev-environment index) would not surface. A misconfigured scale-to-zero setting would affect cold-start latency or endpoint availability, not cause a healthy, responding endpoint to silently return zero retrieved documents. A missing output field in the MLflow signature would typically cause a validation error at serving time, not a clean-looking response with an empty retrieval result. An overly low AI Gateway rate limit would produce throttling errors or rejected requests, not successful responses with no retrieved content. For the exam, remember that end-to-end readiness for a RAG application requires verifying both the model-serving layer and the Vector Search layer independently — one being healthy does not imply the other is.