
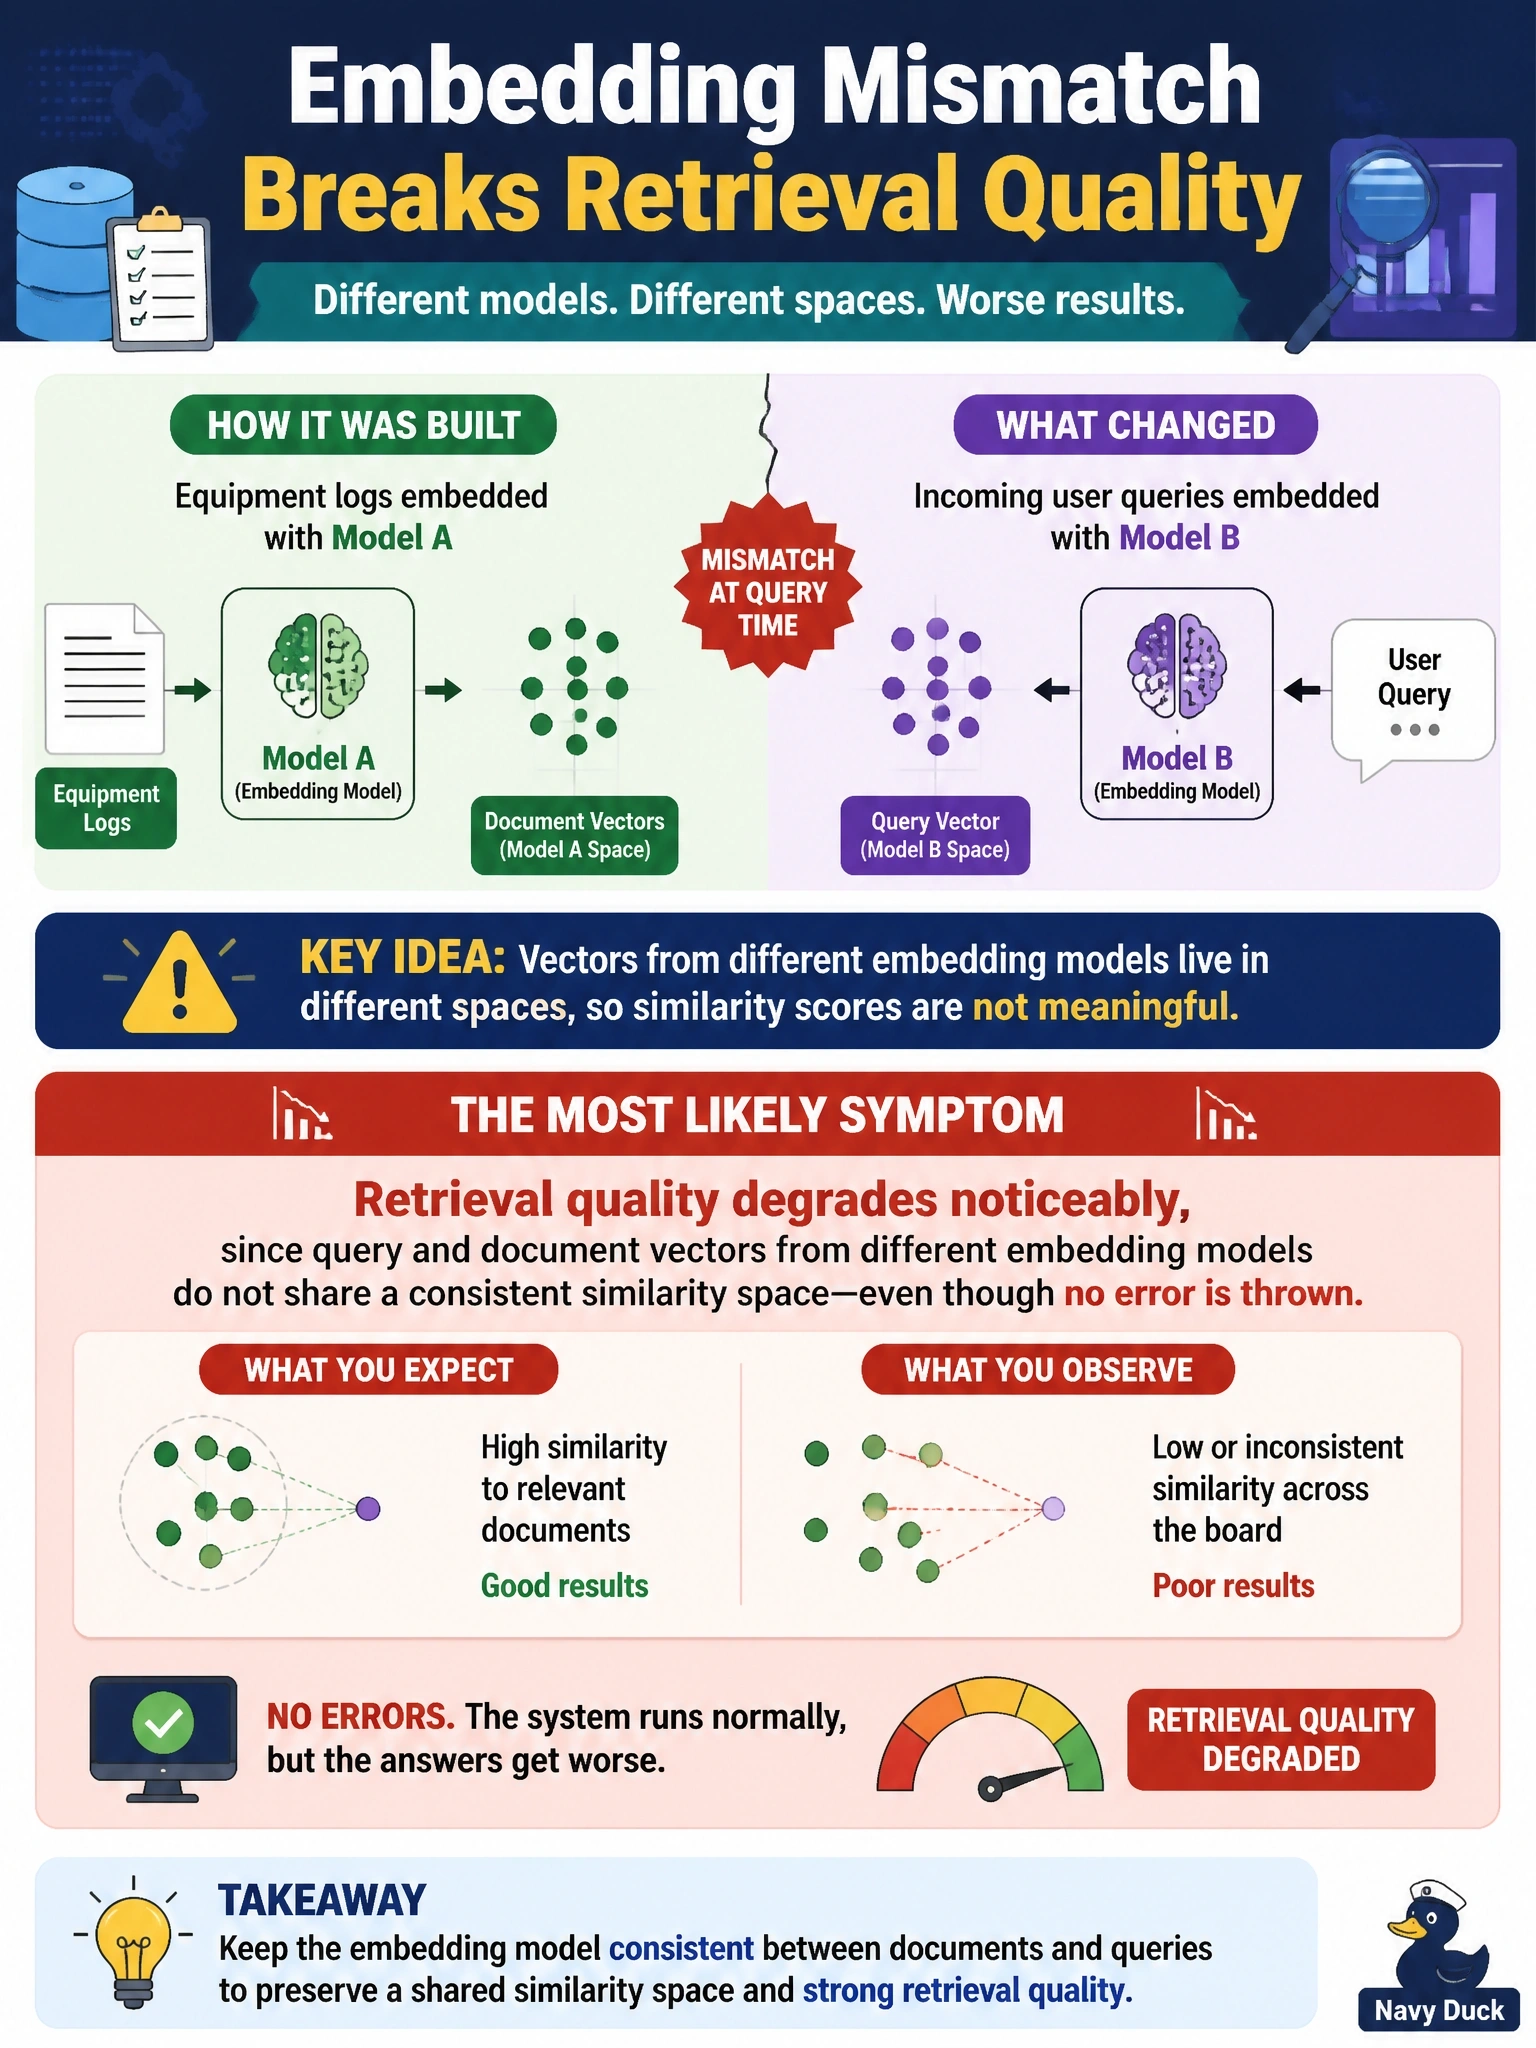
Meridian Line's maintenance-triage index was built by embedding equipment logs with Model A, but a recent code change accidentally embeds incoming user queries with Model B at query time. What is the most likely observable symptom?
Select an answer to reveal the explanation.
Short Explanation
This is the sneaky failure mode -- nothing crashes, nothing errors, retrieval just quietly gets worse because you're comparing apples described in two different languages. Query and index embeddings have to come from the same model, and this is why 'no error' doesn't mean 'working correctly.'
Full Explanation
Consistent embedding-model use across index construction and query time is a basic correctness requirement of vector search: similarity search assumes query and document vectors live in the same learned space, and using different models on each side produces a vector-space mismatch that degrades retrieval quality without necessarily throwing any error, since the similarity computation still runs, it just returns less meaningful rankings -- this is a silent-degradation failure mode rather than a hard failure, which is what makes it dangerous in production. There is no automatic mechanism that overrides an application's chosen query-time embedding model to match whatever built the index; the application is responsible for using the same model consistently, and assuming the platform silently corrects a mismatch is incorrect. Similarly there is no built-in validation that rejects a query for using the 'wrong' embedding model with a clear error -- the system has no way to know the application intended to use a different model than the one that built the index. Framing the mismatch as beneficial diversity misunderstands what similarity search measures; it does not average two models' judgments, it computes distance in one presumed shared space, and using inconsistent models corrupts that measurement rather than enriching it. Exam framing: choosing an embedding model and understanding the consequences of that choice -- including keeping query-time and index-time embedding consistent -- is a named Data Preparation objective with direct Application Development consequences.