
A museum audio-guide tester runs one prompt, likes the tone, and wants to freeze it without comparison or further review. What should happen instead?
Select an answer to reveal the explanation.
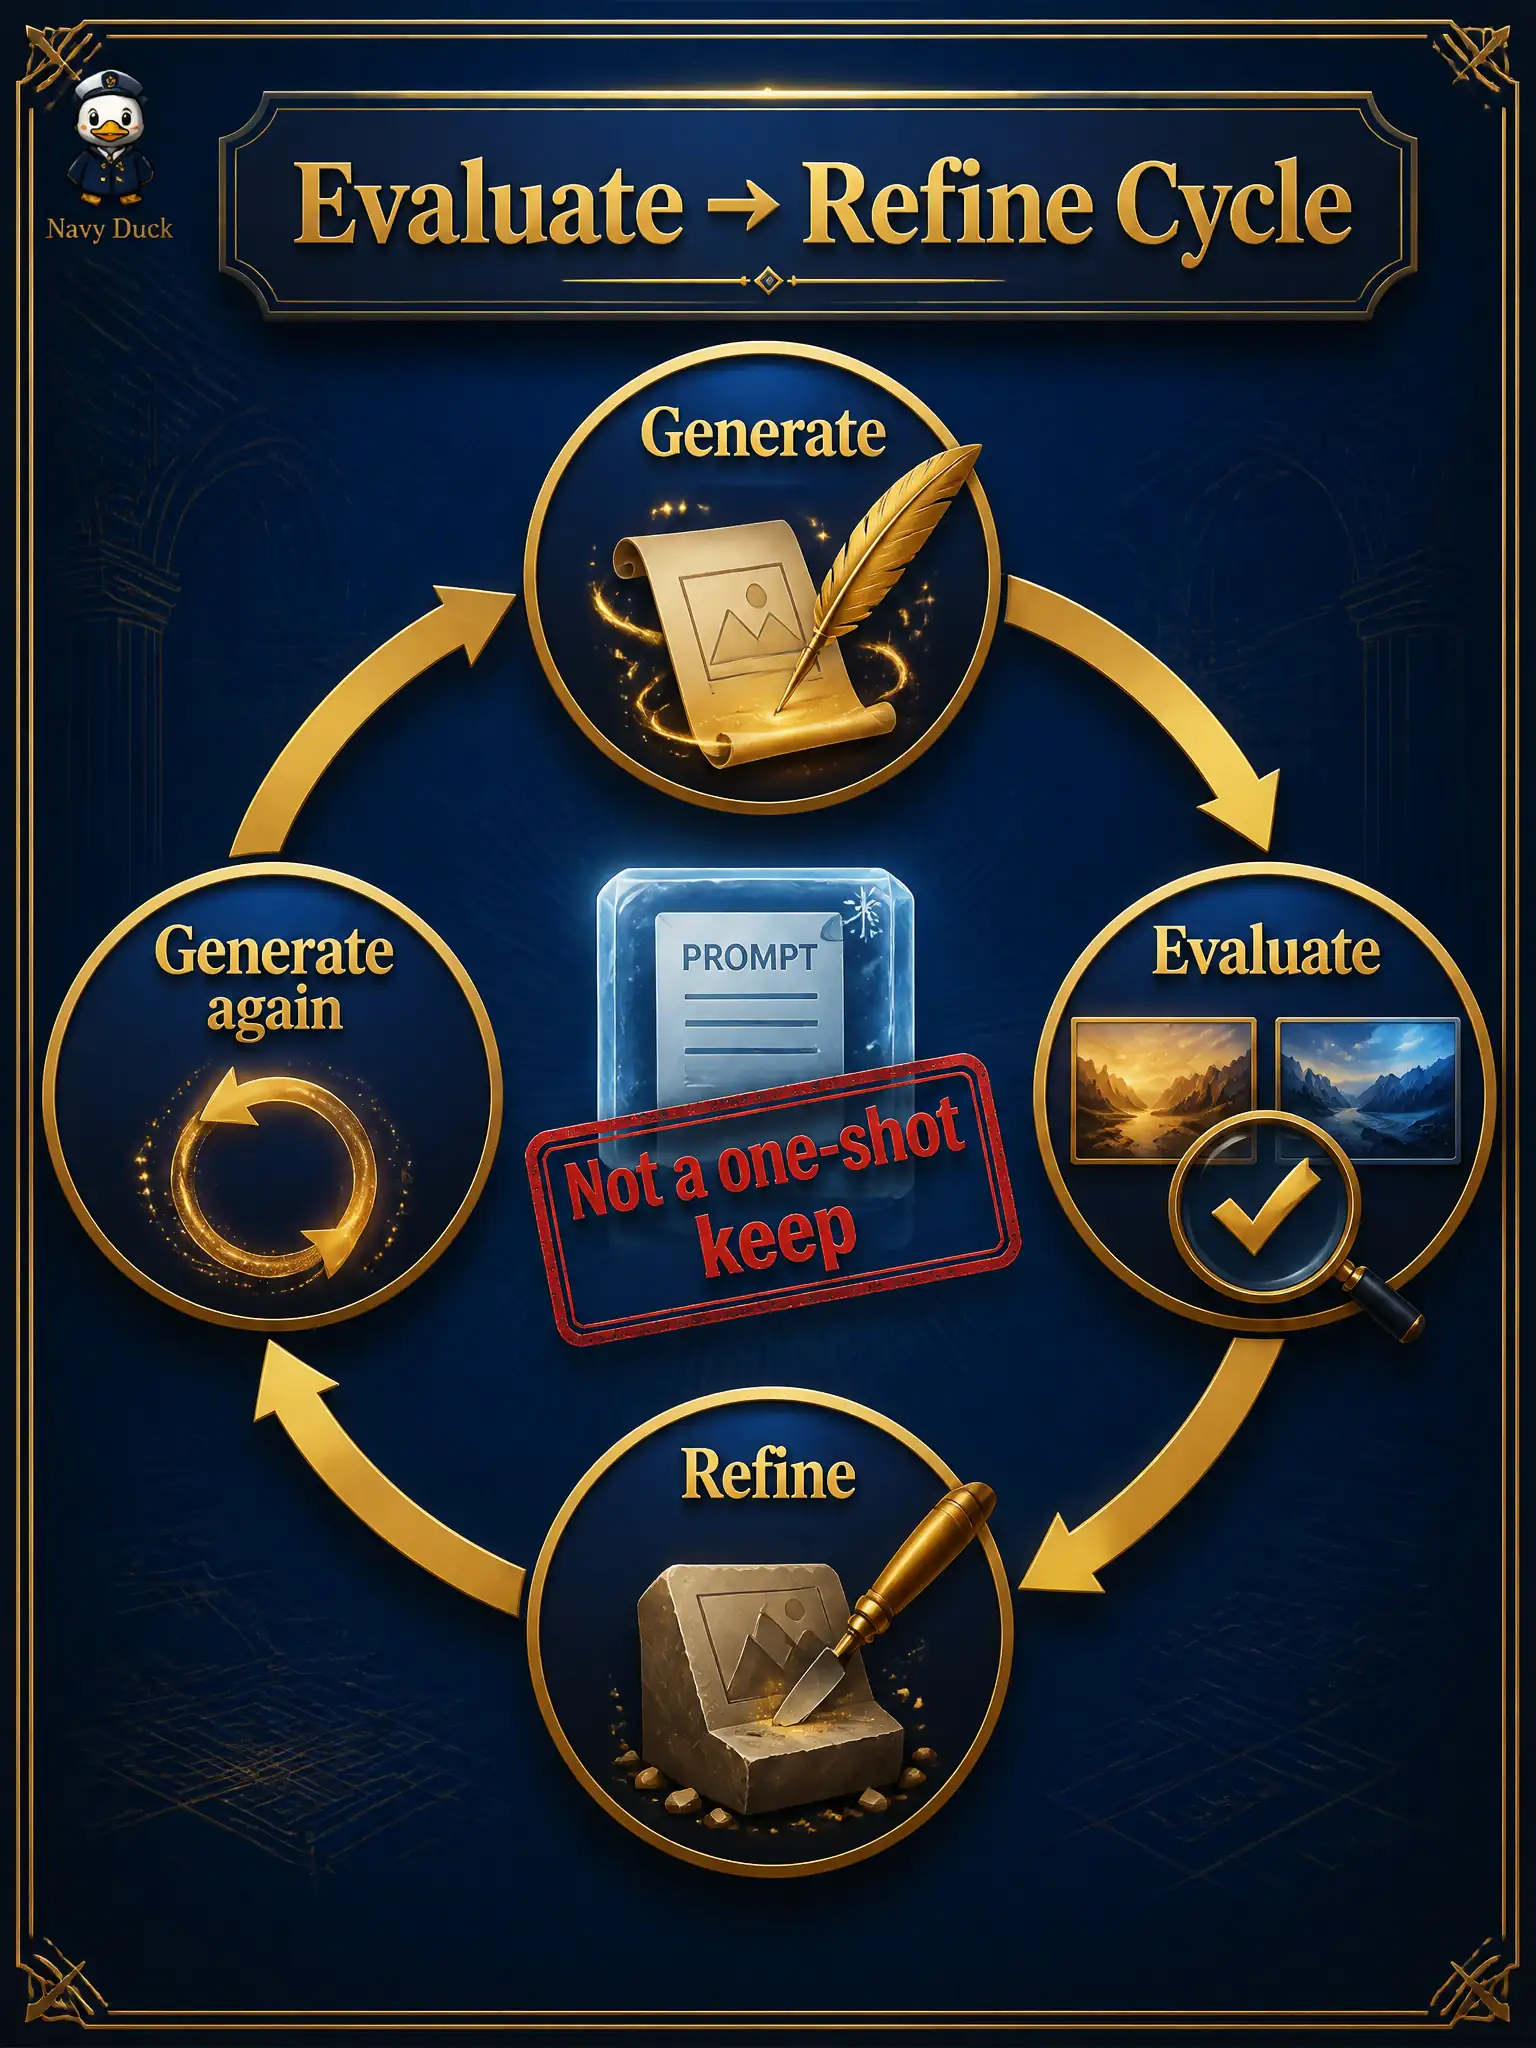
Short Explanation
One nice-sounding run isn’t a finish line. Evaluate, compare, verify with humans, then refine—don’t freeze on vibes alone.
Full Explanation
A museum audio-guide tester who runs one prompt, likes the tone, and wants to freeze it without comparison or further review should instead follow an evaluate-then-refine cycle—using A/B comparison and/or human verification across iterations—rather than a single unmeasured keep. Civic guest experiences deserve evidenced prompts, not vibe locks. Freezing immediately because a friendly tone is sufficient proof fails as style-over-substance. Replacing evaluation with neuron coverage of an audio-guide recommendation model fails by concept relative to prompt evaluation. Publishing the unreviewed prompt as the only library entry forever fails team learning and quality control. Exam caveat: evaluation and refinement are cyclical; tone alone is not a release criterion. Operational check: A/B the liked prompt against an alternative on predefined civic metrics, require a second tester’s verification, log results, and only then promote a version into the museum prompt library. Retain the municipal audit note so later testers can see why the decision protects public service quality and fairness. Retain the municipal audit note so later testers can see why the decision protects public service quality and fairness.