
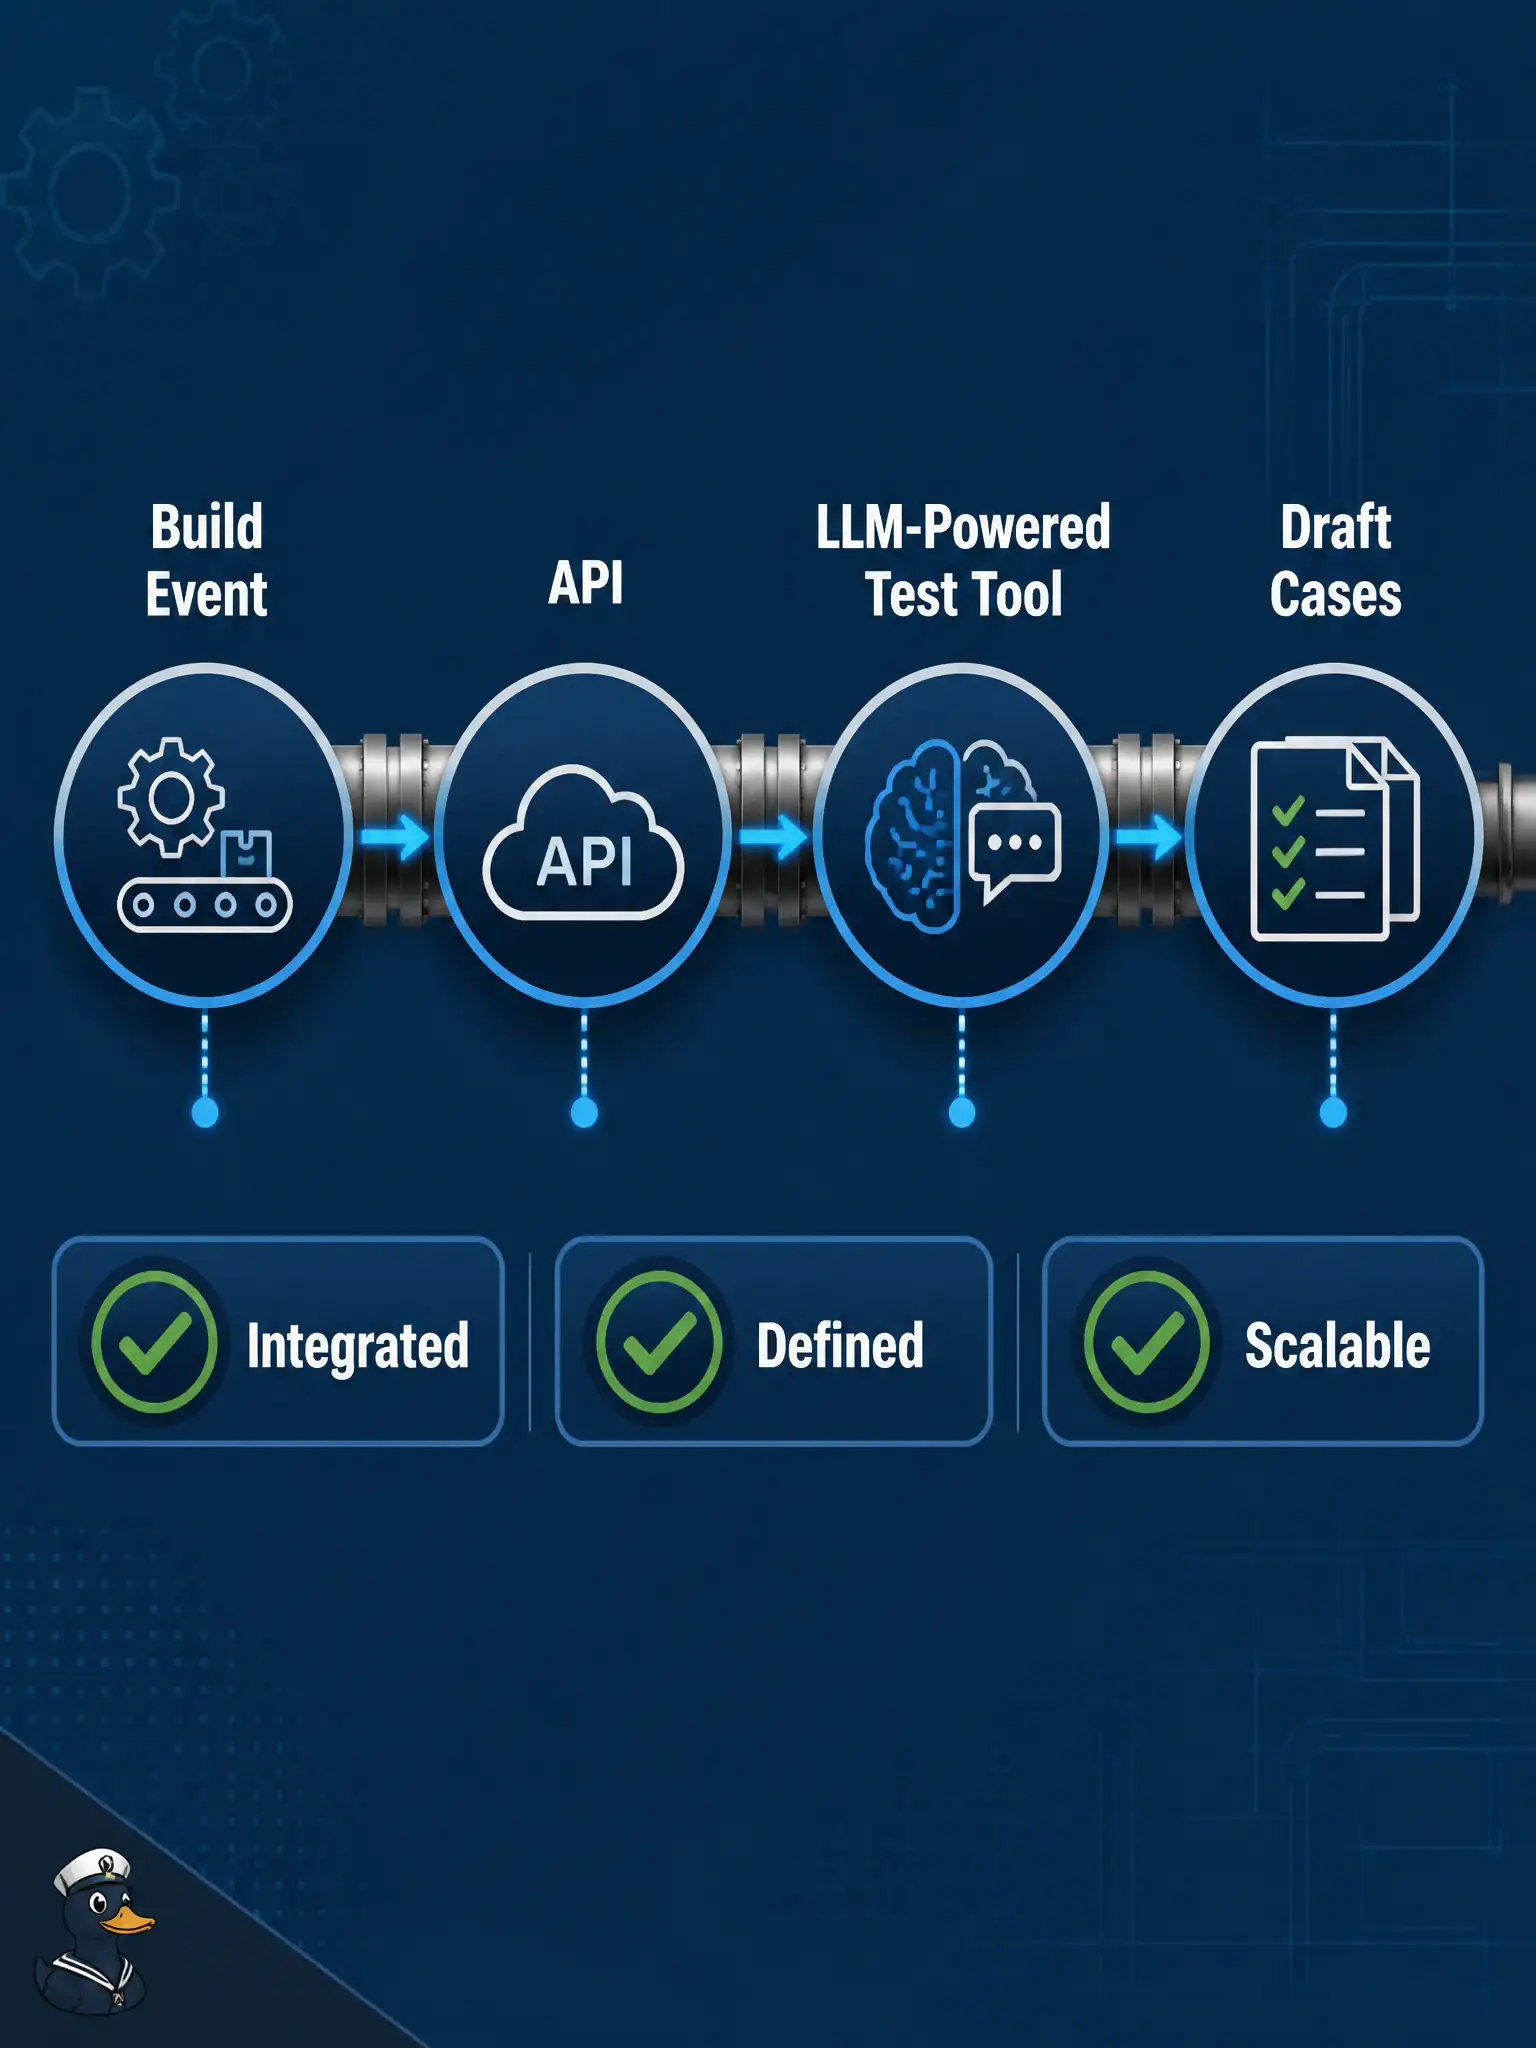
A water-meter suite auto-drafts cases on every build through an API hooked to the test tool; nobody is chatting. Which interaction model is this?
Select an answer to reveal the explanation.
Short Explanation
When cases appear after every build through an API and no one is typing in a chat box, you are looking at an LLM-powered testing application. It is integrated and job-shaped—built for repeatable scale. Chatbots flex; this path runs the defined task.
Full Explanation
An LLM-powered testing application embeds model calls into tools and pipelines for a well-defined, often automated task—matching a water-meter suite that auto-drafts cases on every build through an API hooked to the test tool with nobody chatting. Civic utilities need repeatable job-shaped GenAI for regression after each meter firmware, tariff, or billing build—not hallway conversation for every commit.
A chatbot optimized for ad-hoc coaching and free-form follow-up questions mismatches the silent API path and does not scale the same way for every build. A CT-AI neuron-coverage harness that treats the LLM as the system under test is the wrong certification focus for interaction-model selection. A manual spreadsheet export with no model involvement at all denies that a model is producing the drafted cases.
Exam caveat: absence of chat + API/tool integration + defined repeatable task = testing-application interaction model on CT-GenAI.
Operational check: confirm case drafts appear from the build hook without a chat session; version prompts inside the tool configuration; review sampled drafts each release; document the application-model choice in the water-meter municipal regression runbook and change ticket.