
A radio-pledge tester has a well-written user story and no UI yet. A colleague insists they must attach a mock screenshot before any LLM help. What is the soundest response?
Select an answer to reveal the explanation.
Short Explanation
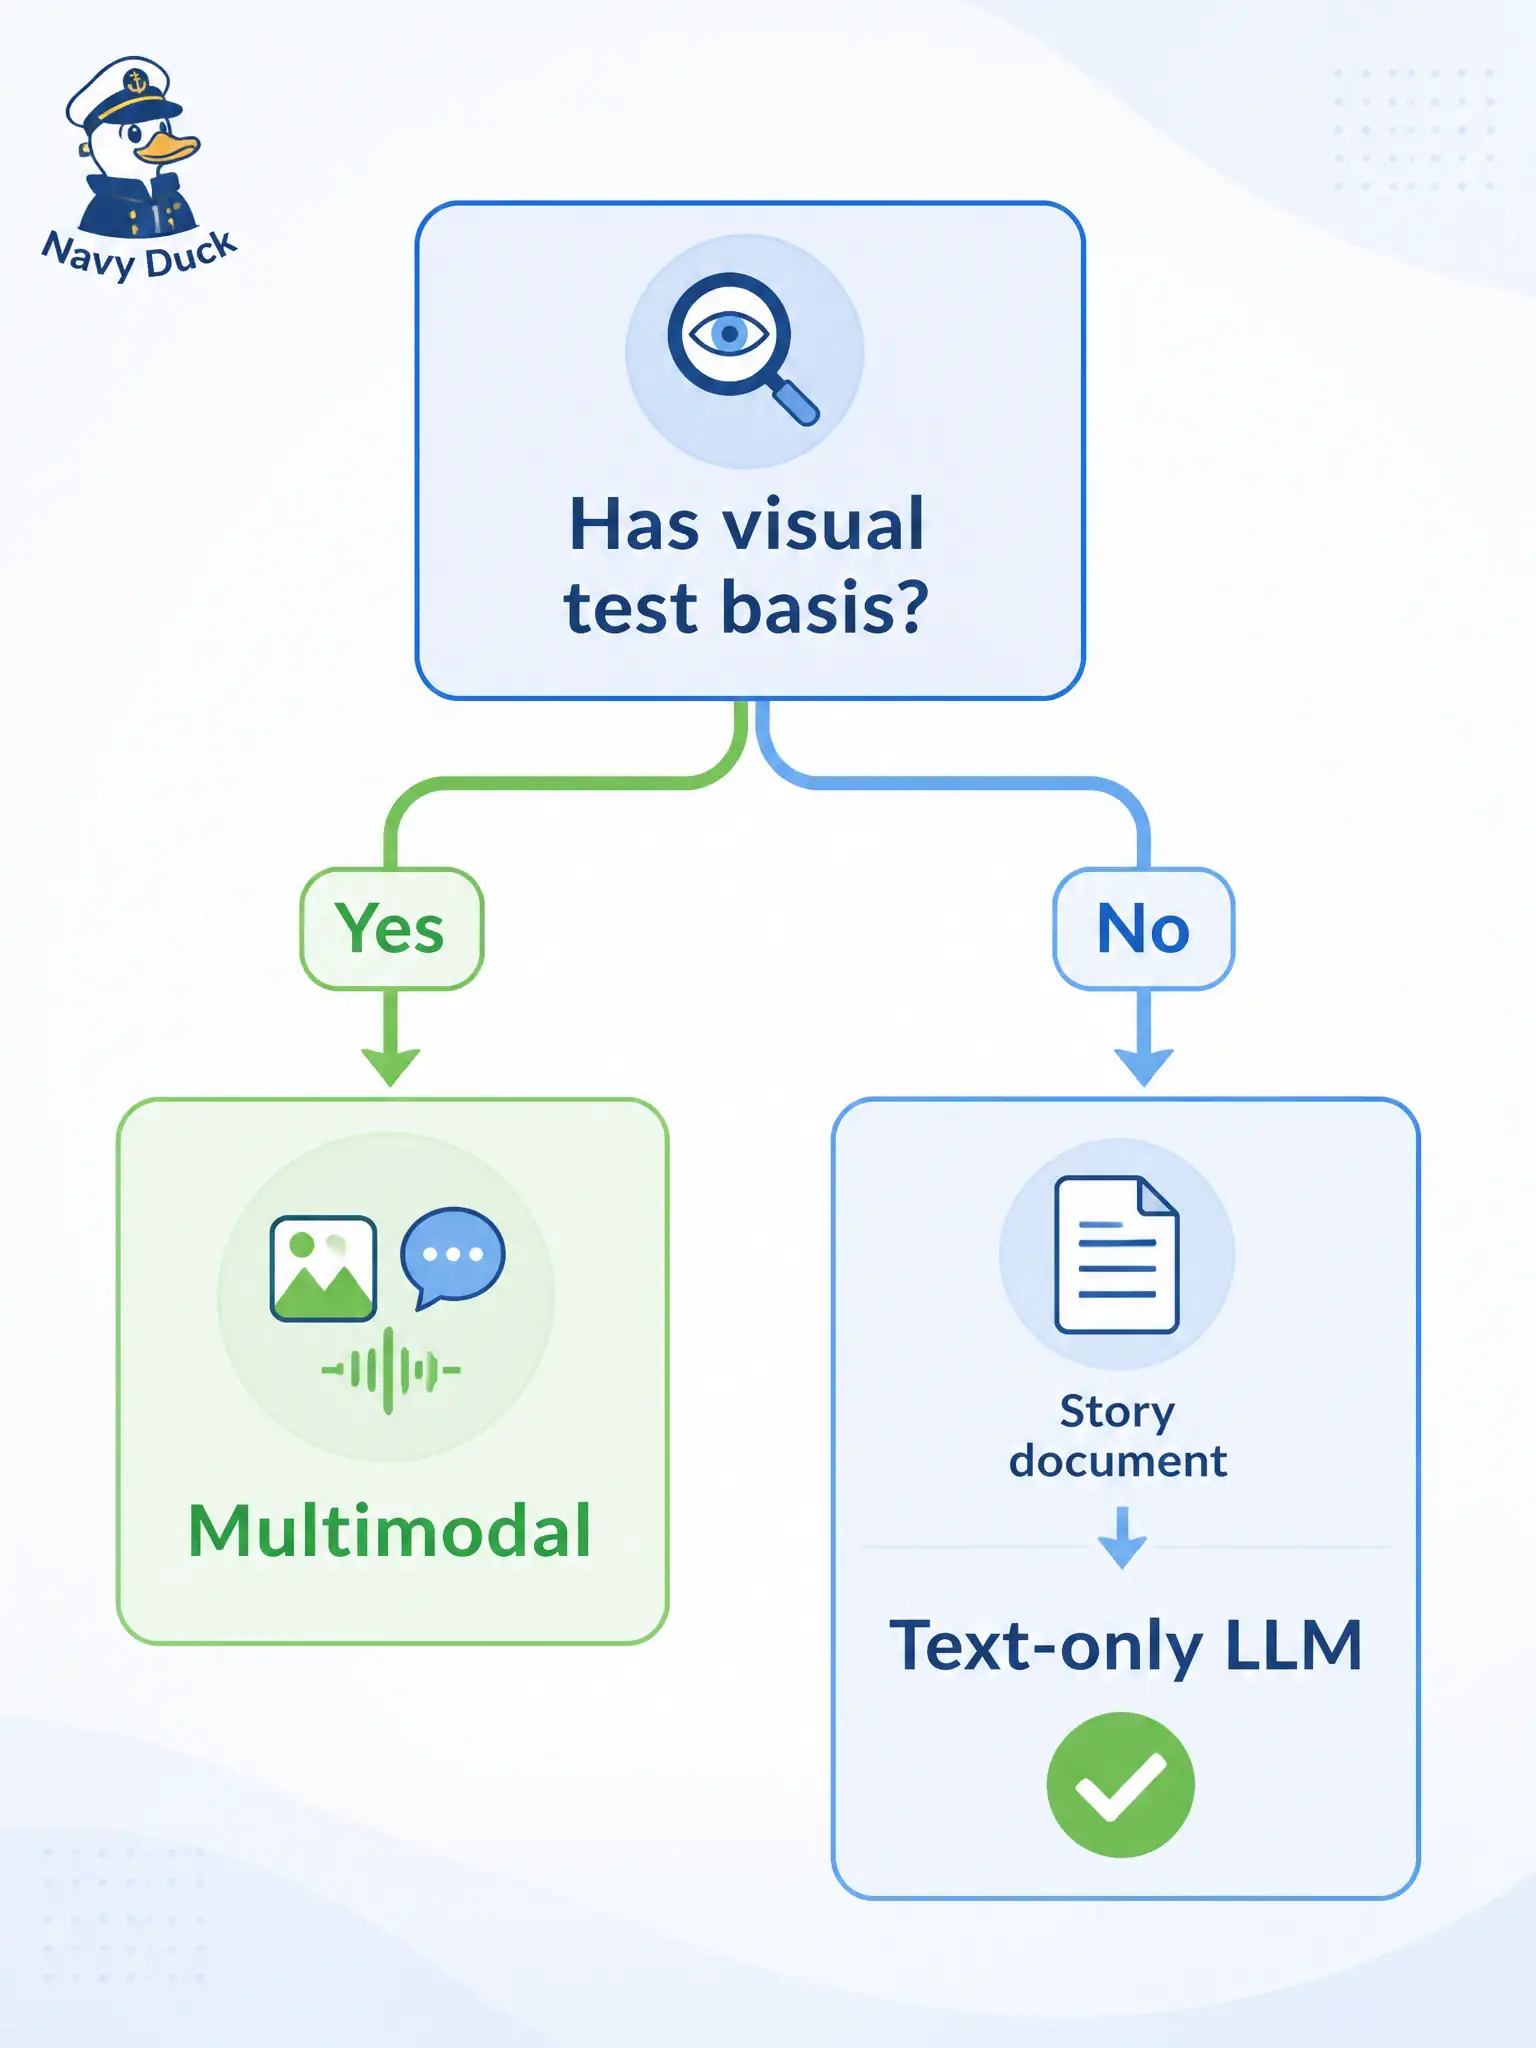
Multimodal is a tool for when pictures matter—not a tax you pay on every prompt. With a solid story and no screen to compare, a text-only model is the honest fit. Forcing a fake screenshot adds noise without a real visual test basis.
Full Explanation
When a radio-pledge tester has a well-written user story and no UI yet, keep a text-only LLM; an image attachment is unnecessary. Multimodal models help when visual artefacts are part of the test basis. Forcing a mock screenshot when none exists adds noise without a real visual comparison target for civic pledge stories and wastes facilitator time.
Always requiring multimodal input even when the only basis is prose turns modality into a tax rather than a fit decision. Refusing all GenAI until neuron coverage of a blank canvas mock is measured imports model-as-SUT gates from another syllabus. Converting the story into a red-team jailbreak payload instead of drafting cases abandons requirements support for attack play that does not advance pledge testware.
Exam caveat: choose modality from the basis you actually have. Text-only stories → text-only aids; wireframes or screenshots → multimodal. Multimodal is not mandatory theater.
Operational check: draft pledge cases from the story with a text LLM; defer multimodal prompts until a real mock or build screenshot exists; document the modality-fit rule in the community-radio municipal test guide so colleagues stop insisting on fake images.