
Where in a Deployment manifest should a developer place container CPU and memory requests so every replica inherits them?
Select an answer to reveal the explanation.
Short Explanation
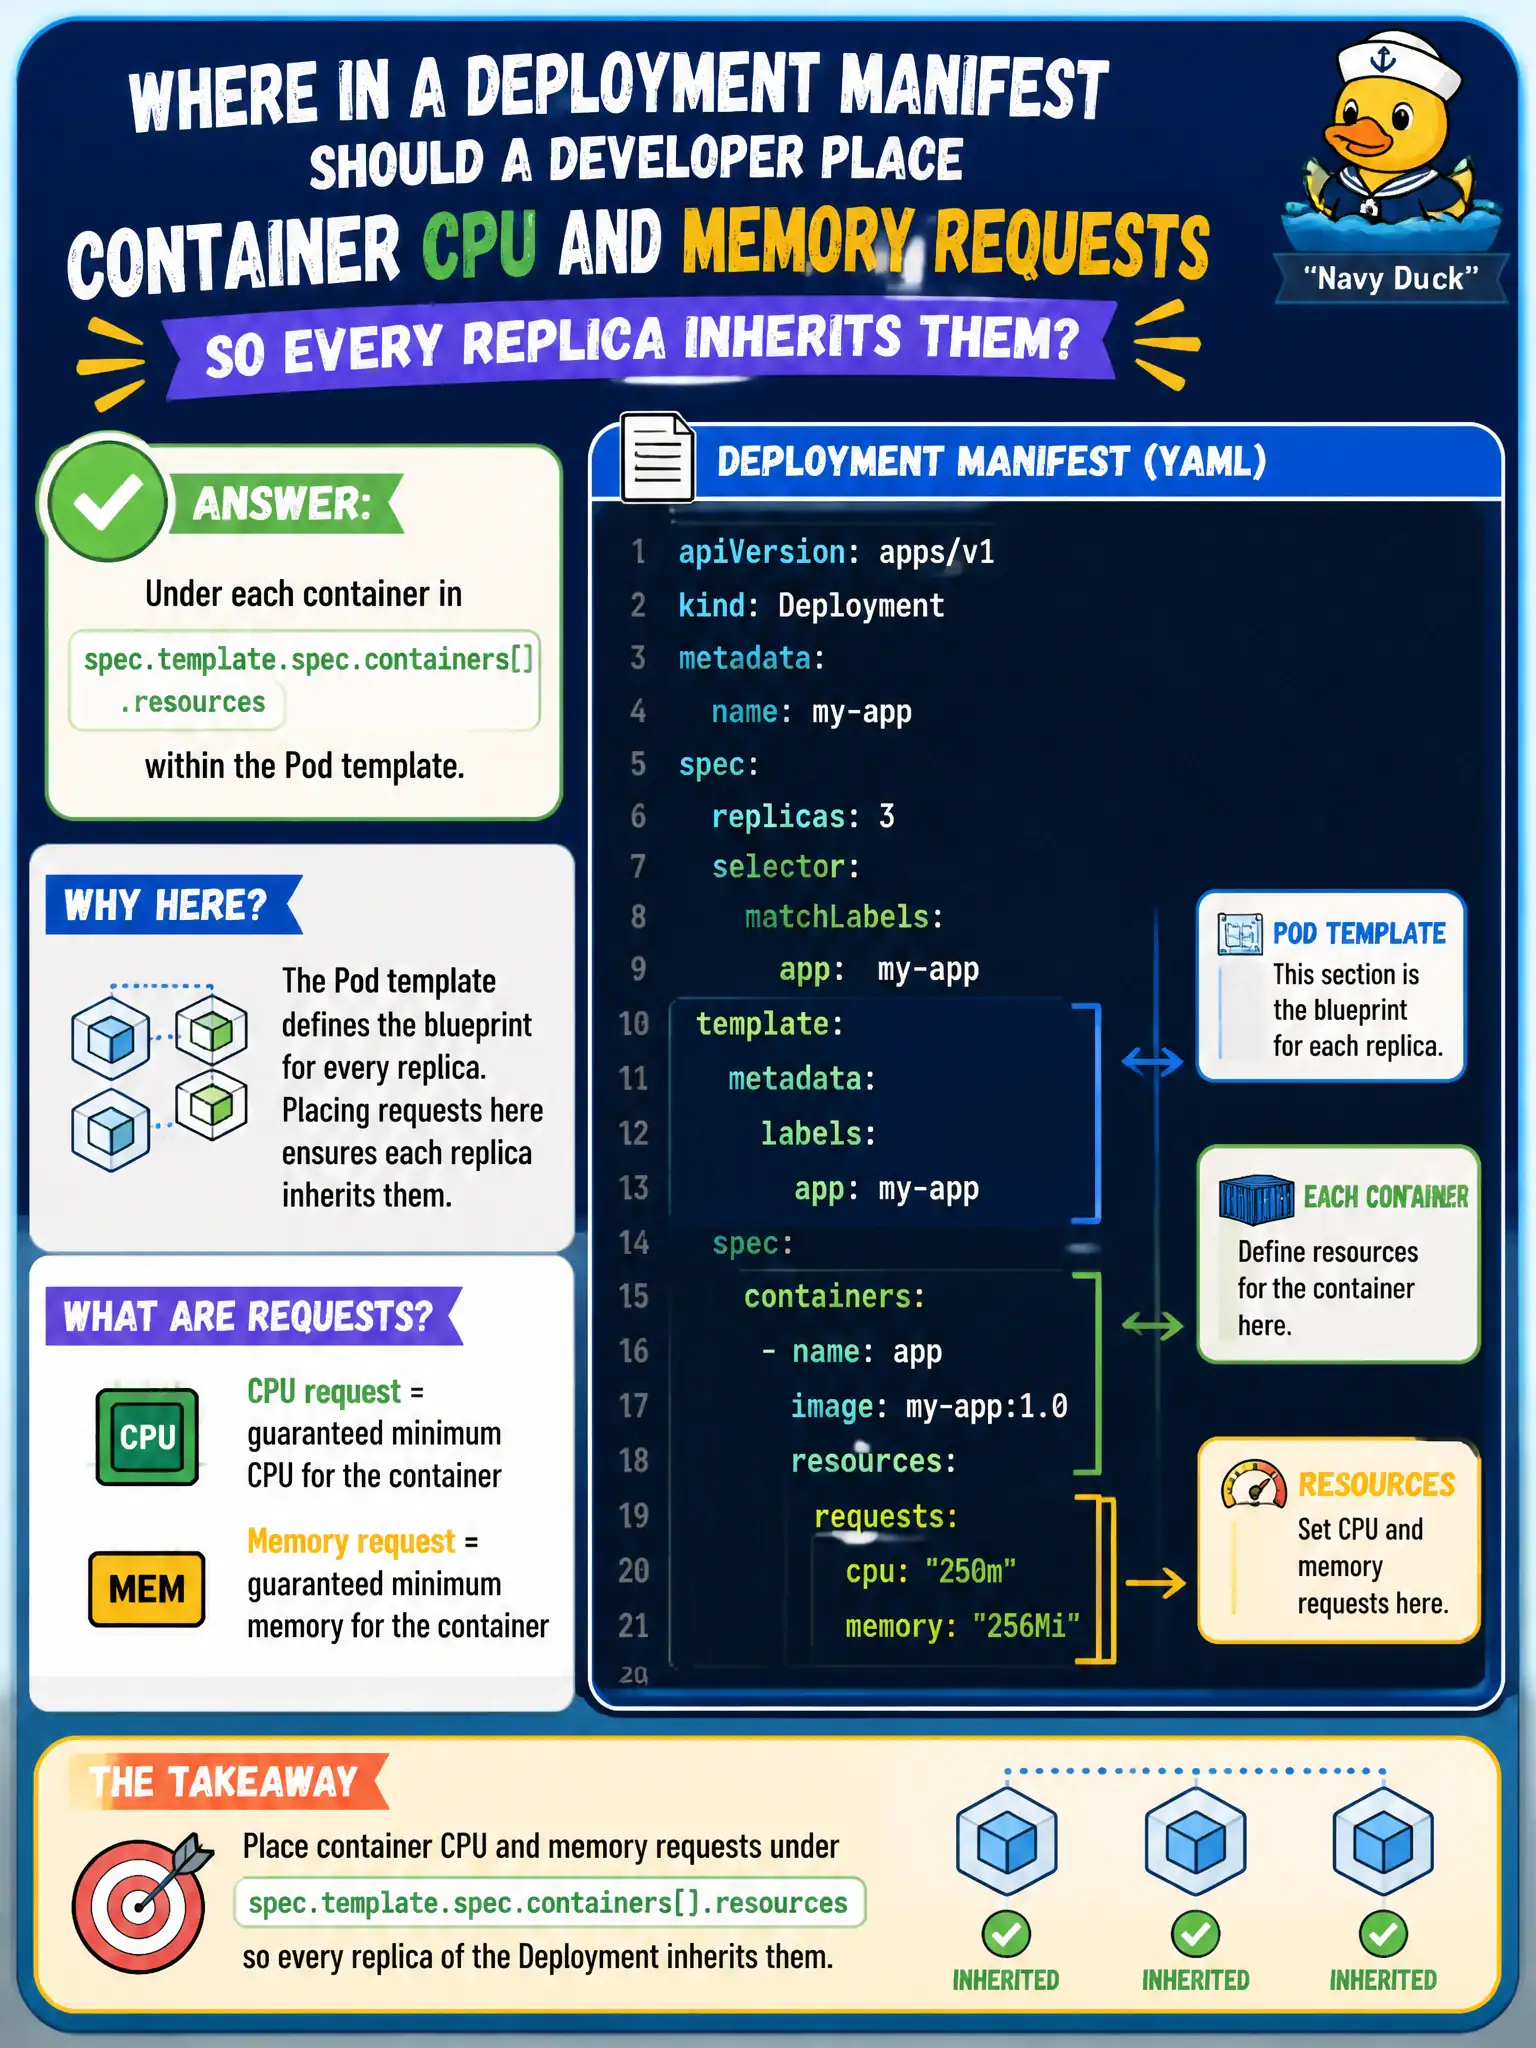
Replicas clone the Pod template like cookie-cutter dough—resources belong in that mold. Put requests under each container inside spec.template.spec. Strategy blocks and labels don't feed the scheduler's reservation math.
Full Explanation
Container CPU and memory requests that every Deployment replica should inherit belong under each container in spec.template.spec.containers[].resources within the Pod template. The Deployment controller creates Pods from that template, so resources defined there apply consistently to each municipal API replica.
Placing them under spec.strategy.rollingUpdate as scheduler hints for each surge Pod fails—rollingUpdate configures max surge and unavailable behavior, not container compute resources. Defining them only in a LimitRange while insisting the Deployment must not duplicate any resource fields misunderstands LimitRange as defaults and constraints rather than a replacement for intentional template resources. Putting resources under metadata.labels using keys shaped like resources.cpu fails because labels are not the scheduler's resource model.
Exam caveat: changing template resources triggers a rolling update; old ReplicaSets retain old requests until their Pods are replaced. Operational check: set resources in the Pod template, apply the Deployment, inspect a replica with kubectl get pod -o yaml, and confirm containers[].resources.requests match the template for every replica. In CKAD scenarios involving q210, prefer verifying the live object with kubectl get and describe before changing cluster-wide settings.