
After a school district rolls a bad image, Pods repeatedly fail to start and show CrashLoopBackOff. What does that status primarily indicate?
Select an answer to reveal the explanation.
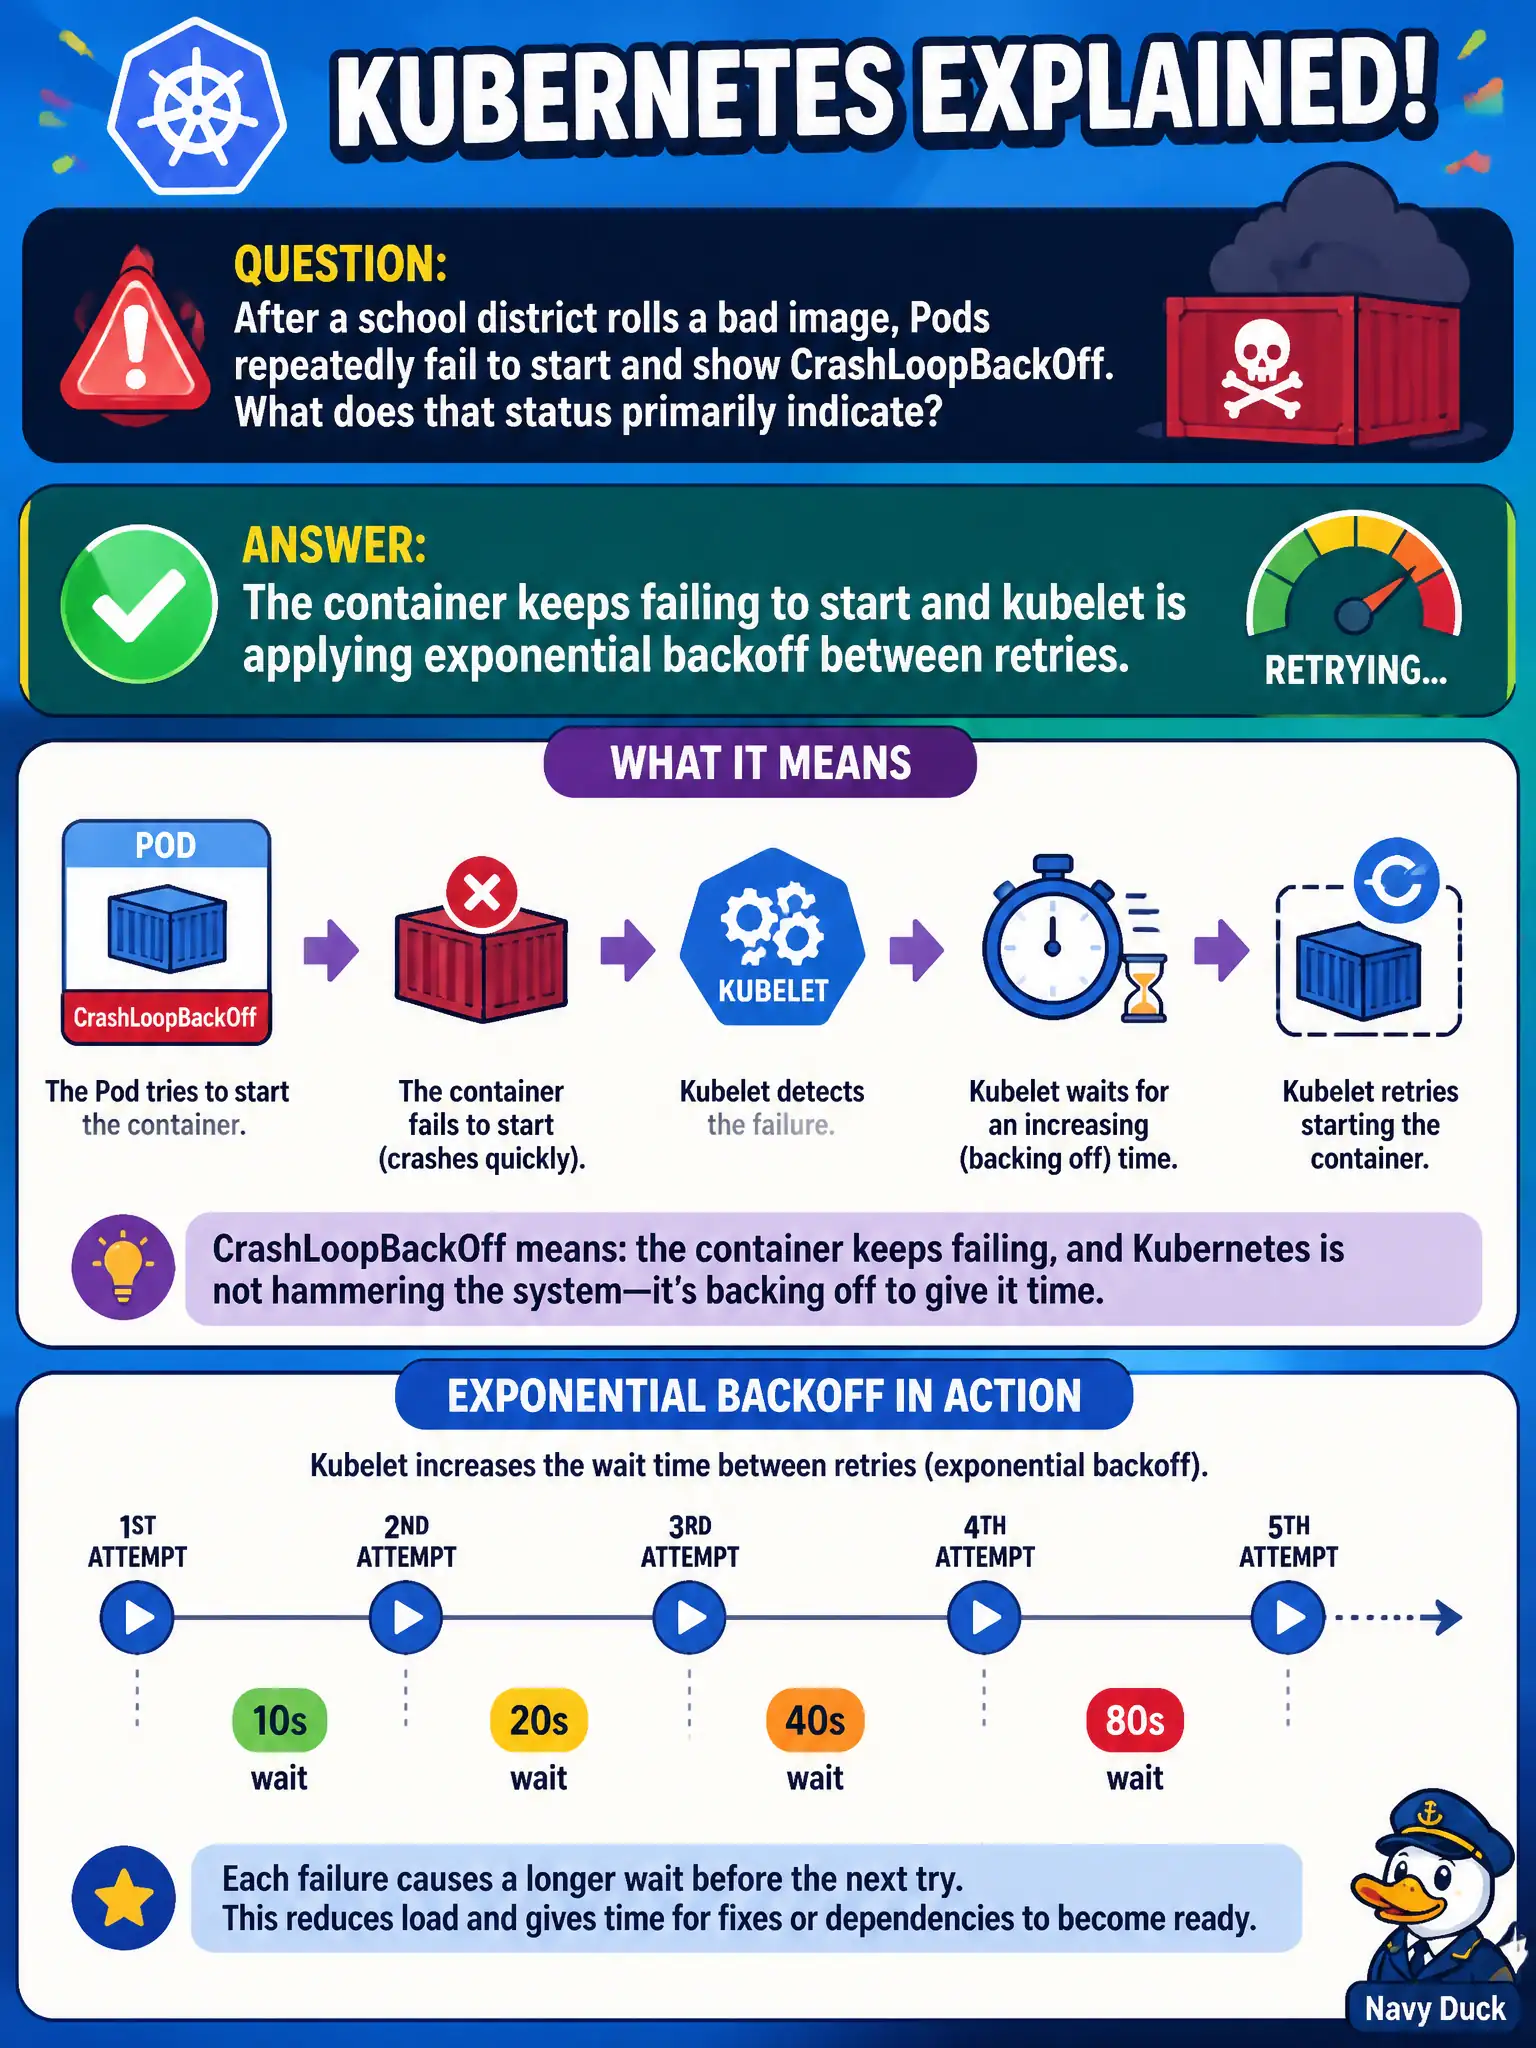
Short Explanation
CrashLoopBackOff is Kubernetes saying it keeps trying to start the container but keeps failing—and it is slowing down between tries so it does not hammer the node. It is still a self-heal attempt, just with a bad image or config underneath.
Full Explanation
After a school district rolls a bad image, Pods that repeatedly fail to start and show CrashLoopBackOff primarily indicate that the container keeps failing to start and kubelet is applying exponential backoff between retries. CrashLoopBackOff is the visible backoff state while kubelet keeps trying; it is a symptom of repeated start failures such as a bad image, missing config, or app panic, not a scheduler blacklist of the namespace.
The scheduler does not permanently blacklist the namespace and refuse retries because of CrashLoopBackOff. kube-apiserver rejecting the Deployment and deleting all replica history is not what CrashLoopBackOff means. NetworkPolicy silently dropping every probe packet is a different troubleshooting path and does not define CrashLoopBackOff.
Exam caveat: read kubectl describe events and container logs to find the underlying start error behind the backoff. Operational check: kubectl describe pod and kubectl logs for the crashing district Pods, fix the image or config, and confirm new Pods leave CrashLoopBackOff. This distinction matters on the CKA because distractors often mix adjacent objects that sound related but solve a different control-plane problem.