
911 platform engineers report that HorizontalPodAutoscalers never scale and kubectl top nodes/pods returns errors. Which missing component most directly explains both symptoms?
Select an answer to reveal the explanation.
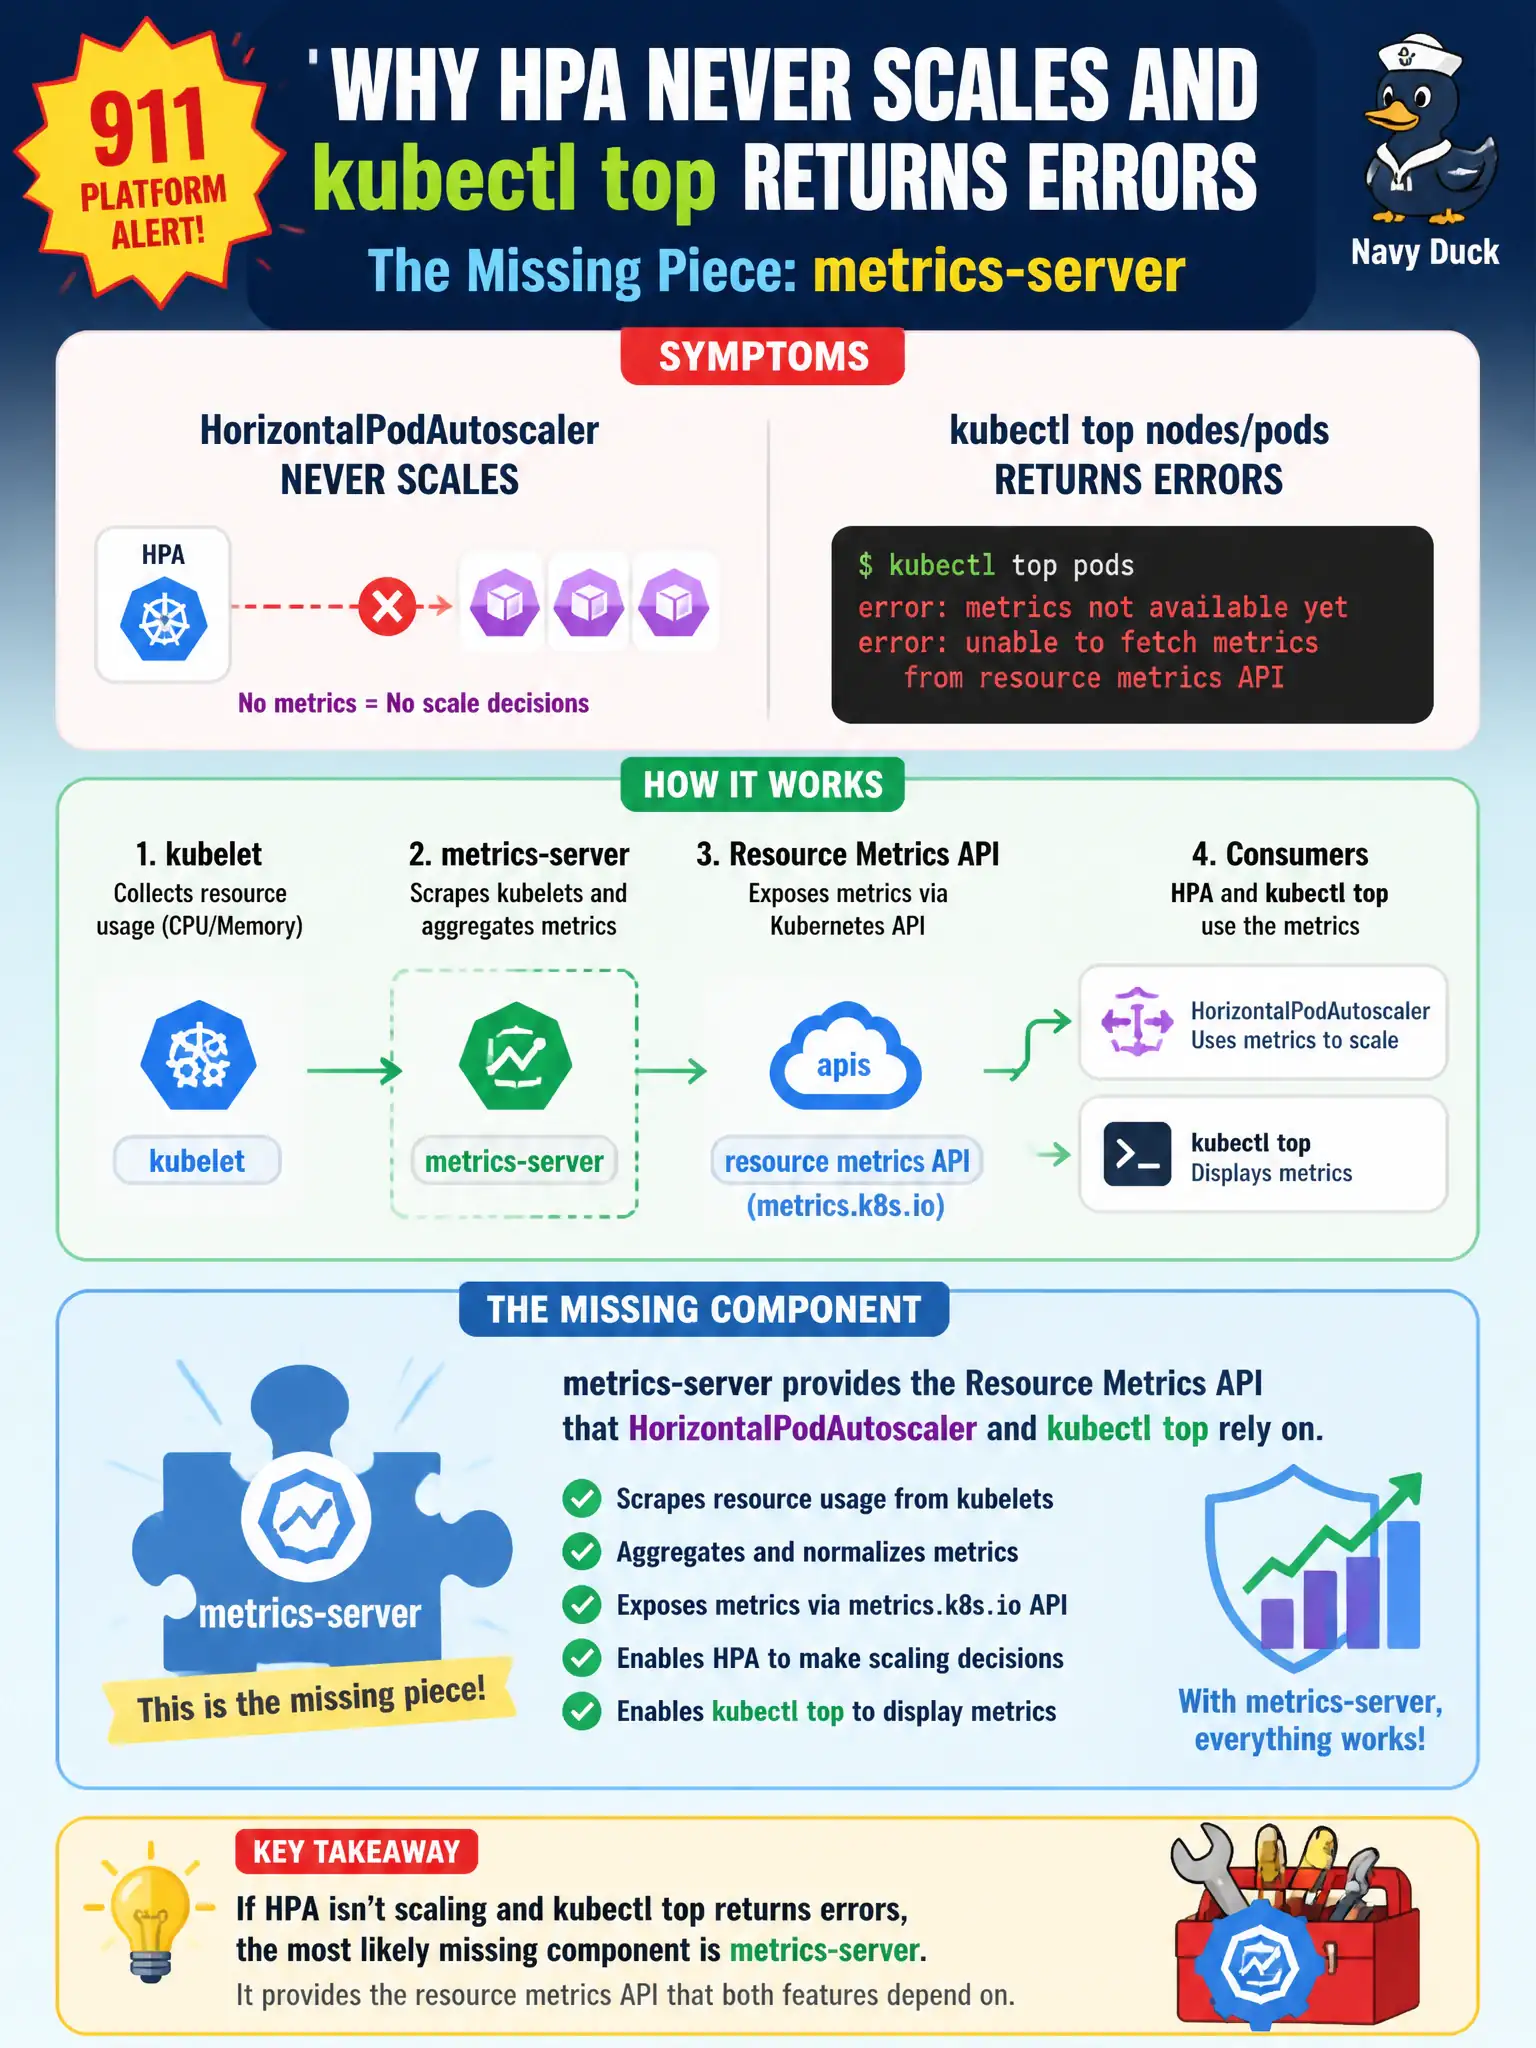
Short Explanation
HPA and kubectl top both shop at the same metrics counter. If metrics-server is missing, the store is closed—no scaling decisions and no top output.
Full Explanation
HorizontalPodAutoscalers and kubectl top both consume the resource metrics API typically served by metrics-server. When 911 platform engineers see HPA never scale and kubectl top nodes/pods return errors, the shared missing component is metrics-server (or an equivalent metrics pipeline). Without CPU and memory samples, neither autoscaling decisions nor top output can work. kube-proxy does not supply CPU samples to the metrics API; it programs Service forwarding rules on nodes and is the wrong component for this paired symptom. A default StorageClass affects dynamic volume provisioning, not whether resource metrics can be scraped or served for HPA and kubectl top. An Ingress controller fronts HTTP(S) traffic; it is not a prerequisite for kubectl top to query node or pod metrics from the metrics pipeline. Exam caveat: HPA can also stall when pods lack CPU/memory requests or when custom metrics adapters are missing even if metrics-server is healthy—but the combination of top errors plus HPA blindness strongly implicates the resource metrics pipeline first. Operational check: Deploy or repair metrics-server, confirm the metrics.k8s.io APIService is Available, re-run kubectl top, and verify HPA status can compute desired replicas for the civic workload.