
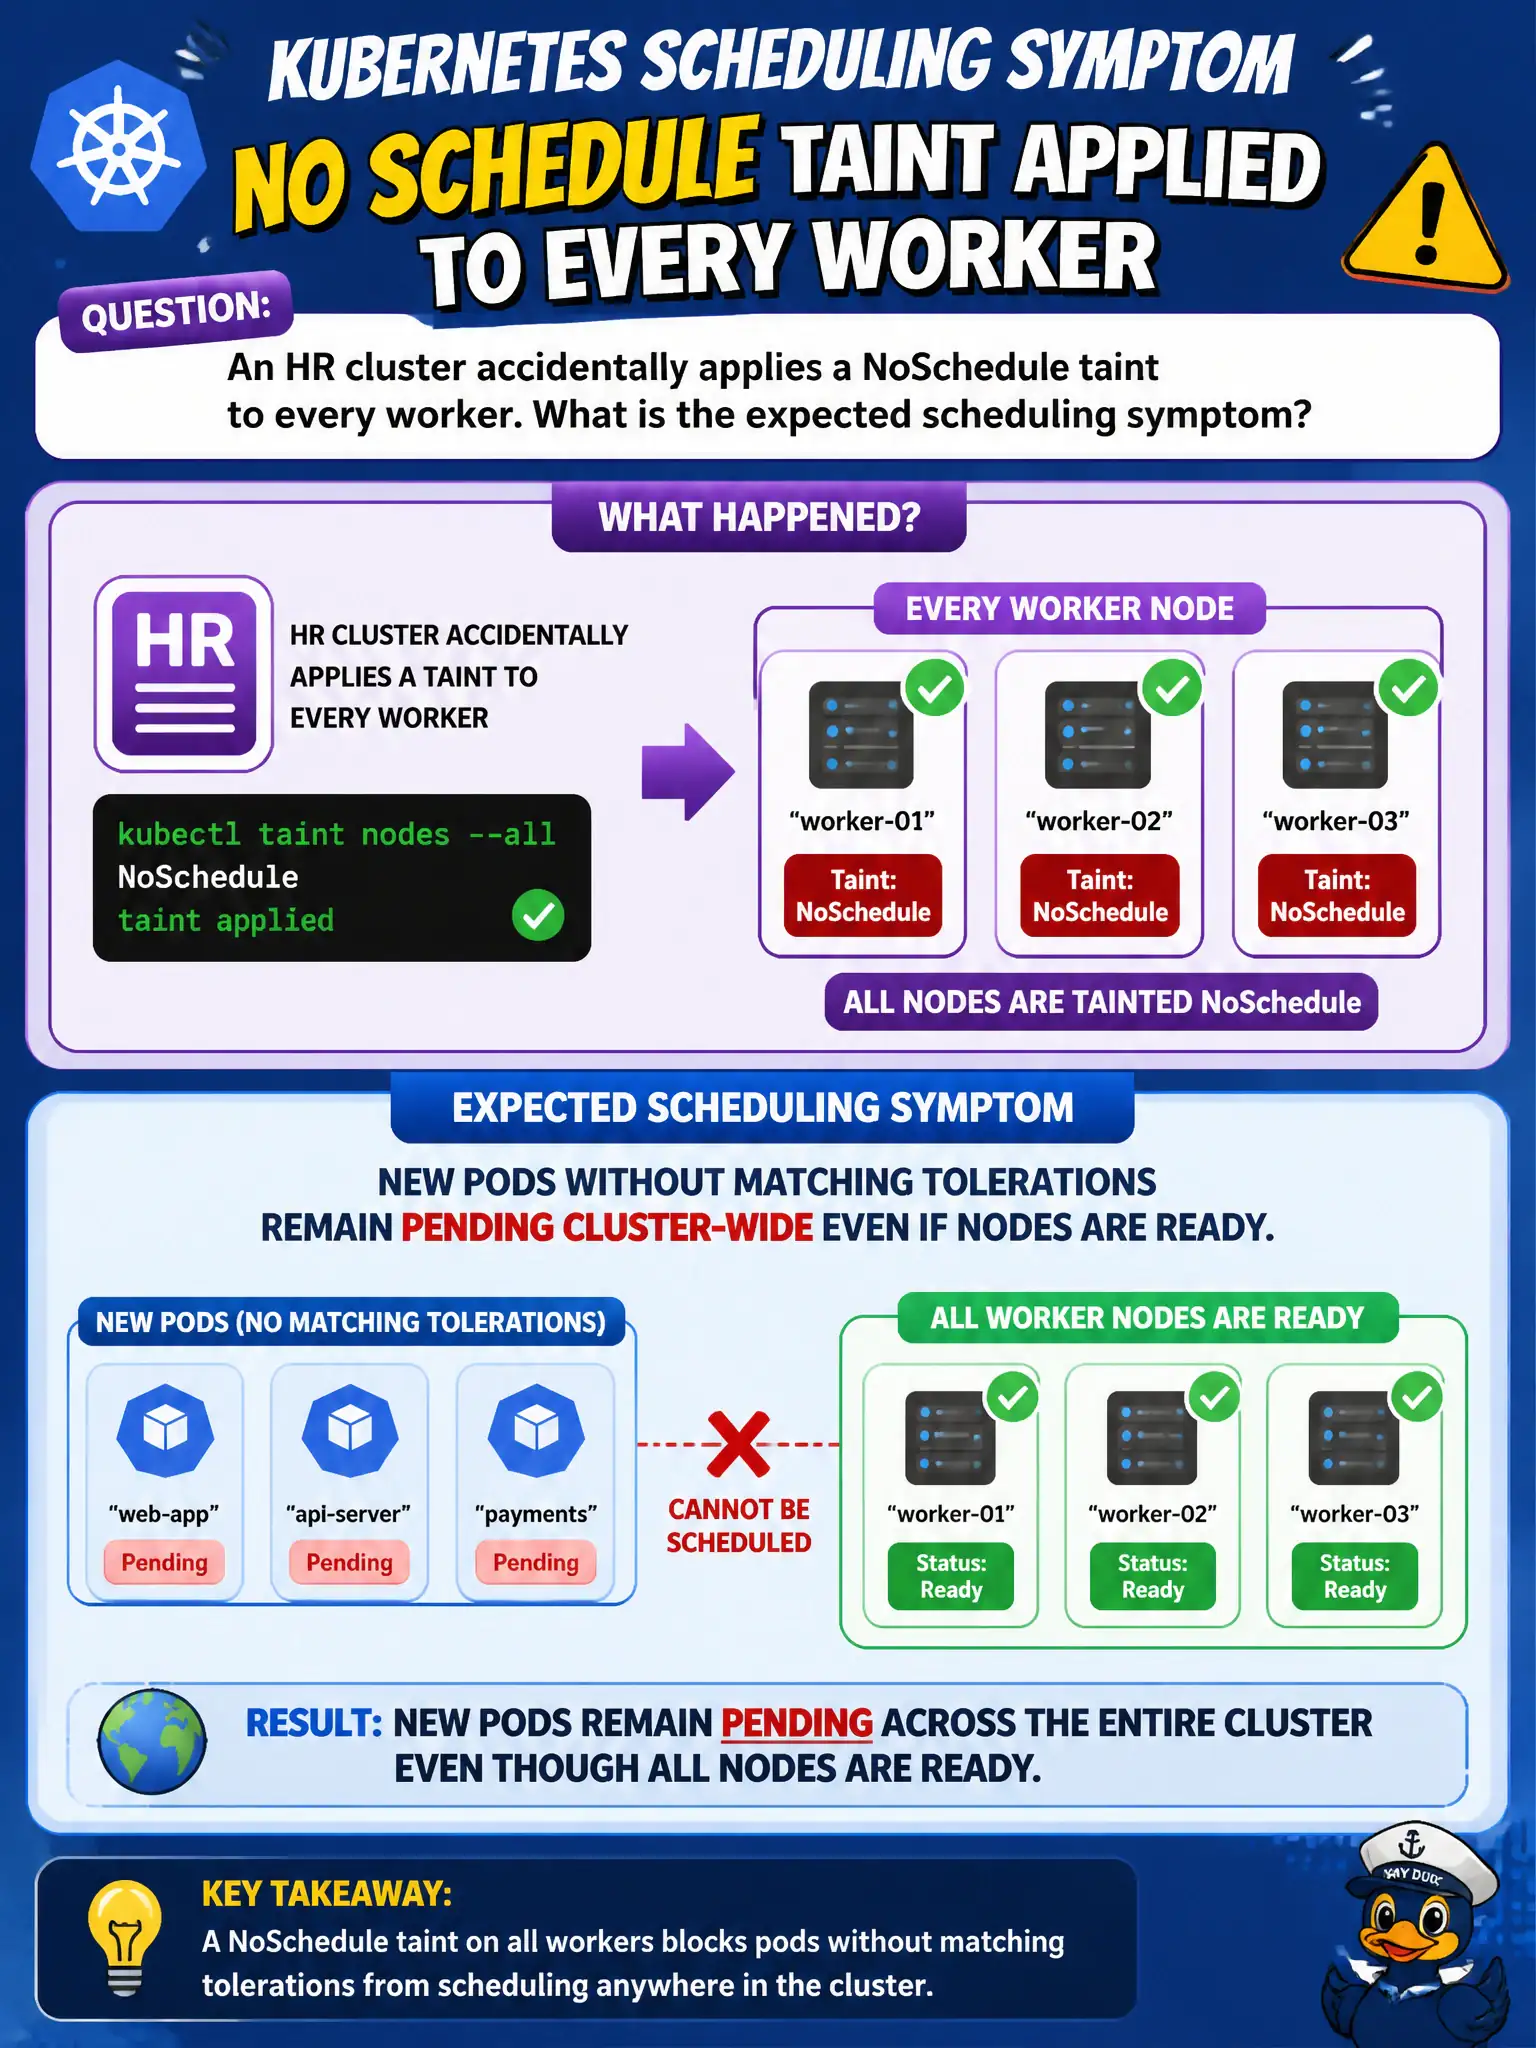
An HR cluster accidentally applies a NoSchedule taint to every worker. What is the expected scheduling symptom?
Select an answer to reveal the explanation.
Short Explanation
NoSchedule is a bouncer at the door. Without a matching toleration, new pods wait outside (Pending) even though the nodes still look Ready.
Full Explanation
If an HR cluster accidentally applies a NoSchedule taint to every worker, new Pods without matching tolerations remain Pending cluster-wide even if nodes are Ready. NoSchedule is a bouncer at the door—without a matching toleration, new Pods wait outside while nodes may still look healthy on get nodes.
All existing Pods are not immediately deleted regardless of tolerations—that eviction-oriented behavior is associated with NoExecute, not NoSchedule alone. NoSchedule taints do not only affect Ingress controllers and never Deployments—they affect scheduling generally. NoSchedule does not convert every node to NotReady until removed.
Exam caveat: pods that already scheduled keep running under NoSchedule; only new scheduling is blocked. Fix by removing the accidental taint or adding tolerations intentionally for system DaemonSets that need them.
Operational check: inspect node taints, remove the accidental NoSchedule taint from workers, and confirm Pending HR Deployments begin scheduling onto Ready nodes. Keep civic change tickets precise: record object names, namespaces, and before/after observations so the next on-call engineer can replay the fix without guesswork. Prefer reversible steps and verify Ready or Bound state before closing the incident.