
On a sanitation worker, containerd has crashed and the kubelet cannot start pods. What failure class does this represent?
Select an answer to reveal the explanation.
Short Explanation
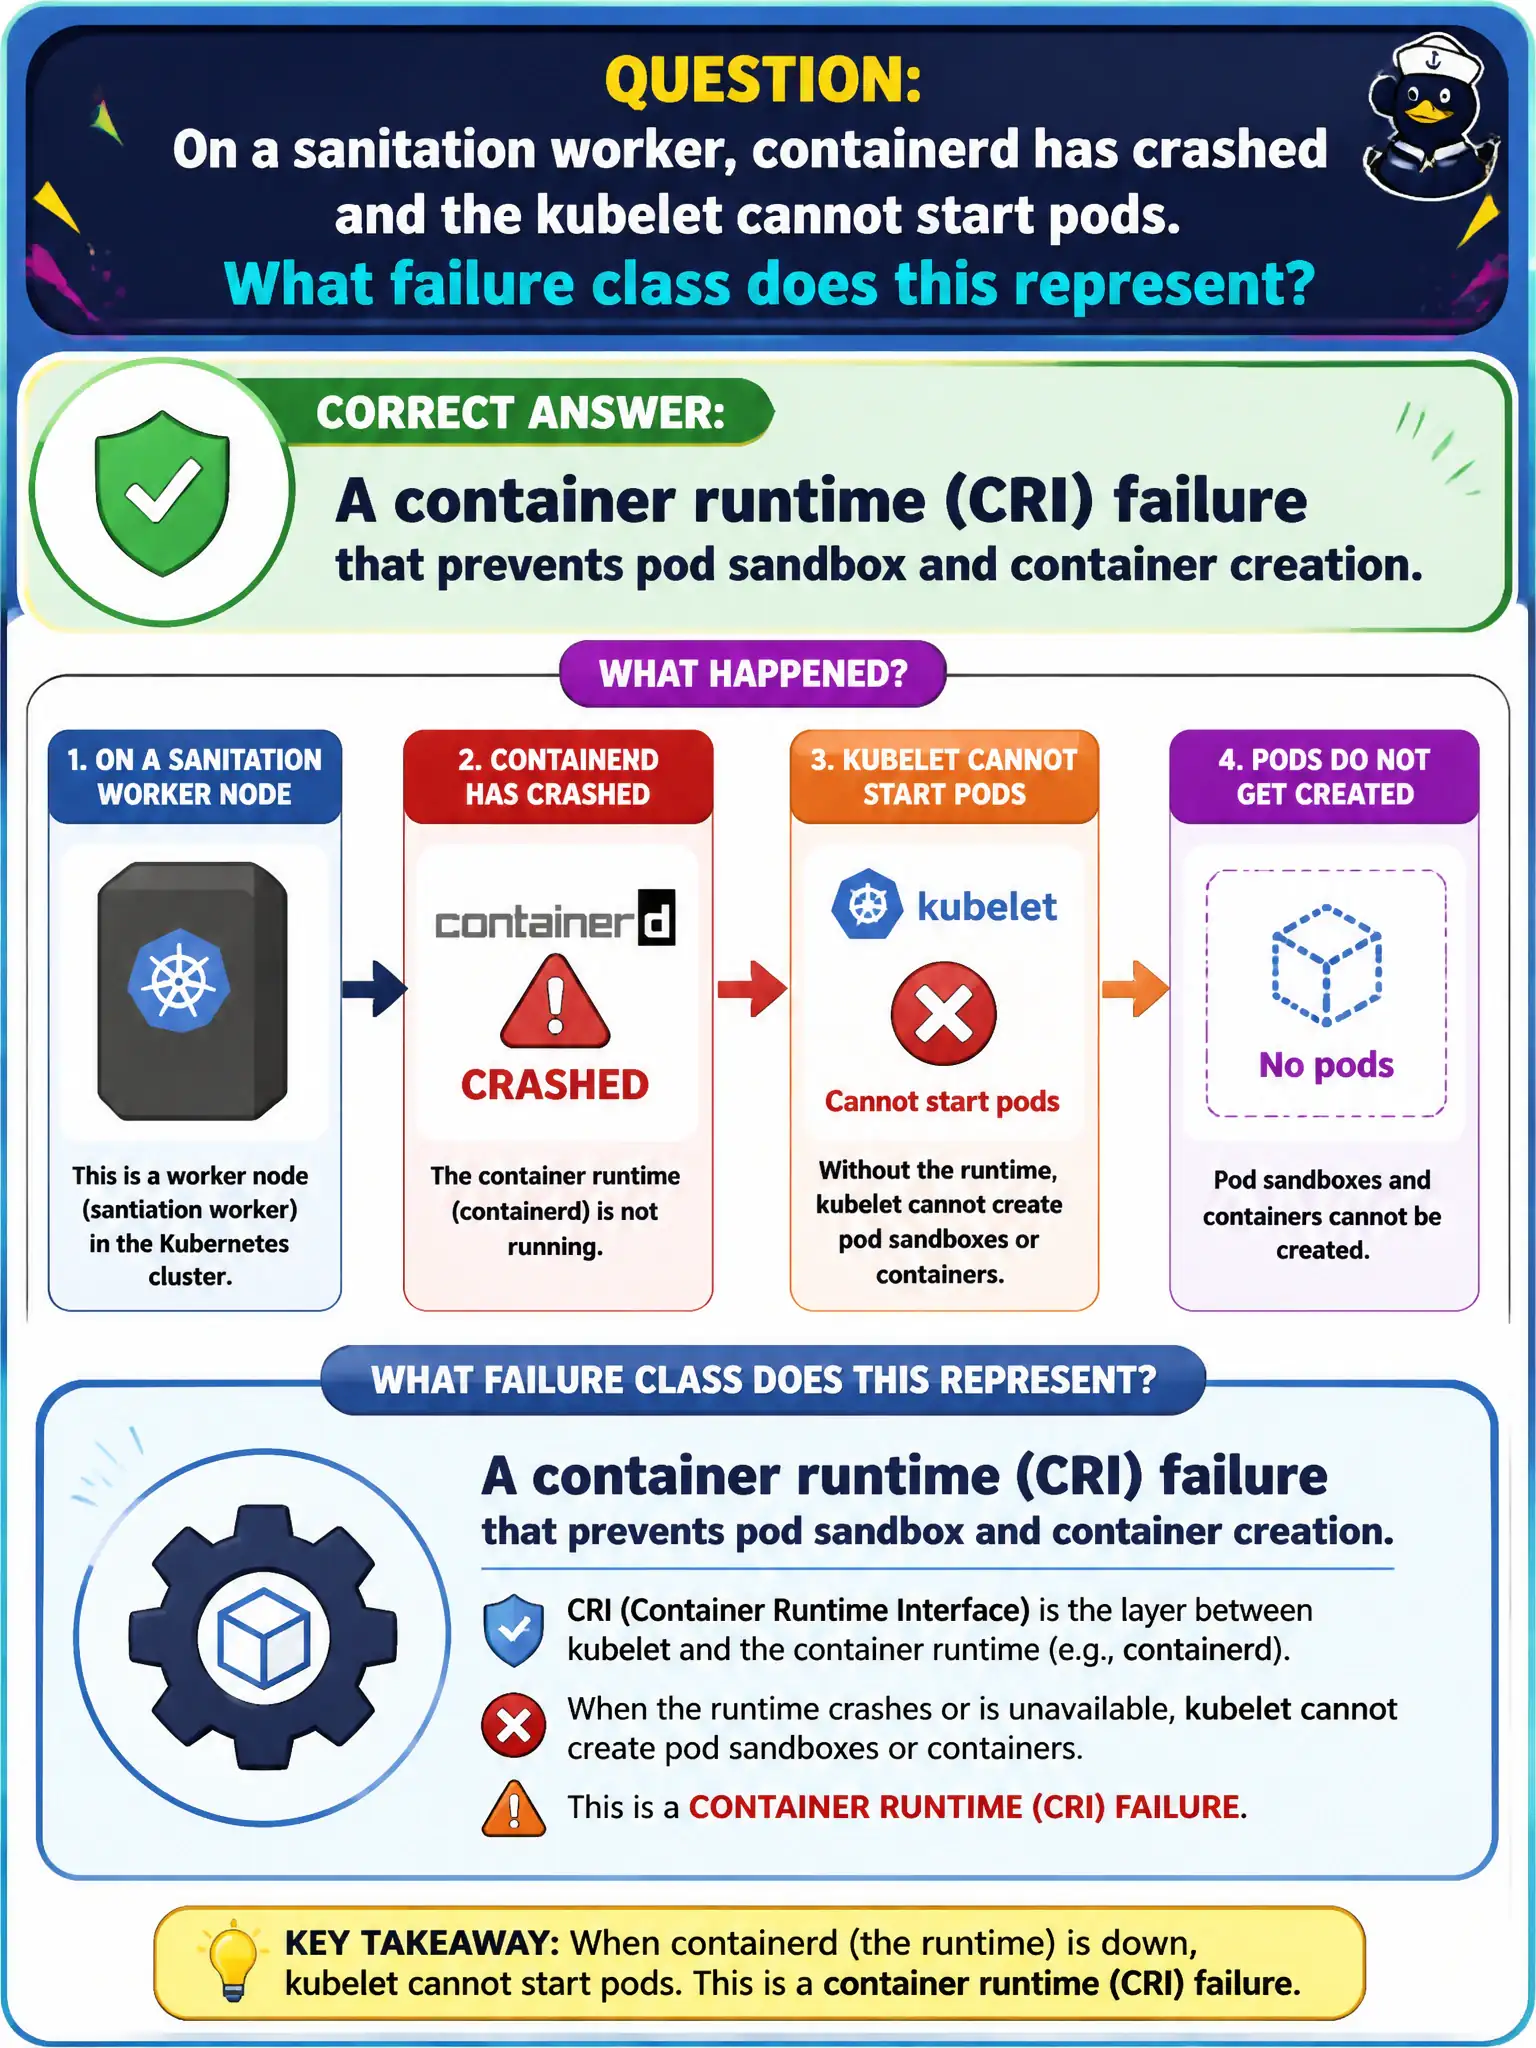
Kubelet delegates “run containers” to the runtime. When containerd is down, that handoff fails and pods never start.
Full Explanation
On a sanitation worker where containerd has crashed and kubelet cannot start Pods, the failure class is a container runtime (CRI) failure that prevents pod sandbox and container creation. Kubelet delegates “run containers” to the runtime—when containerd is down, that handoff fails and Pods never start. The node may also report NotReady while the runtime is unavailable.
This is not merely a CoreDNS stubDomains misconfiguration. It is not only a Gateway API HTTPRoute syntax error. It is not only a StorageClass allowVolumeExpansion flag set to false.
Exam caveat: other CRI runtimes exist (such as CRI-O), but the class of failure is the same—runtime down means no sandboxes. Check runtime service logs separately from kubelet logs for clearer root cause.
Operational check: check and restart containerd (or equivalent), verify CRI is responsive via crictl, confirm kubelet can create Pods again, and recheck sanitation node Ready status. Keep civic change tickets precise: record object names, namespaces, and before/after observations so the next on-call engineer can replay the fix without guesswork. Prefer reversible steps and verify Ready or Bound state before closing the incident. Keep civic change tickets precise: record object names, namespaces, and before/after observations so the next on-call engineer can replay the fix without guesswork. Prefer reversible steps and verify Ready or Bound state before closing the incident.