
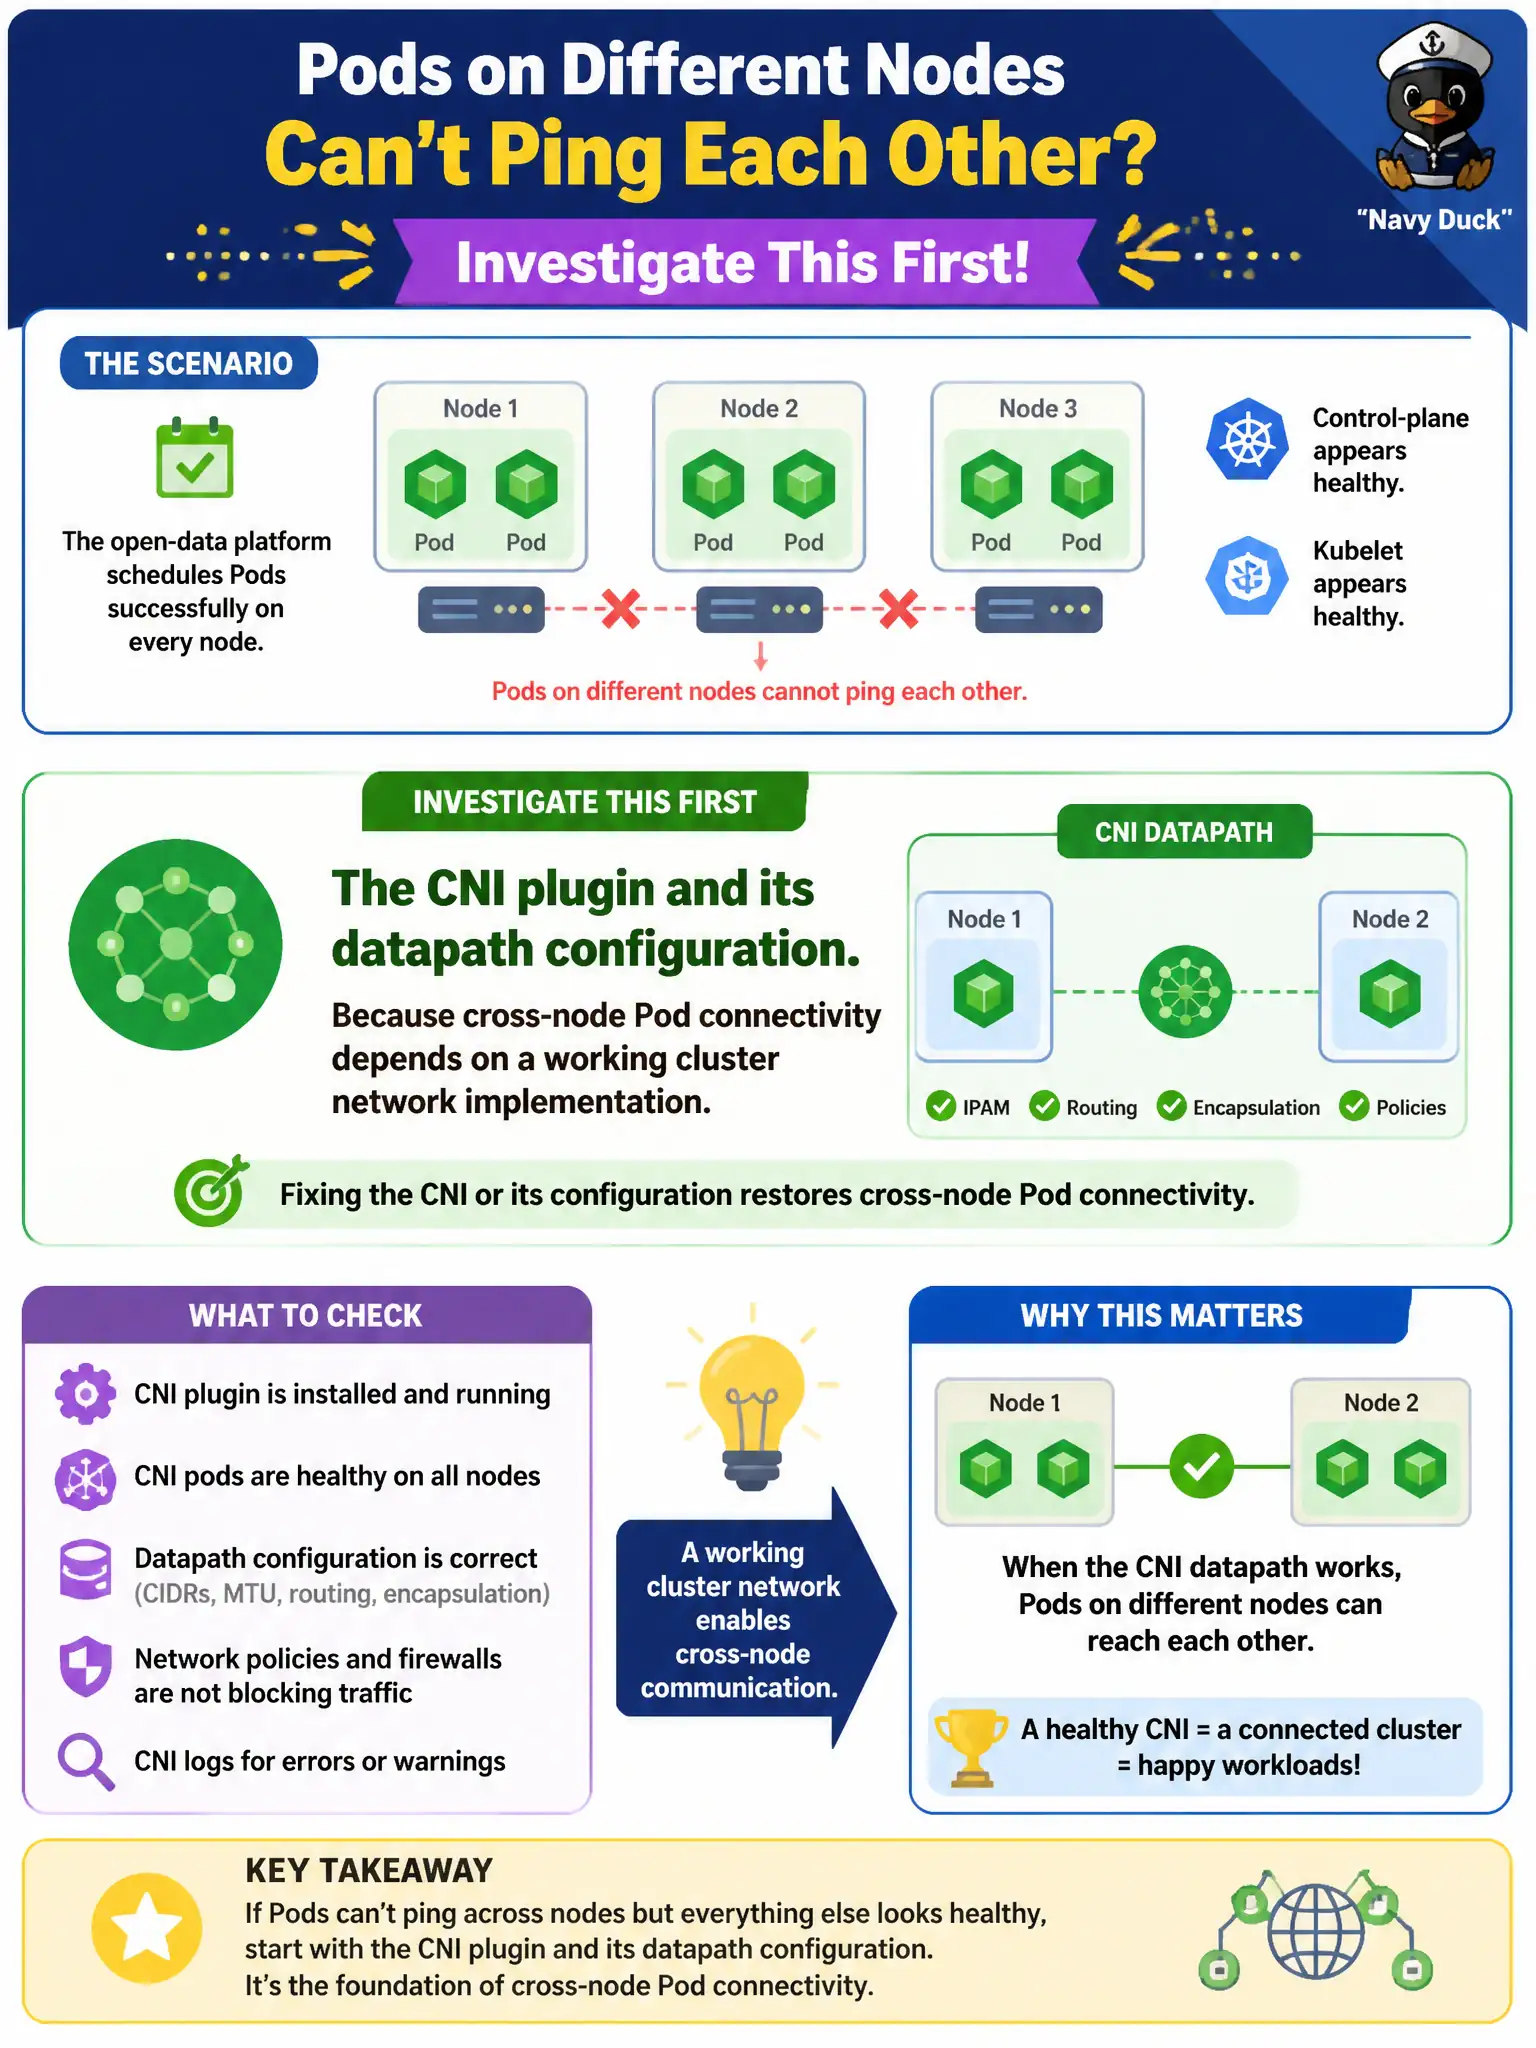
An open-data platform schedules Pods successfully on every node, but Pods on different nodes cannot ping each other. Control-plane and kubelet appear healthy. What should the administrator investigate first?
Select an answer to reveal the explanation.
Short Explanation
If Pods land on nodes but can't talk across the building, the hallway wiring — the CNI — is the first place to look, not HPA or TLS Ingress.
Full Explanation
An open-data platform that schedules Pods successfully on every node but cannot ping between Pods on different nodes—while control-plane and kubelet appear healthy—should investigate the CNI plugin and its datapath configuration first, because cross-node Pod connectivity depends on a working cluster network implementation. Successful scheduling only proves the scheduler and kubelet admitted Pods; east-west traffic still needs routes, overlays, or underlay wiring from the CNI.
Whether every Pod has been assigned a ClusterIP Service even when no Service was requested is not the first cross-node ping dependency. HorizontalPodAutoscaler being disabled is unrelated to ICMP between Pods. Ingress TLS secrets in kube-system do not terminate all Pod-to-Pod traffic and are not the first check.
Exam caveat: same-node success with cross-node failure is a classic CNI/datapath symptom. Operational check: compare same-node versus cross-node Pod pings, inspect CNI agent Pods and node routes, and remediate the network plugin before chasing application bugs. This distinction matters on the CKA because distractors often mix adjacent objects that sound related but solve a different control-plane problem.