
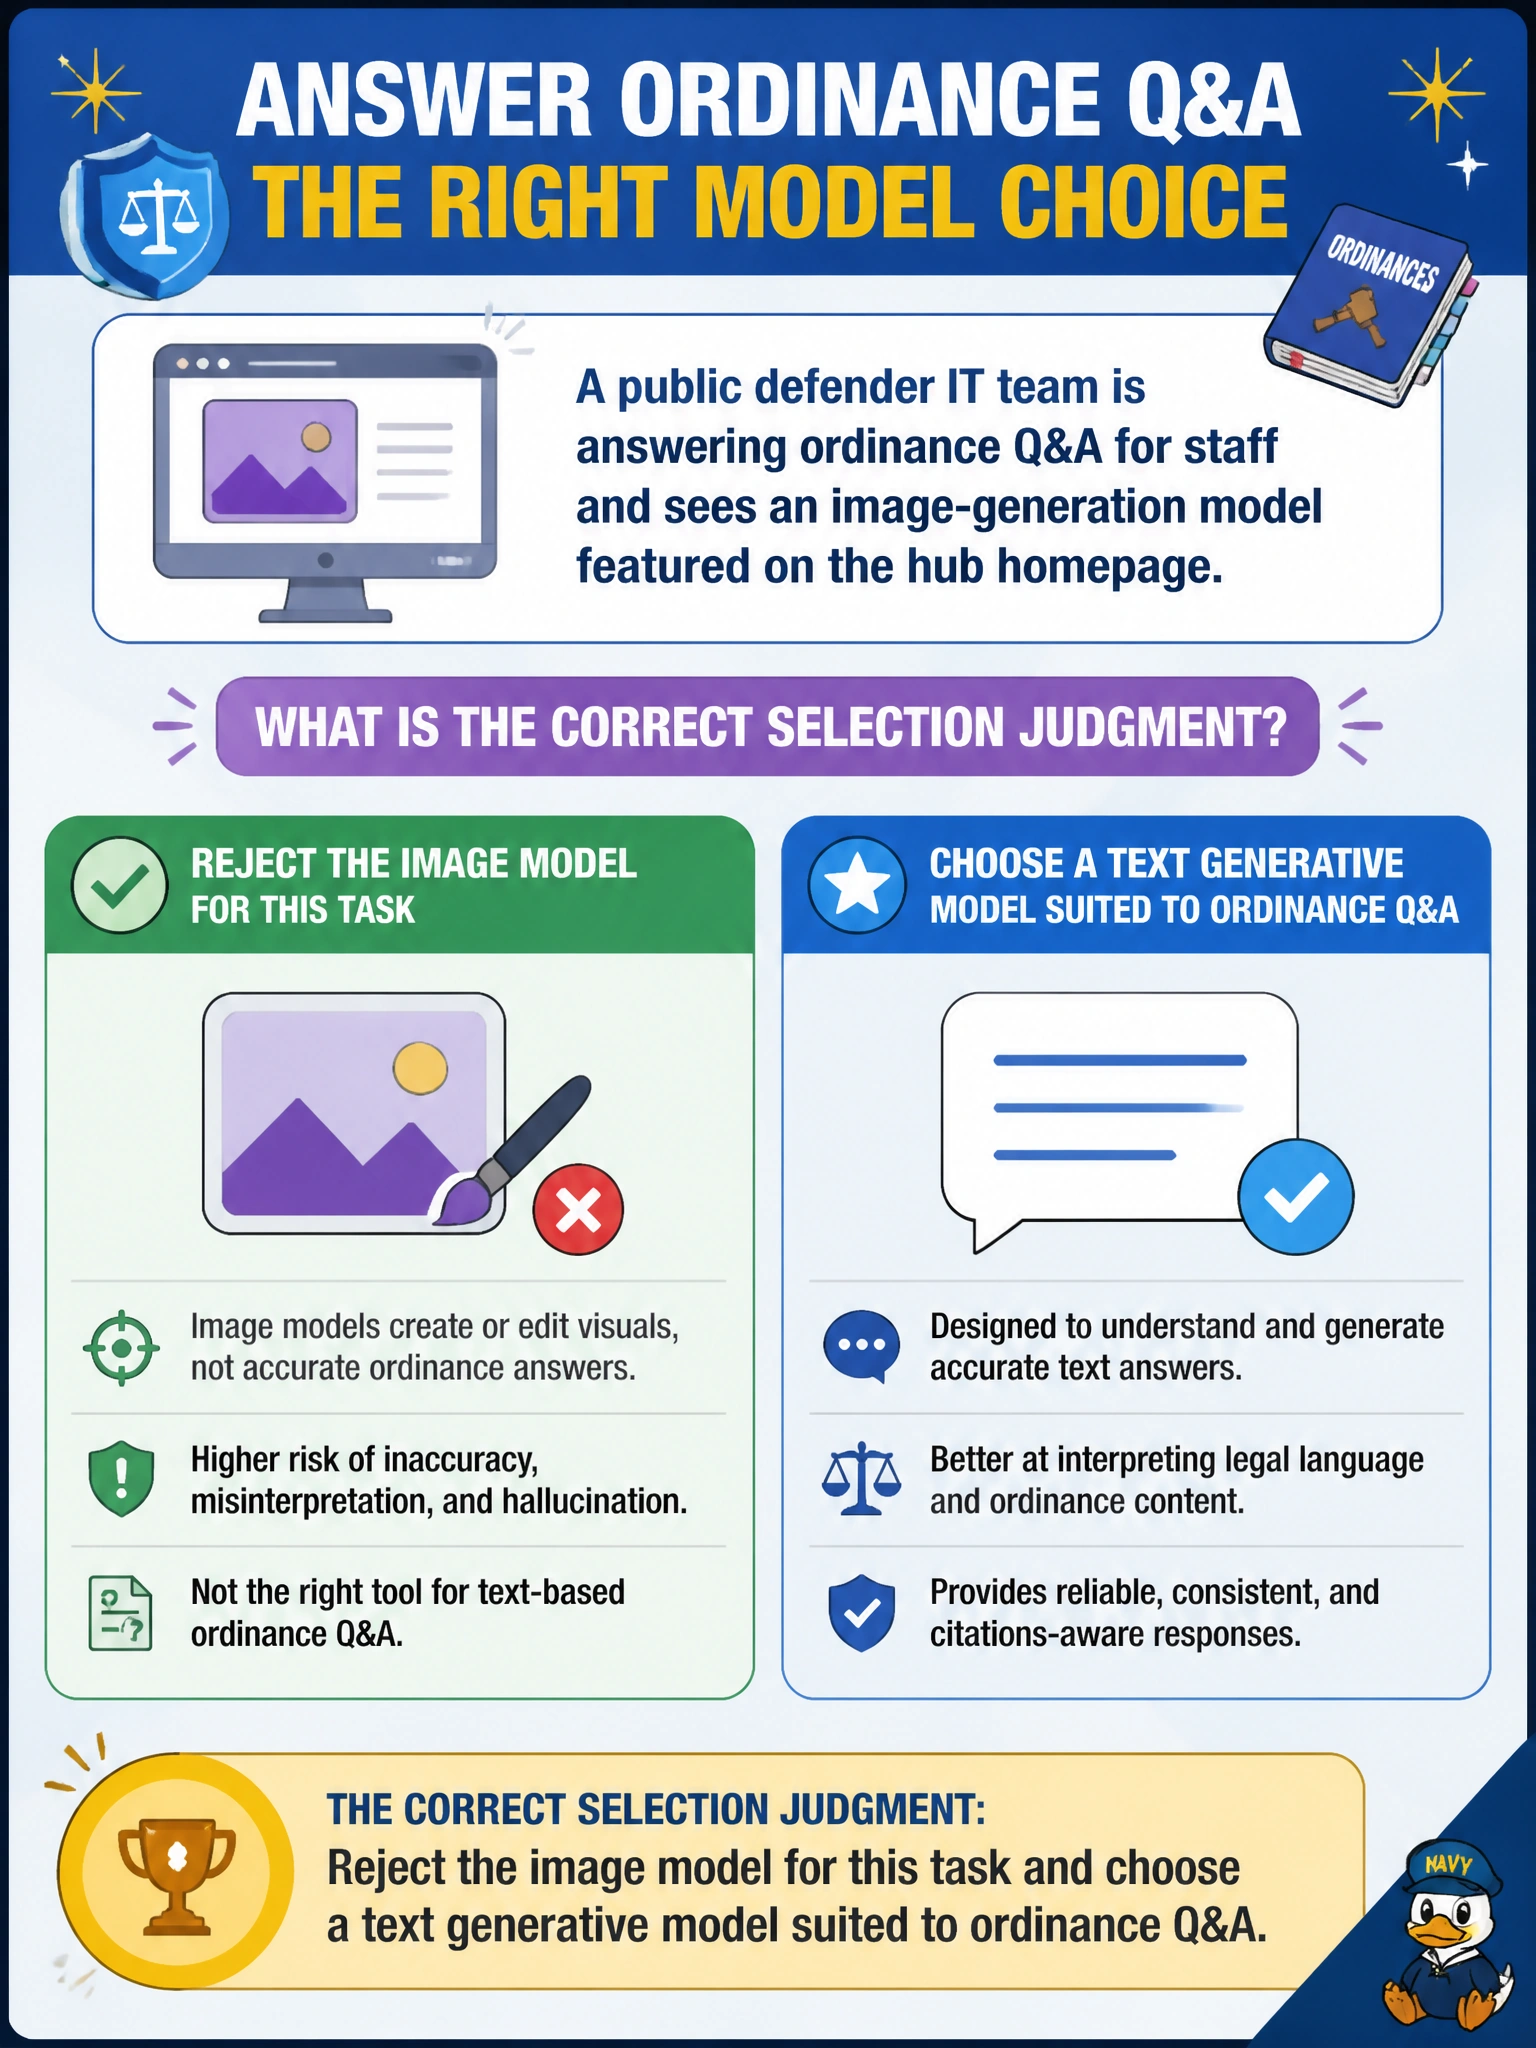
A public defender IT team is answering ordinance Q&A for staff and sees an image-generation model featured on the hub homepage. What is the correct selection judgment?
Select an answer to reveal the explanation.
Short Explanation
If the job is answering ordinance questions, don't hire the poster artist. Skip the mismatched image model and pick a text generative model that actually reads and explains the code.
Full Explanation
Public-defender ordinance Q&A is a text generative task: read statutory language, answer staff questions, and stay faithful to adopted wording. When an image-generation model is featured on the hub homepage, the correct judgment is to reject that mismatched modality for this task and choose a text generative model suited to ordinance Q&A. Homepage placement is marketing, not a fitness certificate for legal research assistance.
Adopting the image model because homepage placement "guarantees legal accuracy" confuses catalog promotion with evaluation; image models do not answer ordinance questions accurately by virtue of being featured. Using the image model to paint murals of each ordinance instead of answering questions abandons the Q&A use case. Assuming any multimodal card automatically outperforms text models on pure Q&A is unsupported—modality breadth does not imply superior text legal QA without evidence on the workload.
Exam caveat: even the right text model should be paired with retrieval of current ordinances; parametric memory alone can lag amendments. Operational check: exclude diffusion/image cards from the ordinance-assistant shortlist, evaluate text generative candidates on a defender FAQ set, and record that homepage features were ignored as selection signals.