
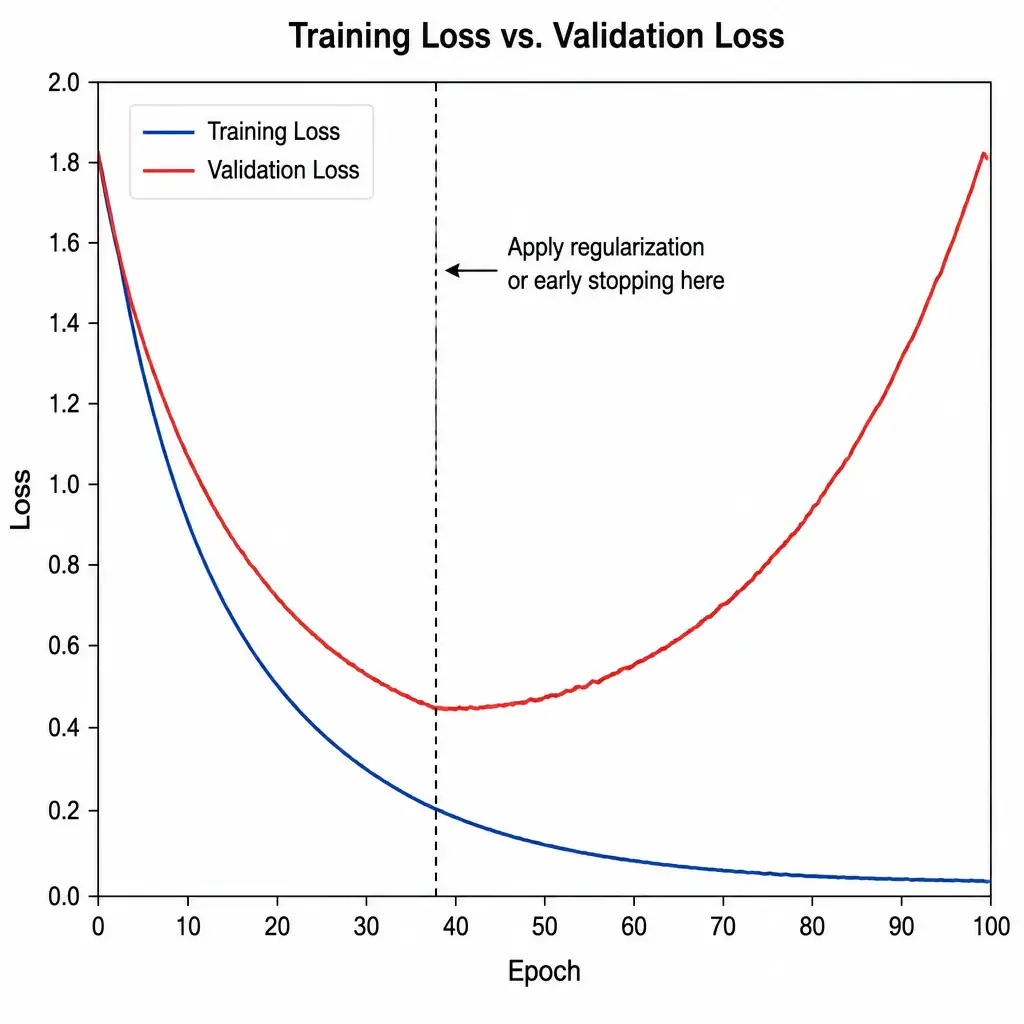
While training a deep neural network, you observe that the training loss continuously decreases to a near-zero value, but the validation loss begins to rise sharply after a certain epoch. Which approach is most appropriate to resolve this issue?
Select an answer to reveal the explanation.
Short Explanation
You're seeing classic overfitting: training loss drops while validation loss climbs, so the model is memorizing instead of generalizing. Use regularization like dropout, weight decay, or early stopping to force it to learn broader patterns. Don't make it more complex or train longer—that just makes it worse.
Full Explanation
The divergence between a low training loss and a high validation loss is the classic hallmark of overfitting, which is a high-variance problem. Overfitting occurs when a machine learning model learns the training data too well, capturing noise, random fluctuations, and highly specific details that do not generalize to unseen validation or test data. To mitigate overfitting, several strategies can be employed, primarily centered around regularization and reducing effective model capacity: regularization such as L1 or L2 adds a penalty term to the loss function based on the magnitude of the model weights, where L1 encourages sparsity by driving some weights to zero and L2 prevents any single weight from becoming too large; dropout randomly deactivates a fraction of neurons during each training step in a deep neural network, forcing the model to learn redundant, robust representations; early stopping monitors validation loss during training and halts the process as soon as validation performance begins to degrade, preventing the model from over-optimizing on the training set; and data augmentation increases the diversity of the training set, making it harder for the model to memorize specific samples. The other options would worsen or miss the issue: increasing the model's capacity by adding more hidden layers and parameters gives the model even more capacity and opportunity to memorize noise, running the training process for a much larger number of epochs also gives the model more opportunity to memorize noise, and increasing the learning rate of the optimizer to push training out of local minima can cause optimization instability but does not address generalization directly.