
A developer is using a pre-trained BERT (Bidirectional Encoder Representations from Transformers) model for a text classification task. What is the defining architectural characteristic of the BERT model?
Select an answer to reveal the explanation.
Short Explanation
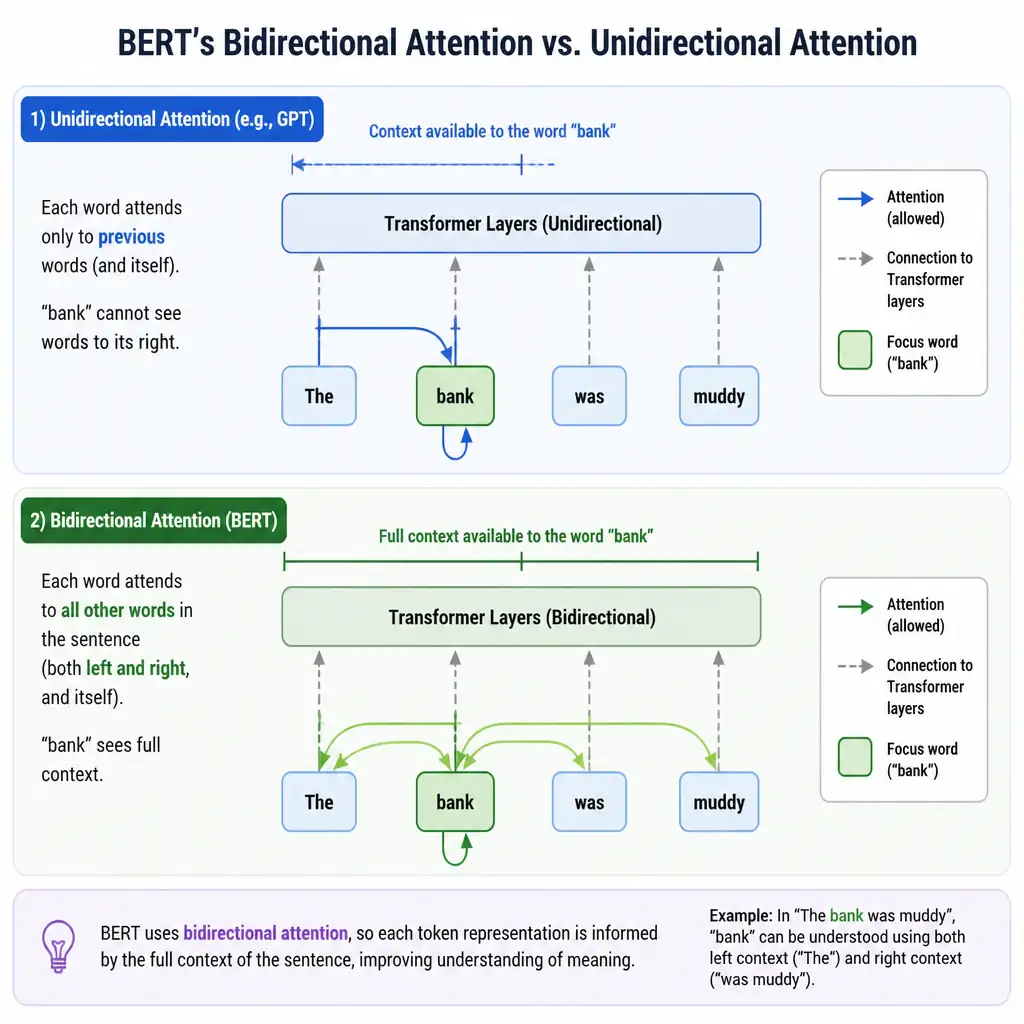
You need to remember that BERT stands for Bidirectional Encoder Representations from Transformers, so the defining trait is the Transformer encoder looking at both directions at once. That bidirectional self-attention is what lets you capture context from words before and after a target word. The other ideas, like sequential RNN/LSTM processing, image-only feedforward networks, or left-to-right decoder-only generation, don't fit BERT.
Full Explanation
BERT (Bidirectional Encoder Representations from Transformers) is a landmark language model developed by Google. Its primary architectural characteristic is its use of the Transformer encoder, which utilizes self-attention to model bidirectional context. Unlike traditional sequential models like LSTMs or unidirectional models (like GPT, which are autoregressive decoders that process text left-to-right), BERT reads the entire sequence of words at once. This non-directional approach allows the model to learn the context of a word based on all of its surroundings (both left and right of the word) across all layers. The correct choice is the Transformer encoder architecture using bidirectional self-attention.
Let's check the distractors: - The recurrent neural network (RNN) structure with LSTM cells to process text sequentially is incorrect because BERT is a Transformer-based model, not a recurrent model (RNN/LSTM). Transformers replaced recurrence with self-attention to allow parallel processing. - The feedforward neural network optimized solely for spatial image classification is incorrect because BERT is a language model designed for Natural Language Processing (NLP), not spatial image classification. - The autoregressive decoder-only network that processes text strictly from left to right is incorrect because it describes autoregressive decoder models (like the GPT series), which are unidirectional (left-to-right) and designed for text generation rather than bidirectional context representation.
For the exam, remember that BERT uses the Transformer encoder, making it inherently bidirectional in its attention mechanism.