
The Adam optimizer is widely used for training deep neural networks due to its fast convergence and robust performance. What are the two core mechanisms that Adam combines to achieve this efficiency?
Select an answer to reveal the explanation.
Short Explanation
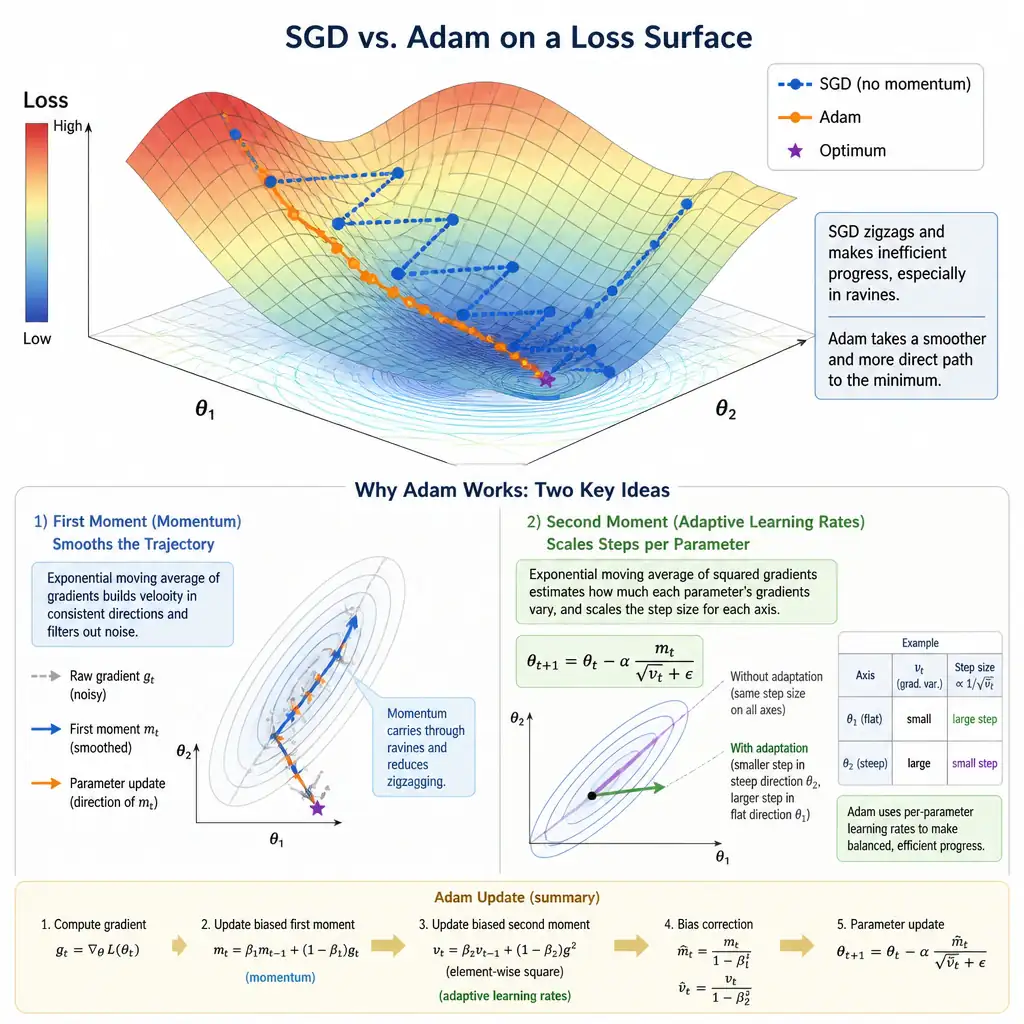
Here's the deal: Adam wins because it blends momentum—an exponentially decaying average of past gradients—with individual adaptive learning rates for each parameter. That lets you keep speed in consistent directions while scaling each weight's step size based on its own gradient history. Fast, stable, and smart.
Full Explanation
The Adam (Adaptive Moment Estimation) optimization algorithm is designed to improve training speeds and stability compared to standard Stochastic Gradient Descent (SGD). Its effectiveness stems from combining two key concepts: momentum and adaptive learning rates.
1. Momentum (First Moment Vector): Adam maintains an exponentially decaying average of past gradients (similar to SGD with momentum). This helps accelerate the optimizer in directions of consistent gradients, reducing oscillation and helping the optimization path navigate out of shallow local minima or flat regions. 2. Adaptive Learning Rates (Second Moment Vector): Adam computes individual learning rates for different parameters by tracking the exponentially decaying average of the squared gradients. If a parameter's gradient is highly volatile or very large, its learning rate is scaled down; conversely, parameters with small, sparse updates receive larger steps. Furthermore, Adam introduces default hyperparameters (such as β1 = 0.9 for momentum, β2 = 0.999 for scaling, and ε = 10^-8 to prevent division by zero) which work remarkably well out-of-the-box for most architectures.
The answer that says an exponentially decaying average of past gradients (momentum) and individual adaptive learning rates for each parameter is correct.
Why the other choices are incorrect: - The choice that says static weight decay and global learning rate scheduling is incorrect because static weight decay is a regularization penalty rather than Adam's adaptive moment mechanism, and global learning rate scheduling is an external hyperparameter schedule rather than the per-parameter adaptive mechanism inside Adam. A loss function is separate from the optimization algorithm itself, and a static learning rate is a hyperparameter rather than the adaptive mechanism inside Adam. - The choice that says gradient clipping and dynamic dropout rate adjustments is incorrect because gradient clipping is an external technique used to prevent exploding gradients, and dropout is a regularization method applied to layer activations, not a component of the optimizer. - The choice that says L1 regularization (Lasso) and batch-normalized step sizing is incorrect because L1 regularization is a penalty added to the loss function, and batch normalization is a layer-level technique used to stabilize inputs to subsequent layers, not part of the optimizer's math.