
When training a machine learning model, you observe that increasing the model's complexity reduces its training error but increases its error on unseen test data. What fundamental concept in machine learning describes this tension between a model's capacity to fit the training dataset and its ability to generalize effectively to new, unseen data?
Select an answer to reveal the explanation.
Short Explanation
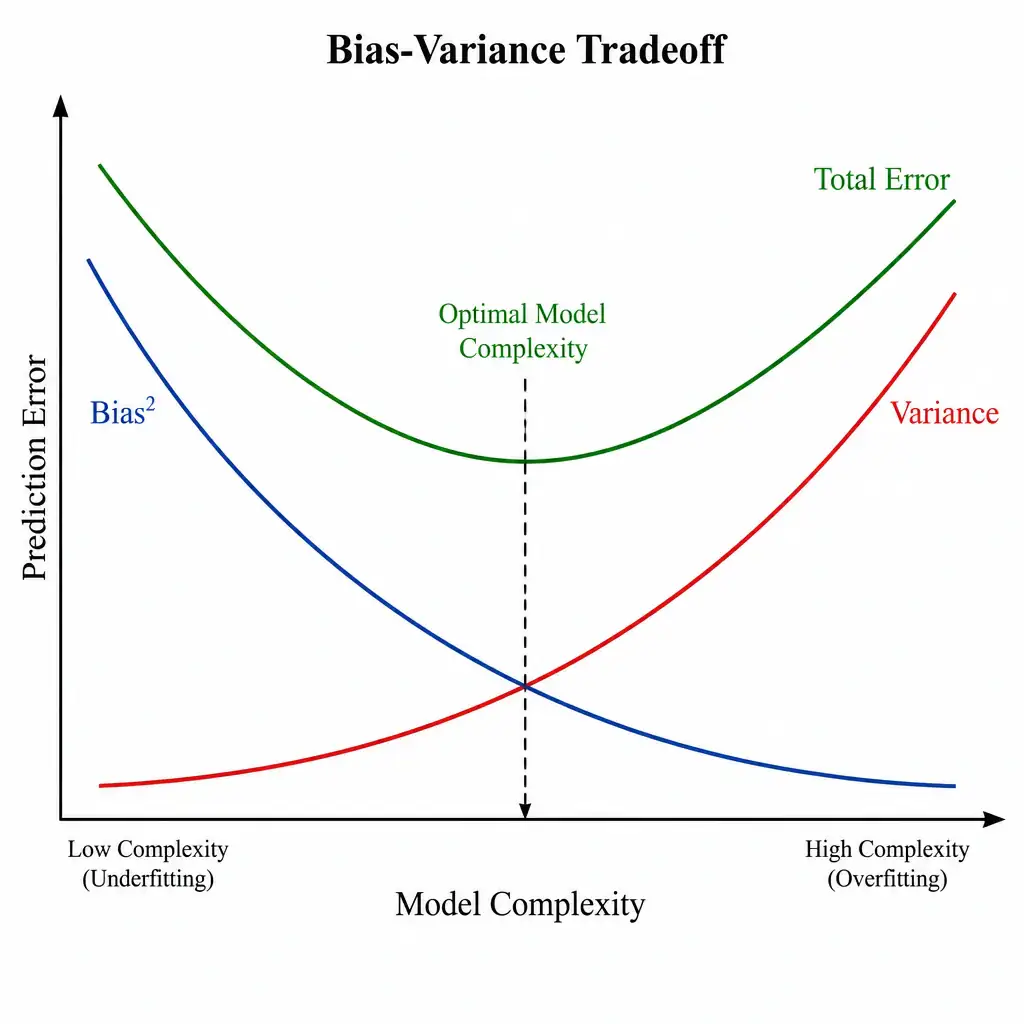
When your model fits training data better but fails on new data, you're seeing the bias-variance tradeoff. Simple models have high bias and underfit; complex models have high variance and overfit. You need the sweet spot that minimizes total error.
Full Explanation
The bias-variance tradeoff is a central concept in supervised machine learning that describes the relationship between a model's complexity, its training performance, and its generalization error on unseen data. It is the balance between two sources of error that prevent supervised learning algorithms from generalizing beyond their training set. Bias is the error introduced by approximating a real-world problem, which may be highly complex, with a simpler model. High bias leads to underfitting, where the model fails to capture the underlying patterns in the training data. Variance is the error from sensitivity to small fluctuations in the training set. High variance leads to overfitting, where the model learns the noise and random fluctuations in the training data rather than the true underlying relationships. As model complexity increases, bias decreases because the model fits the training data better, but variance increases because the model becomes less stable when applied to new datasets. The tradeoff involves finding the optimal level of complexity that minimizes total error, which is the sum of bias squared, variance, and irreducible noise. The supervised-unsupervised dichotomy refers to whether an algorithm trains on labeled data or unlabeled data, which is a structural categorization of algorithms rather than an error tradeoff. The feature-label distinction represents the separation between input data columns and output prediction targets. The learning rate decay limit refers to optimization schedules used during neural network training to adjust step size, not the relationship between training fit and generalization. Therefore, the bias-variance tradeoff is the correct concept describing this generalization tension.