
IT staff use “Hadoop” and “MapReduce” as if the words were identical. How should a BDPC-oriented explanation separate them?
Select an answer to reveal the explanation.
Short Explanation
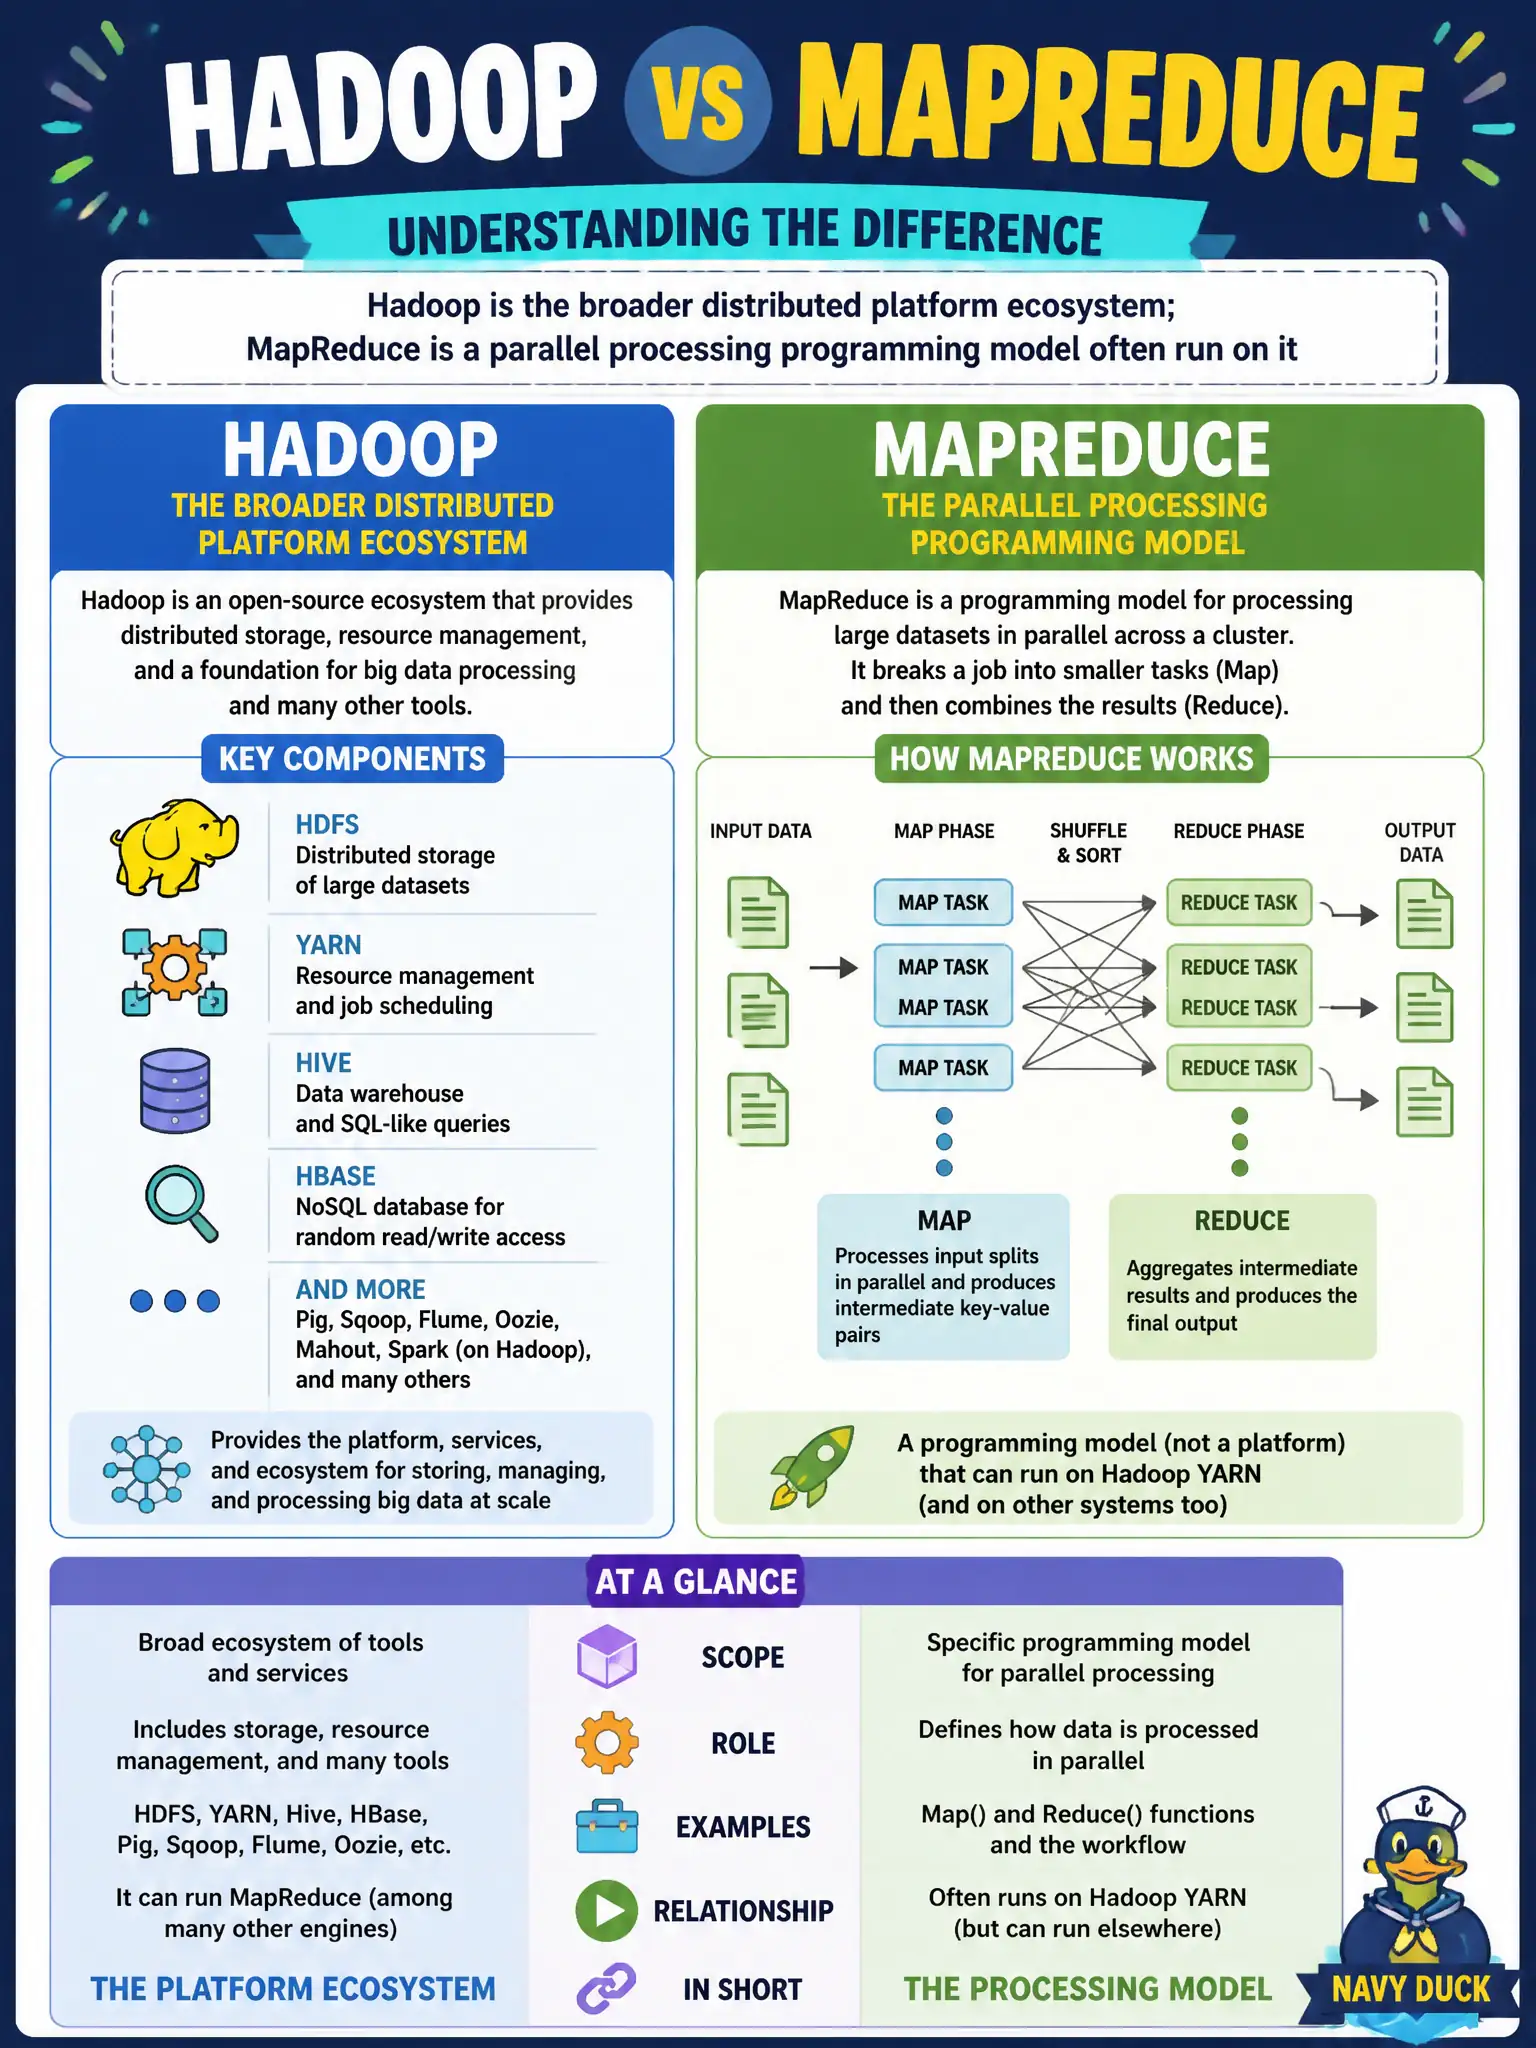
Hadoop is the neighborhood; MapReduce is one popular way the work gets done on those streets. Same zip code, not the same building.
Full Explanation
BDPC-oriented explanations separate Hadoop from MapReduce clearly: Hadoop is the broader distributed platform ecosystem spanning storage, resource management, and related projects, while MapReduce is a parallel processing programming model often executed on that platform. Same neighborhood, different buildings—staff should not treat the words as synonyms in architecture reviews or runbooks. MapReduce is not the entire Hadoop ecosystem, and HDFS is not unrelated; distributed storage is a core Hadoop concern that MapReduce jobs typically read and write. MapReduce does not only store files while Hadoop only draws dashboards; that claim inverts and confuses storage, processing, and presentation roles. The terms are not interchangeable trademarks for the same single daemon process on a cluster. Exam caveat: candidates lose points when they treat Hadoop as identical to MapReduce or forget HDFS and YARN as distinct concerns within the ecosystem. Operational check: in runbooks and training, label jobs as MapReduce or Spark processing on a Hadoop cluster with HDFS storage, quiz operations staff to name storage versus processing components, and correct slideware that collapses the terms before it reaches council or auditors.