
A blood-bank nightly label job in Azure Container Instances must run once and stay stopped on success, but should retry if the process exits non-zero. Which restart policy matches that contract?
Select an answer to reveal the explanation.
Short Explanation
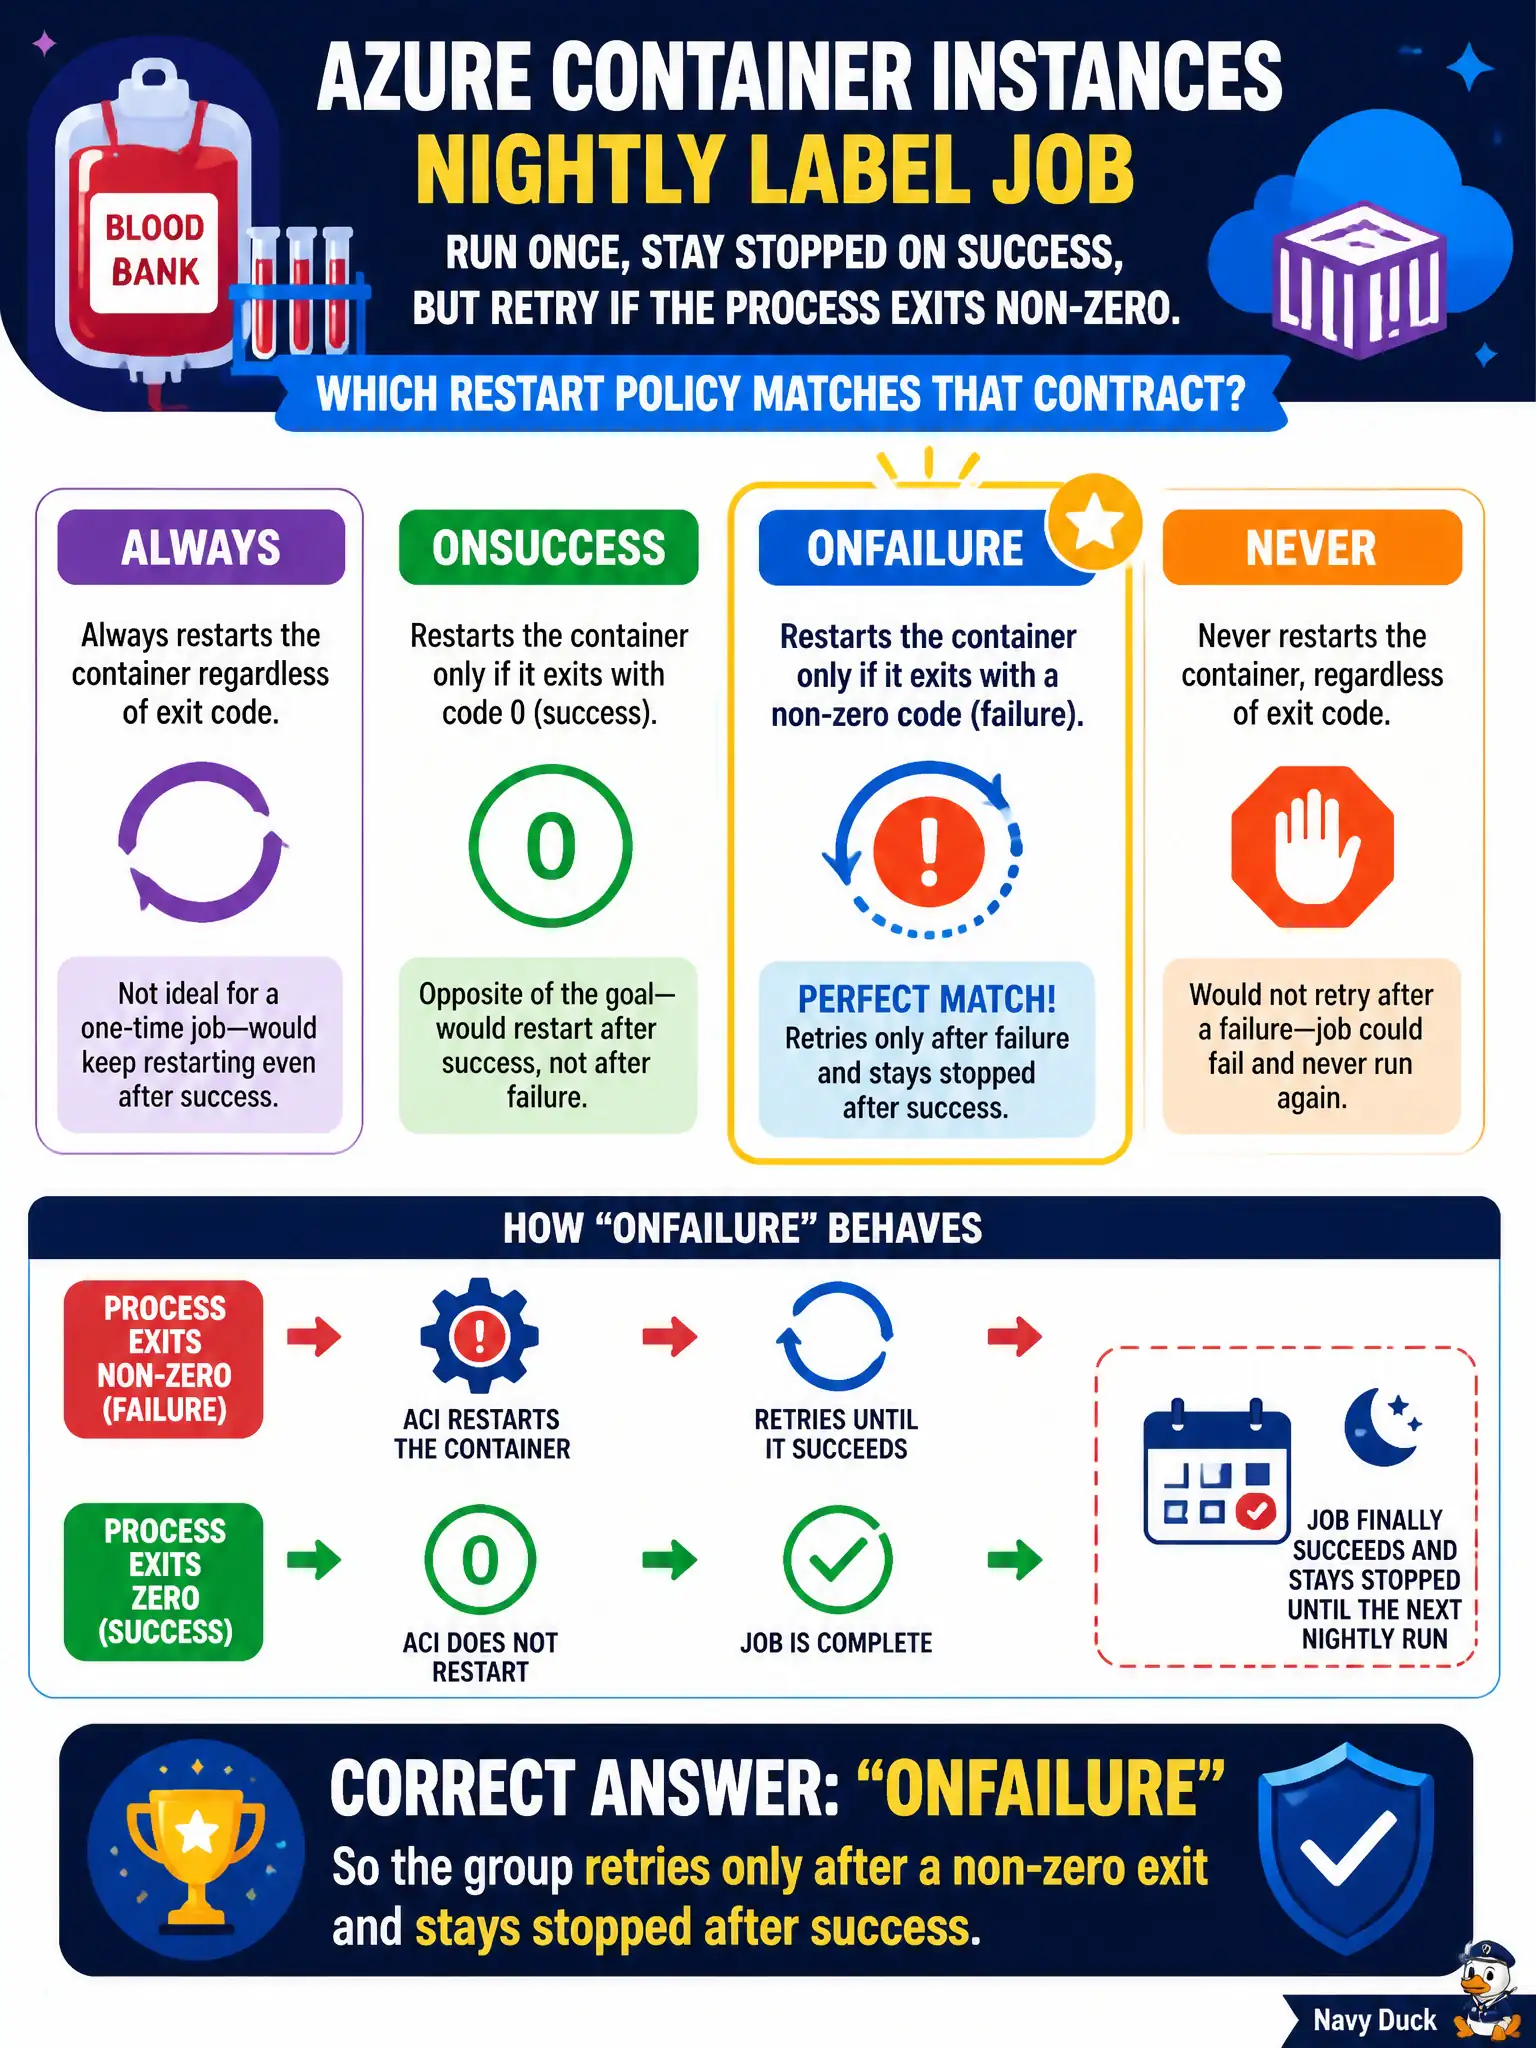
Always is a night watchman who never clocks out. Never walks away even after a crash. OnFailure is the sensible lab tech: try again when the run fails, hang up the coat when it succeeds.
Full Explanation
Batch jobs that should retry on failure but stop after success use the OnFailure restart policy on Azure Container Instances. When the municipal lab process exits with a non-zero code, the container group restarts and tries again; when it exits zero, the group remains stopped. That contract matches “retry the bad run, hang up the coat after a clean finish” without turning the batch into a forever daemon.
Always keeps restarting even after a successful exit, which converts a finite job into an endless loop and can re-process completed work indefinitely. Never leaves even a failed exit stopped with no automatic retry, so every transient error needs a human to start the group again. Unless-stopped is a Docker Engine restart policy familiar from local daemons; ACI’s supported restart policies for this exam framing are Always, OnFailure, and Never—not unless-stopped as a batch default.
Exam caveat: restart policy applies at the container/group level ACI exposes; sidecar containers that exit unexpectedly can influence overall group health—keep one-shot batch groups simple or align companion exit codes with the same success contract.
Operational check: deploy a test group with OnFailure, force a non-zero exit once and confirm events show a restart, then force a zero exit and confirm the group stays stopped with no further restarts.