
A travel company launches a Bedrock chatbot that summarizes bookings and calls tools to refund tickets. Testers bypassed safety prompts with jailbreaks, leaked PII in outputs, and triggered disallowed refund actions. Which generative AI guardrail control mitigates prompt injection and unsafe tool use?
Select an answer to reveal the explanation.
Short Explanation
Your bot is a bit too trusting and needs firm house rules. Bedrock Guardrails filters nasty prompts and scrubs PII before answering.
Full Explanation
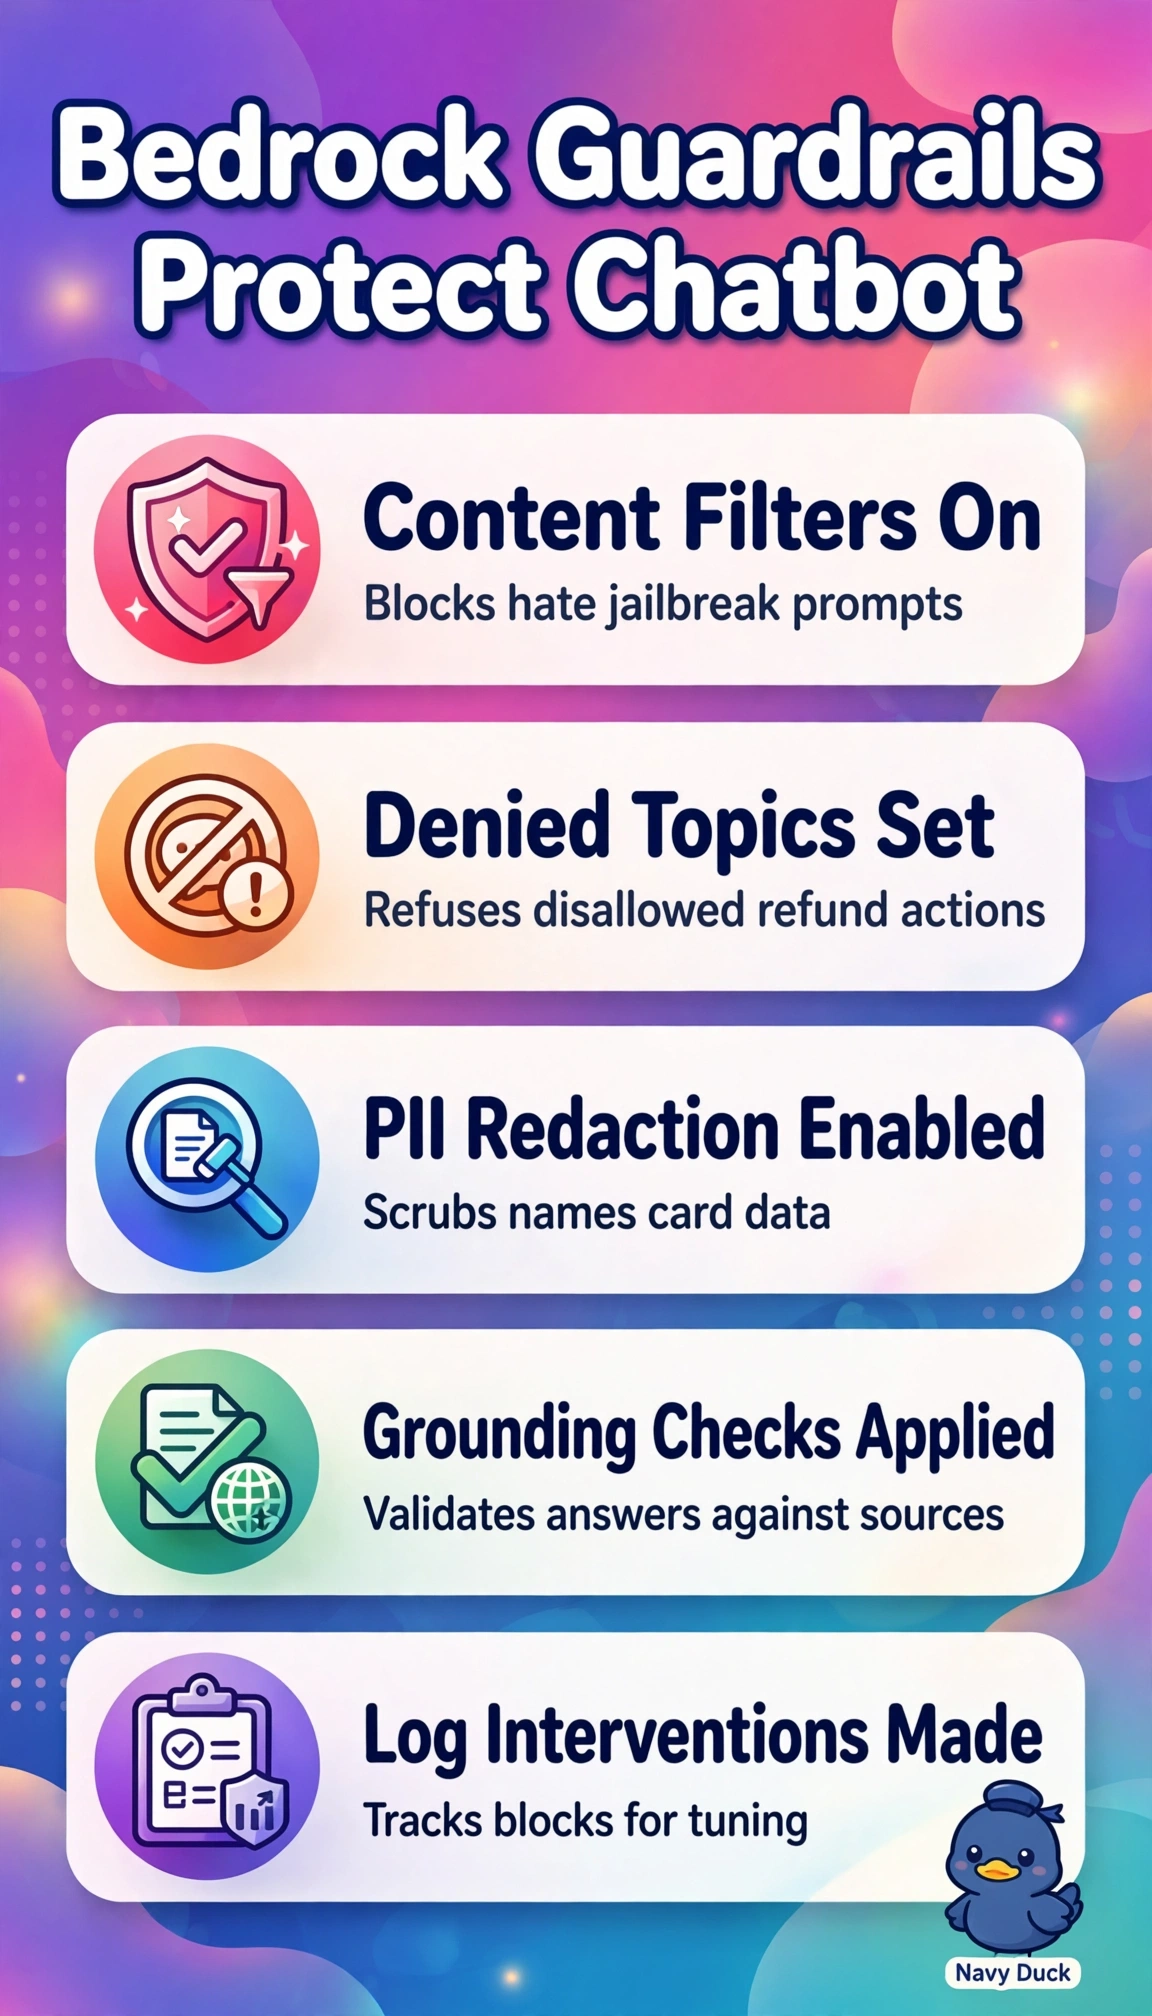
The correct control applies Bedrock Guardrails as an independent policy layer that evaluates user inputs and model outputs, combining denied topics to block disallowed refund workflows, prompt attack and jailbreak filters to neutralize injection, PII redaction to prevent leakage in outputs, content filters for harmful content, and contextual grounding checks to keep booking summaries faithful to source data, which directly maps to all three tester findings. Strengthened system prompts sound like best practice but fail because instructions live inside the model context and can be overridden by the same jailbreak techniques reported, offering no deterministic enforcement outside inference. Least-privilege IAM with auditing is essential for limiting blast radius of the refund function and provides detective value, yet it operates at API authorization and cannot inspect or transform natural language prompts and completions for injection, PII, or grounding. Knowledge Bases retrieval improves factual consistency by anchoring summaries to booking records, but retrieval alone provides no policy to redact PII, block denied refund intents, or filter jailbreak attempts. On exams, distinguish model instructions and data plumbing from dedicated safety enforcement that evaluates both inputs and outputs even when prompts are adversarial, while IAM least privilege on the refund tool remains a complementary control. In practice, verify by replaying the reported jailbreak prompts, PII probe utterances, and refund edge cases in a staging agent with guardrail traces and blocked-content metrics enabled to confirm intervention before production deployment.