
A fintech runs payment workers on ECS Fargate behind an ALB and needs early warning for task crashes, target health shifts, and queue backlogs before customer impact. Leadership wants health-aware dashboards with paging only on actionable failures. Which workload monitoring strategy best provides resource health visibility?
Select an answer to reveal the explanation.
Short Explanation
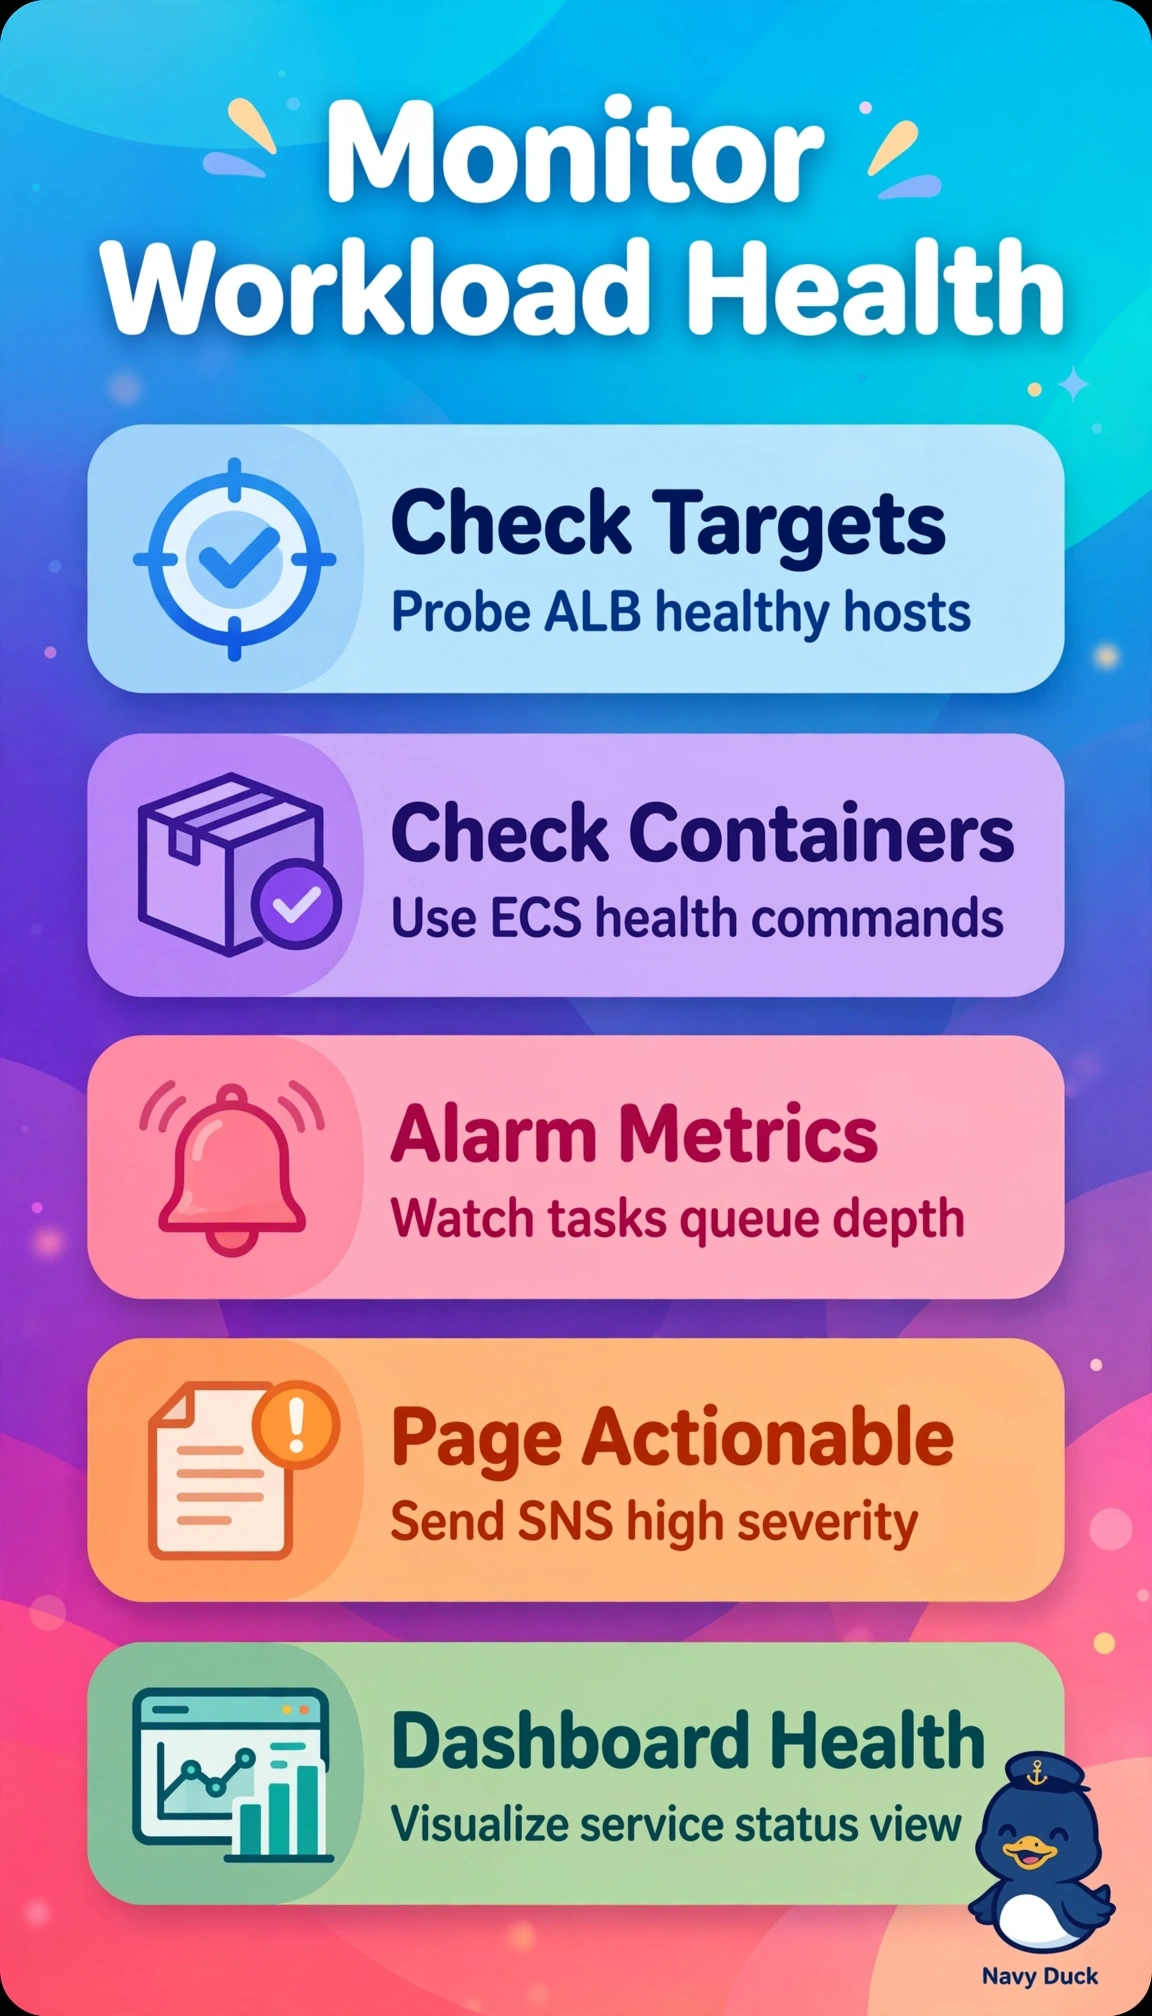
You can catch task crashes, target health changes, and queue buildup early by combining ALB target health, ECS checks, and queue-backlog alarms. Selective SNS paging keeps your team focused on failures that need action while dashboards show workload health.
Full Explanation
Combining ALB target health, ECS checks, and queue-backlog alarms works because ALB target health reveals target shifts and routing failures, ECS checks surface task crashes and restart loops, and backlog alarms signal saturation before customer latency rises. Sending SNS pages only for actionable failures keeps alerts useful while dashboards show workload health. The strategy with ALB target health, Container Insights, dashboards, and selective paging fails to provide the same early warning because rich dashboards and selective paging cannot replace queue-depth and message-age alarms; without them, you may discover buildup through customer latency rather than an early signal. The strategy that pages on all warning and informational events fails because alert fatigue can bury real failures and conflicts with the requirement to page only when action is needed, even though its health checks and backlog alarms provide coverage. The strategy with ECS service health, backlog alarms, operational dashboards, and selective paging fails to provide load-balancer visibility: without ALB target health, it can miss failed health checks, deregistration, or AZ imbalance, leaving tasks apparently healthy while no healthy targets can serve traffic. Exam caveat: dashboards and Container Insights aid triage but do not provide early warning on their own; alarms, thresholds, and a notification policy are also needed. Practical check: verify ALB healthy and unhealthy host counts, ECS running versus desired count and deployment events, and queue backlog per task plus oldest-message age, with severity-filtered SNS notifications, before go-live.