
A healthcare startup launches a Bedrock-powered triage chatbot that summarizes patient messages and calls Lambda tools. Pen tests show prompt injection can override safety instructions and elicit disallowed medical advice, plus sensitive data leaks into outputs. The app already uses IAM and KMS encryption. Which generative AI guardrail addresses OWASP LLM prompt injection and sensitive-data disclosure?
Select an answer to reveal the explanation.
Short Explanation
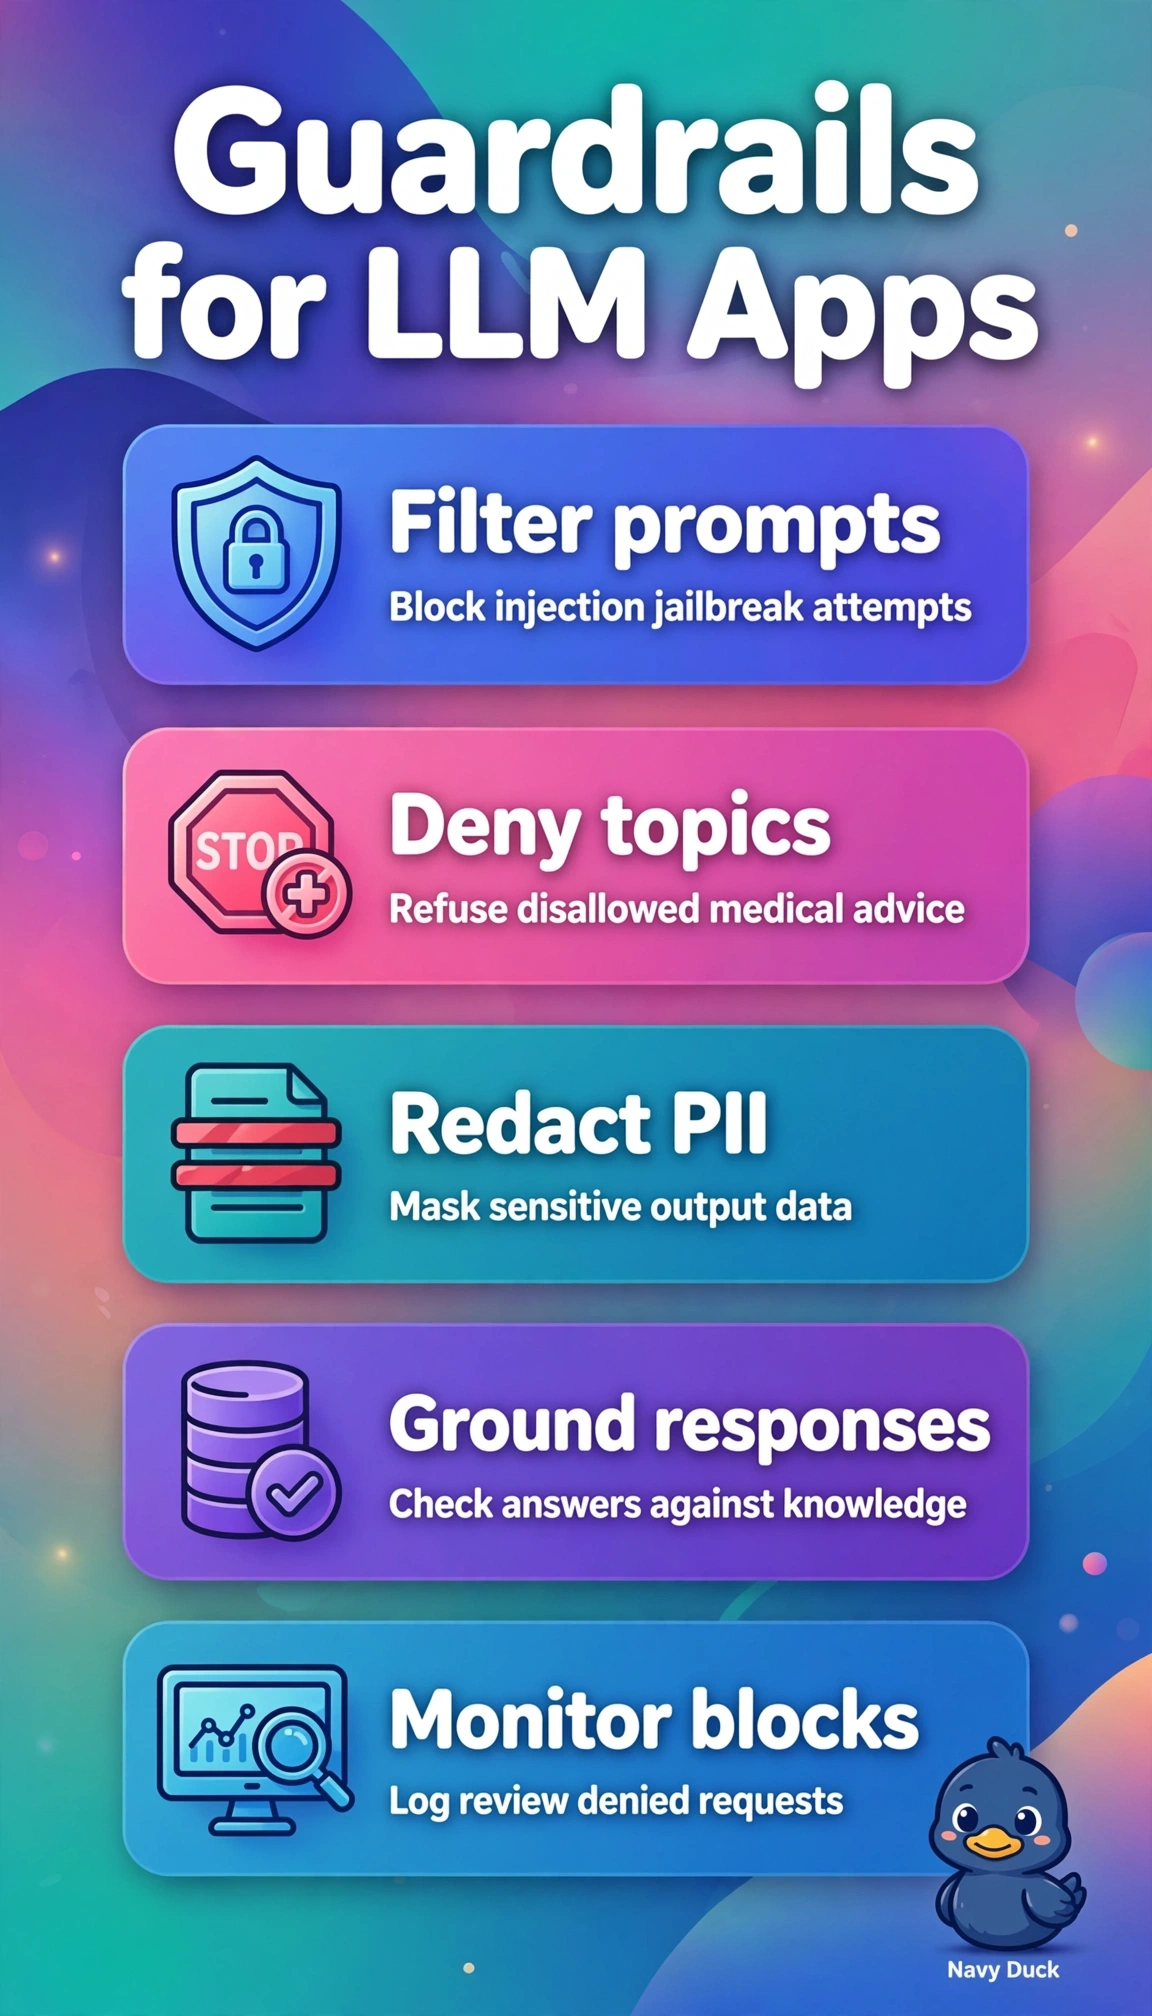
You need a content bouncer inside the model flow, not just locks outside. Bedrock Guardrails screens prompts and answers for attacks, banned topics, and PII.
Full Explanation
The correct control is Amazon Bedrock Guardrails because it enforces inline policies on both inputs and outputs, where prompt-attack filters detect injection and jailbreak attempts to override safety instructions, denied topics refuse disallowed medical advice, and sensitive-information redaction removes PHI before delivery, directly addressing OWASP LLM risks for prompt injection and sensitive-data disclosure beyond what IAM authorization and KMS encryption provide. The WAF with KMS-encrypted inputs fails by layer because WAF matches web signatures at the edge and KMS protects confidentiality at rest and in transit, so neither interprets model instructions nor reliably blocks semantic overrides or redacts generated summaries. The Comprehend with disclaimer approach fails by completeness because it can identify PII in outputs but provides no input-side attack filtering and no enforced topic denial, leaving injection-driven overrides unhandled while a static warning does not block or transform content. The IAM with auditing and human review approach fails by timing because least privilege, CloudTrail history, and sampled clinician checks give detective governance after execution but cannot intercept and rewrite malicious prompts or leaking completions in real time at scale. For exams, do not conflate network, identity, encryption, or logging controls with AI content guardrails, especially when the stem states IAM and KMS already exist and asks for preventive prompt and disclosure protection. As a practical check, pilot Guardrails with crafted jailbreaks, disallowed triage questions, and synthetic PHI and verify blocked and redacted interventions on both input and output via test playground and monitoring metrics.