
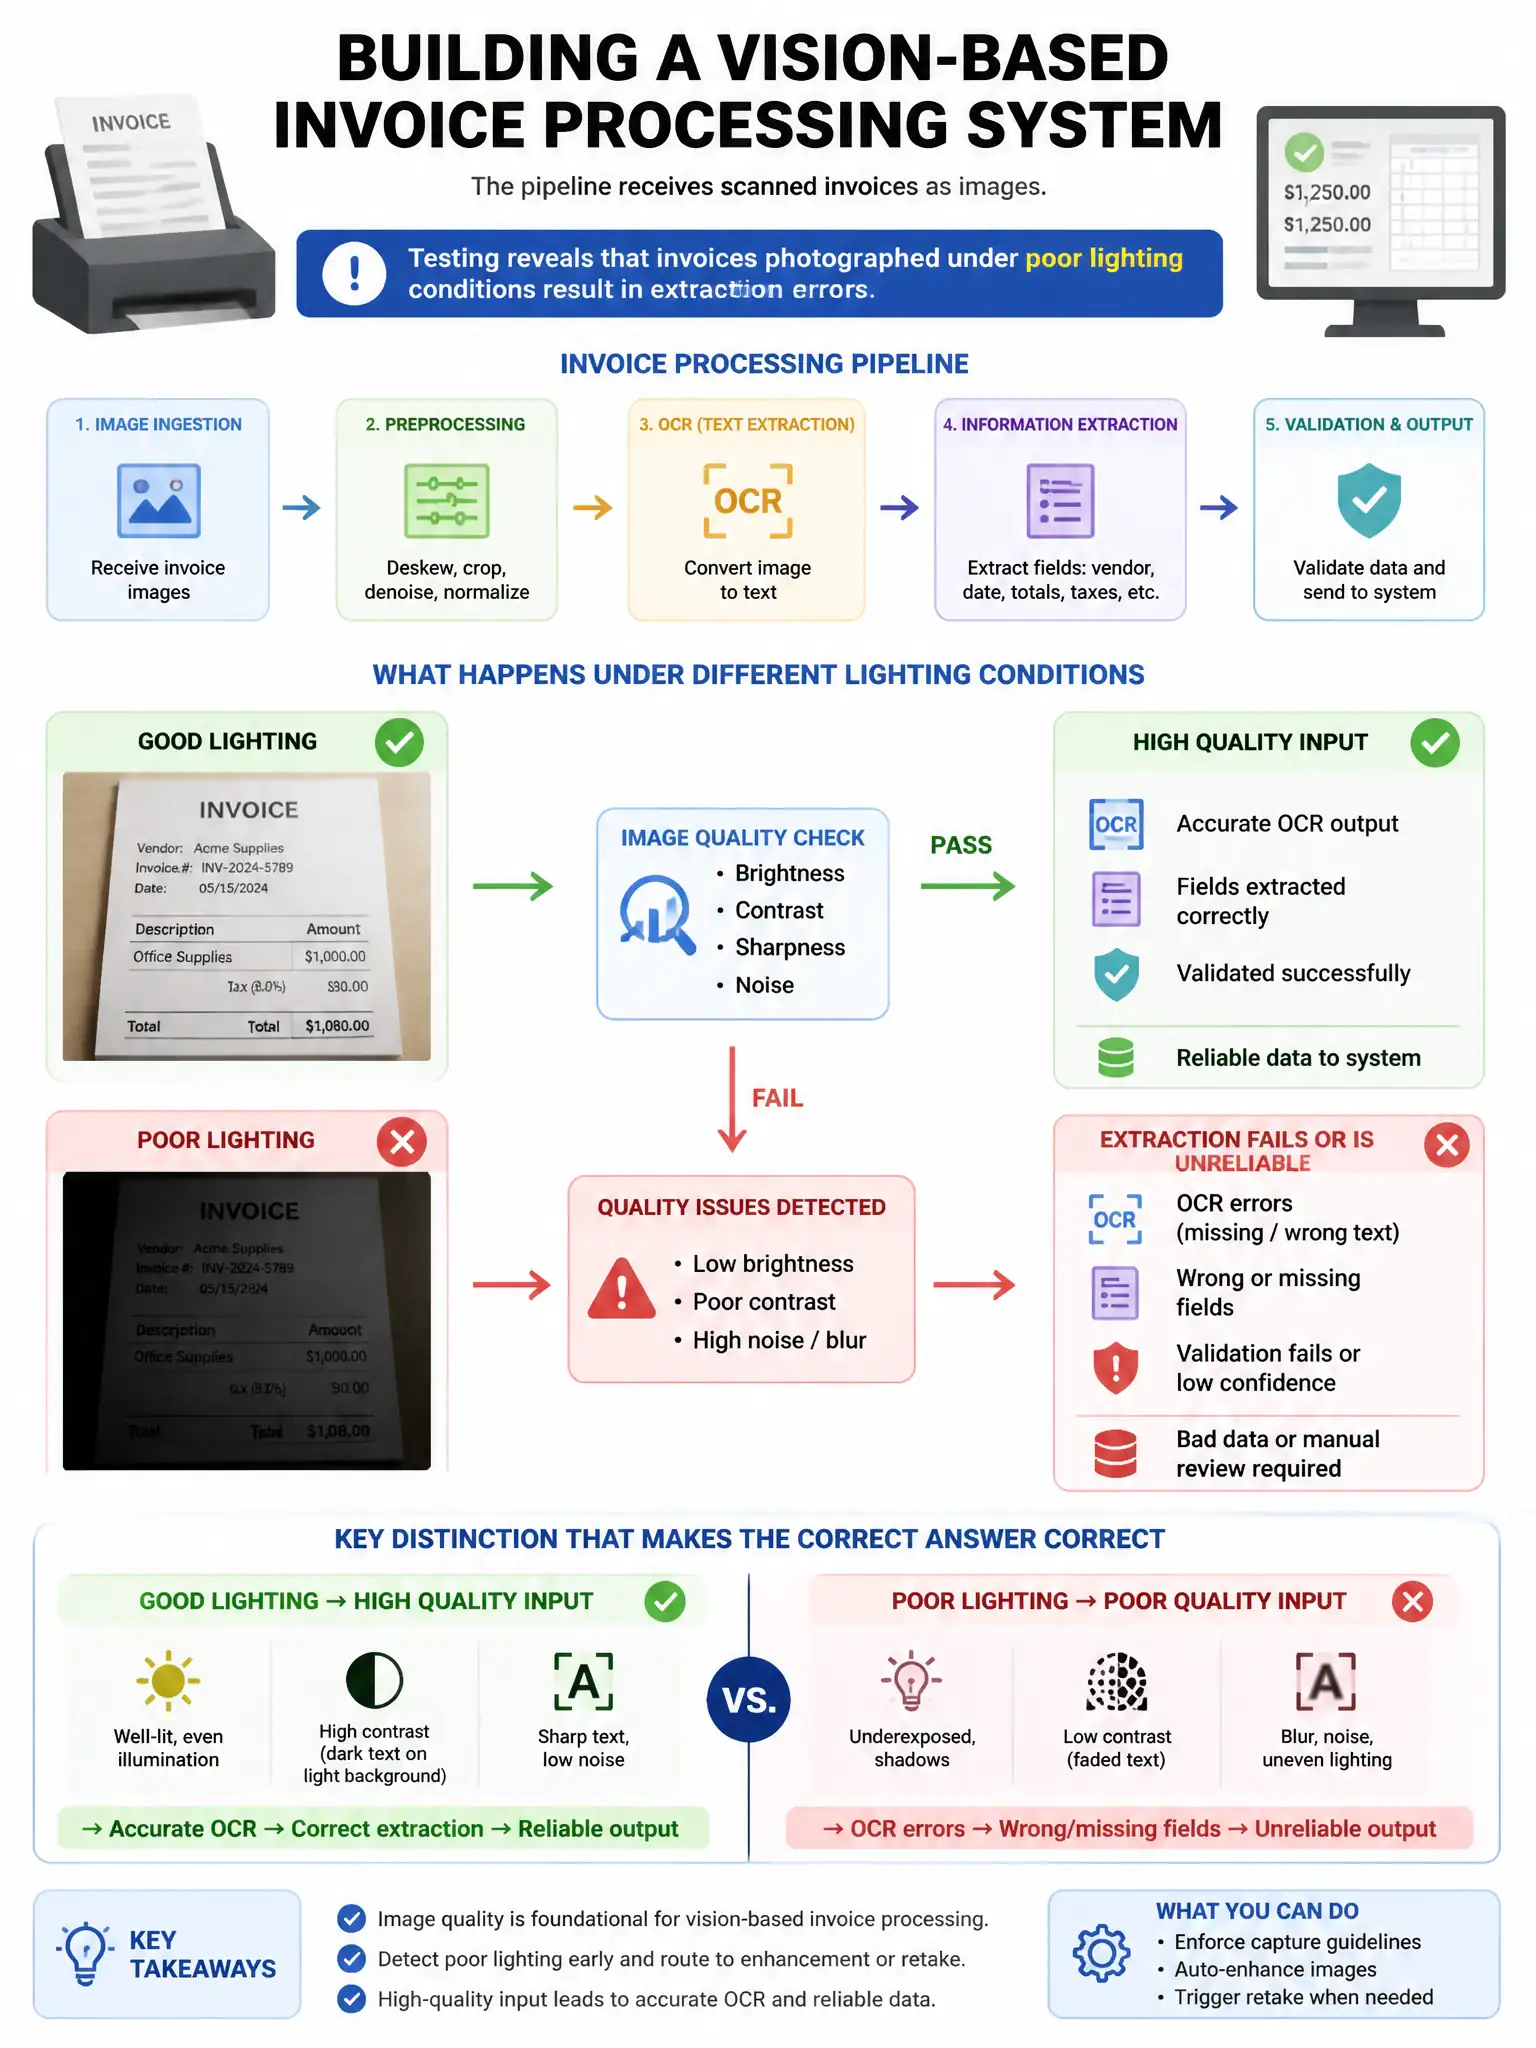
You are building a vision-based invoice processing system. The pipeline receives scanned invoices as images. Testing reveals that invoices photographed under poor lighting conditions (high contrast shadows, overexposed regions) result in significantly lower extraction accuracy. Before sending images to Claude's vision API, what preprocessing should the architect implement?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — normalize the image before you send it. CLAHE fixes local contrast, deskewing straightens the document, and enough DPI keeps characters legible, so Claude isn't guessing through bad lighting.
Full Explanation
The correct approach is to apply adaptive histogram equalization (CLAHE) to normalize contrast across regions, correct skew using detected document edges, and ensure the image is at an appropriate resolution (at least 150 DPI for text legibility) before submission. The described failures — high contrast shadows and overexposed regions — are image quality problems that preprocessing can directly mitigate. CLAHE normalizes local contrast without globally washing out the image. Skew correction ensures text orientation is consistent. Minimum resolution (150+ DPI for text) ensures characters are legible at the pixel level. These are standard document image preprocessing steps that have a direct, measurable impact on OCR and vision model accuracy. Converting all images to grayscale is wrong because it eliminates color information that can be useful for distinguishing printed text from stamps, logos, or highlighted fields on colored invoice templates — and it does not address the lighting normalization problem. Sending multiple exposures of the same invoice and averaging Claude's extractions across them is wrong because it requires multiple API calls per invoice, multiplying cost and latency, and averaging extractions from a poorly exposed original with other poorly exposed variants does not correct the root problem. Increasing Claude's temperature parameter to 0.5 is wrong because temperature controls output sampling randomness and has no effect on how the model perceives visual content — increasing temperature would make extractions less consistent, not more accurate.