
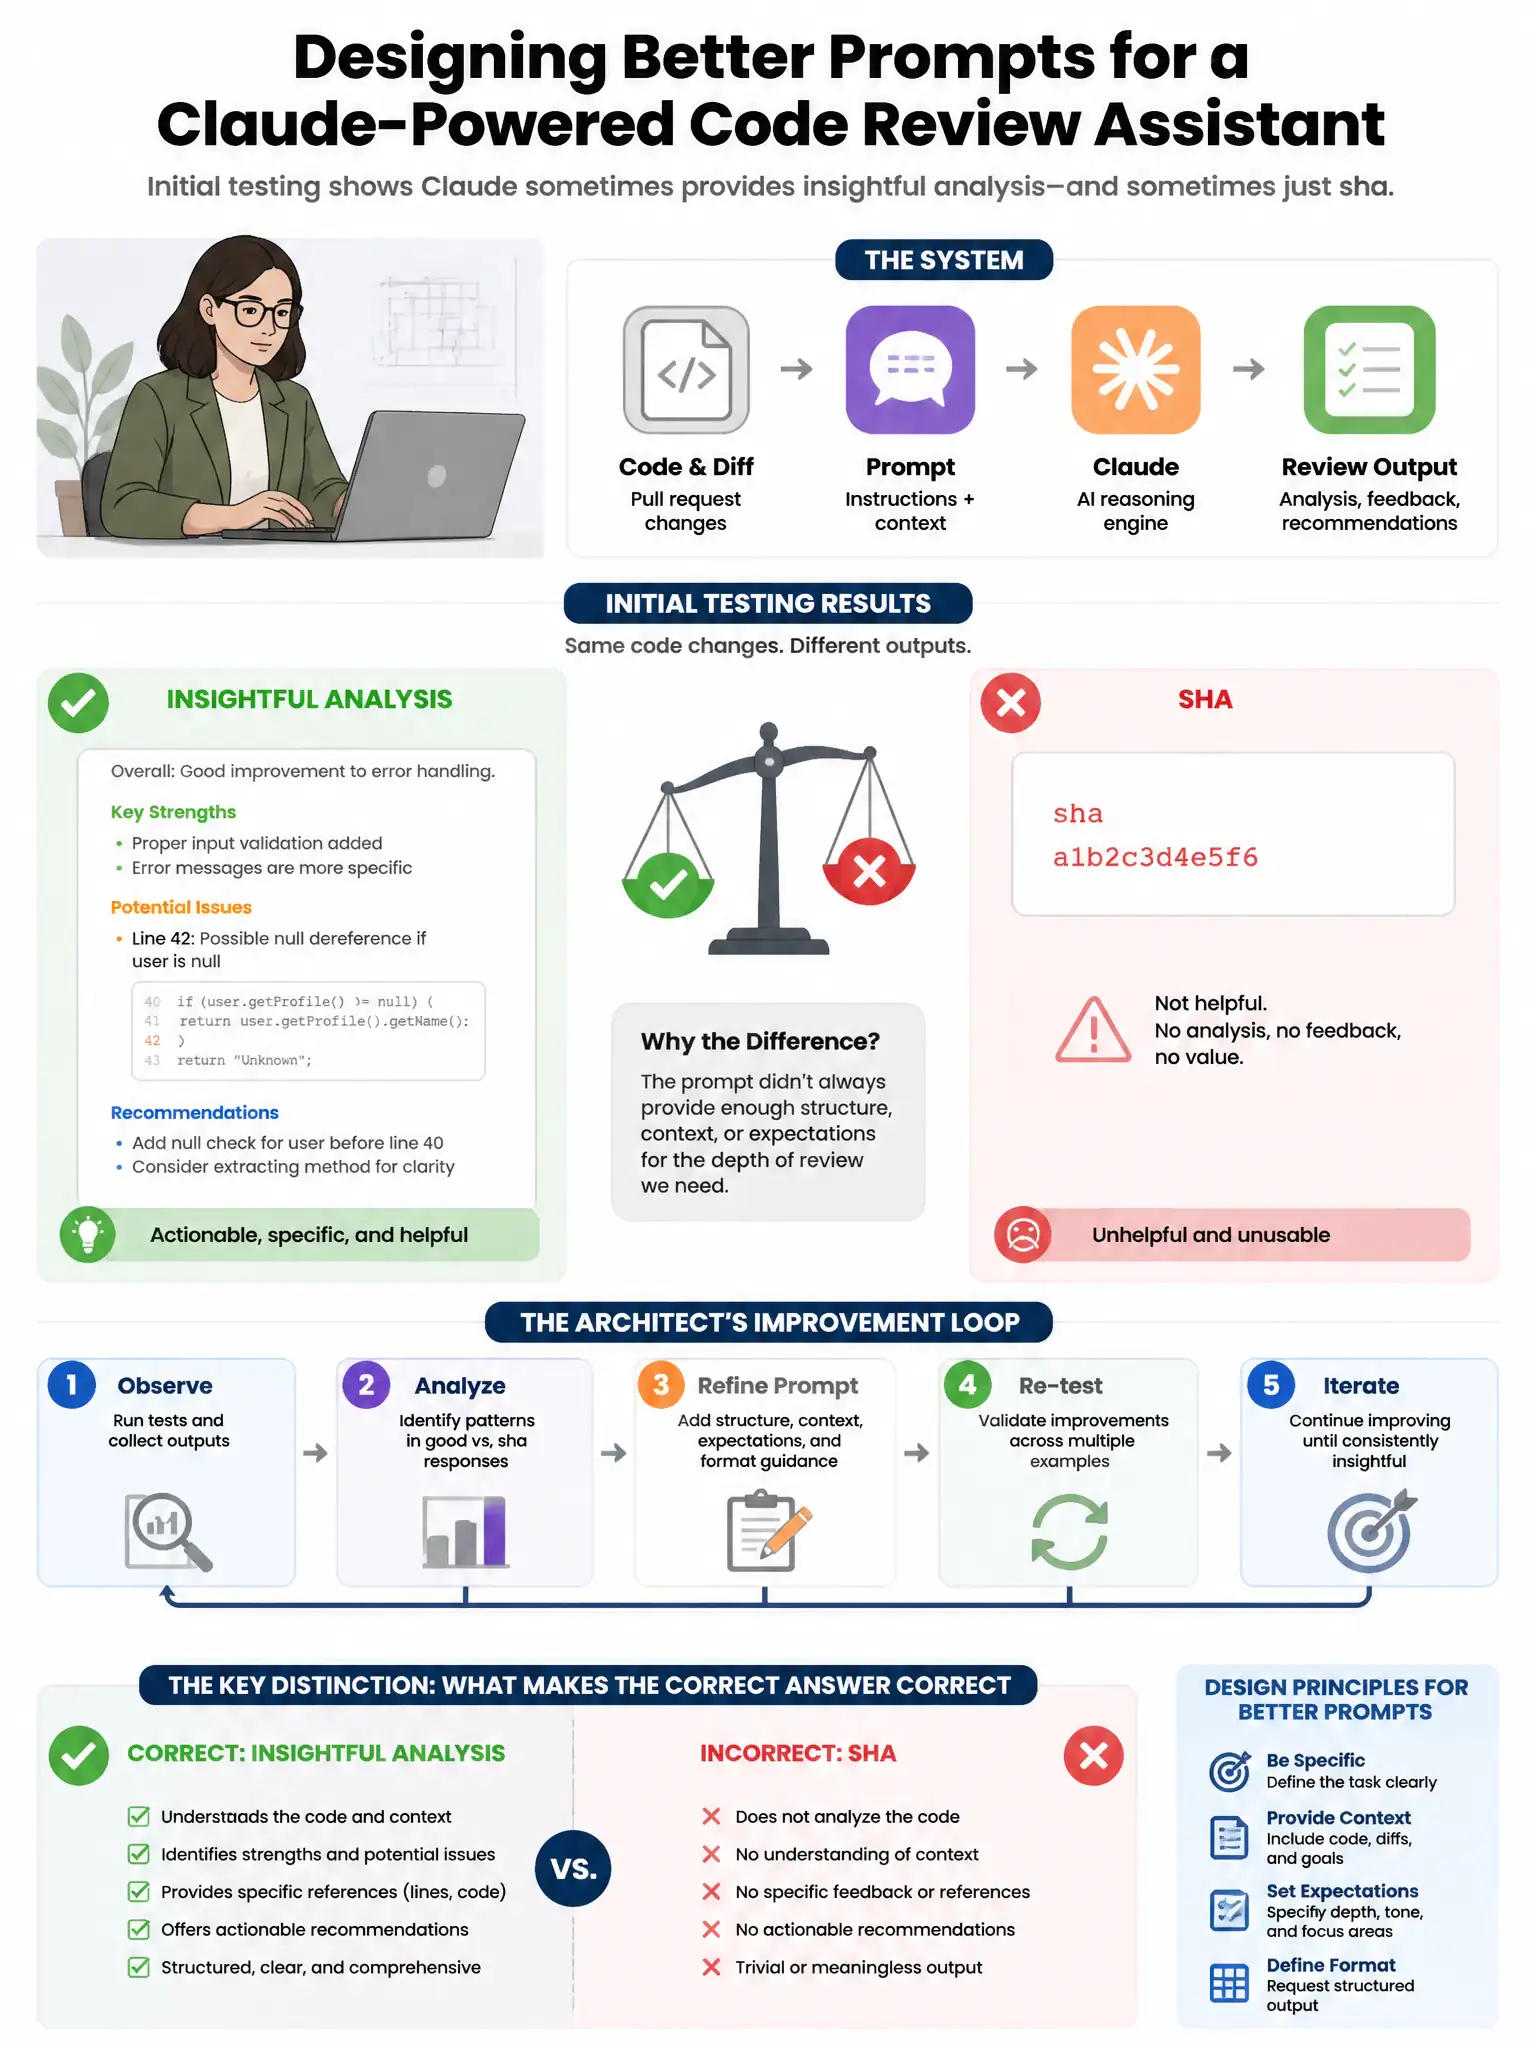
An architect is designing prompts for a Claude-powered code review assistant. Initial testing reveals that Claude sometimes generates insightful analysis and sometimes produces shallow bullet-point summaries of the same code. The temperature is set to 0.7. What prompt engineering approach most reliably improves response depth consistency?
Select an answer to reveal the explanation.
Short Explanation
You need structure, not just temperature tweaks. Required sections with depth criteria give Claude a template to fill, and a negative shallow example shows what to avoid. That keeps reviews consistently deep instead of collapsing into bullet points.
Full Explanation
The explicit output structure approach is correct because response depth inconsistency is a structural problem best solved with structural constraints. Defining required sections, such as Security Vulnerabilities, Performance Concerns, and Code Quality, with minimum depth criteria creates a template that Claude fills consistently, preventing the collapse into shallow bullet points. Including a negative example of a shallow response explicitly teaches Claude what not to do, which is particularly effective for preventing known failure modes. The temperature-lowering approach is wrong because shallow responses at temperature 0.7 are not primarily a sampling temperature problem — they are a structural guidance problem. Temperature reduction would make outputs more consistent but would not inherently make them deeper without structural scaffolding. The longer-system-prompt approach is wrong because more domain knowledge in the system prompt does not guarantee depth — it gives Claude more material but does not constrain how that material is applied in responses. The majority-voting approach is wrong because selecting the longest response conflates verbosity with depth and creates unnecessary API cost; a structurally guided single call is more reliable than five unguided calls.