
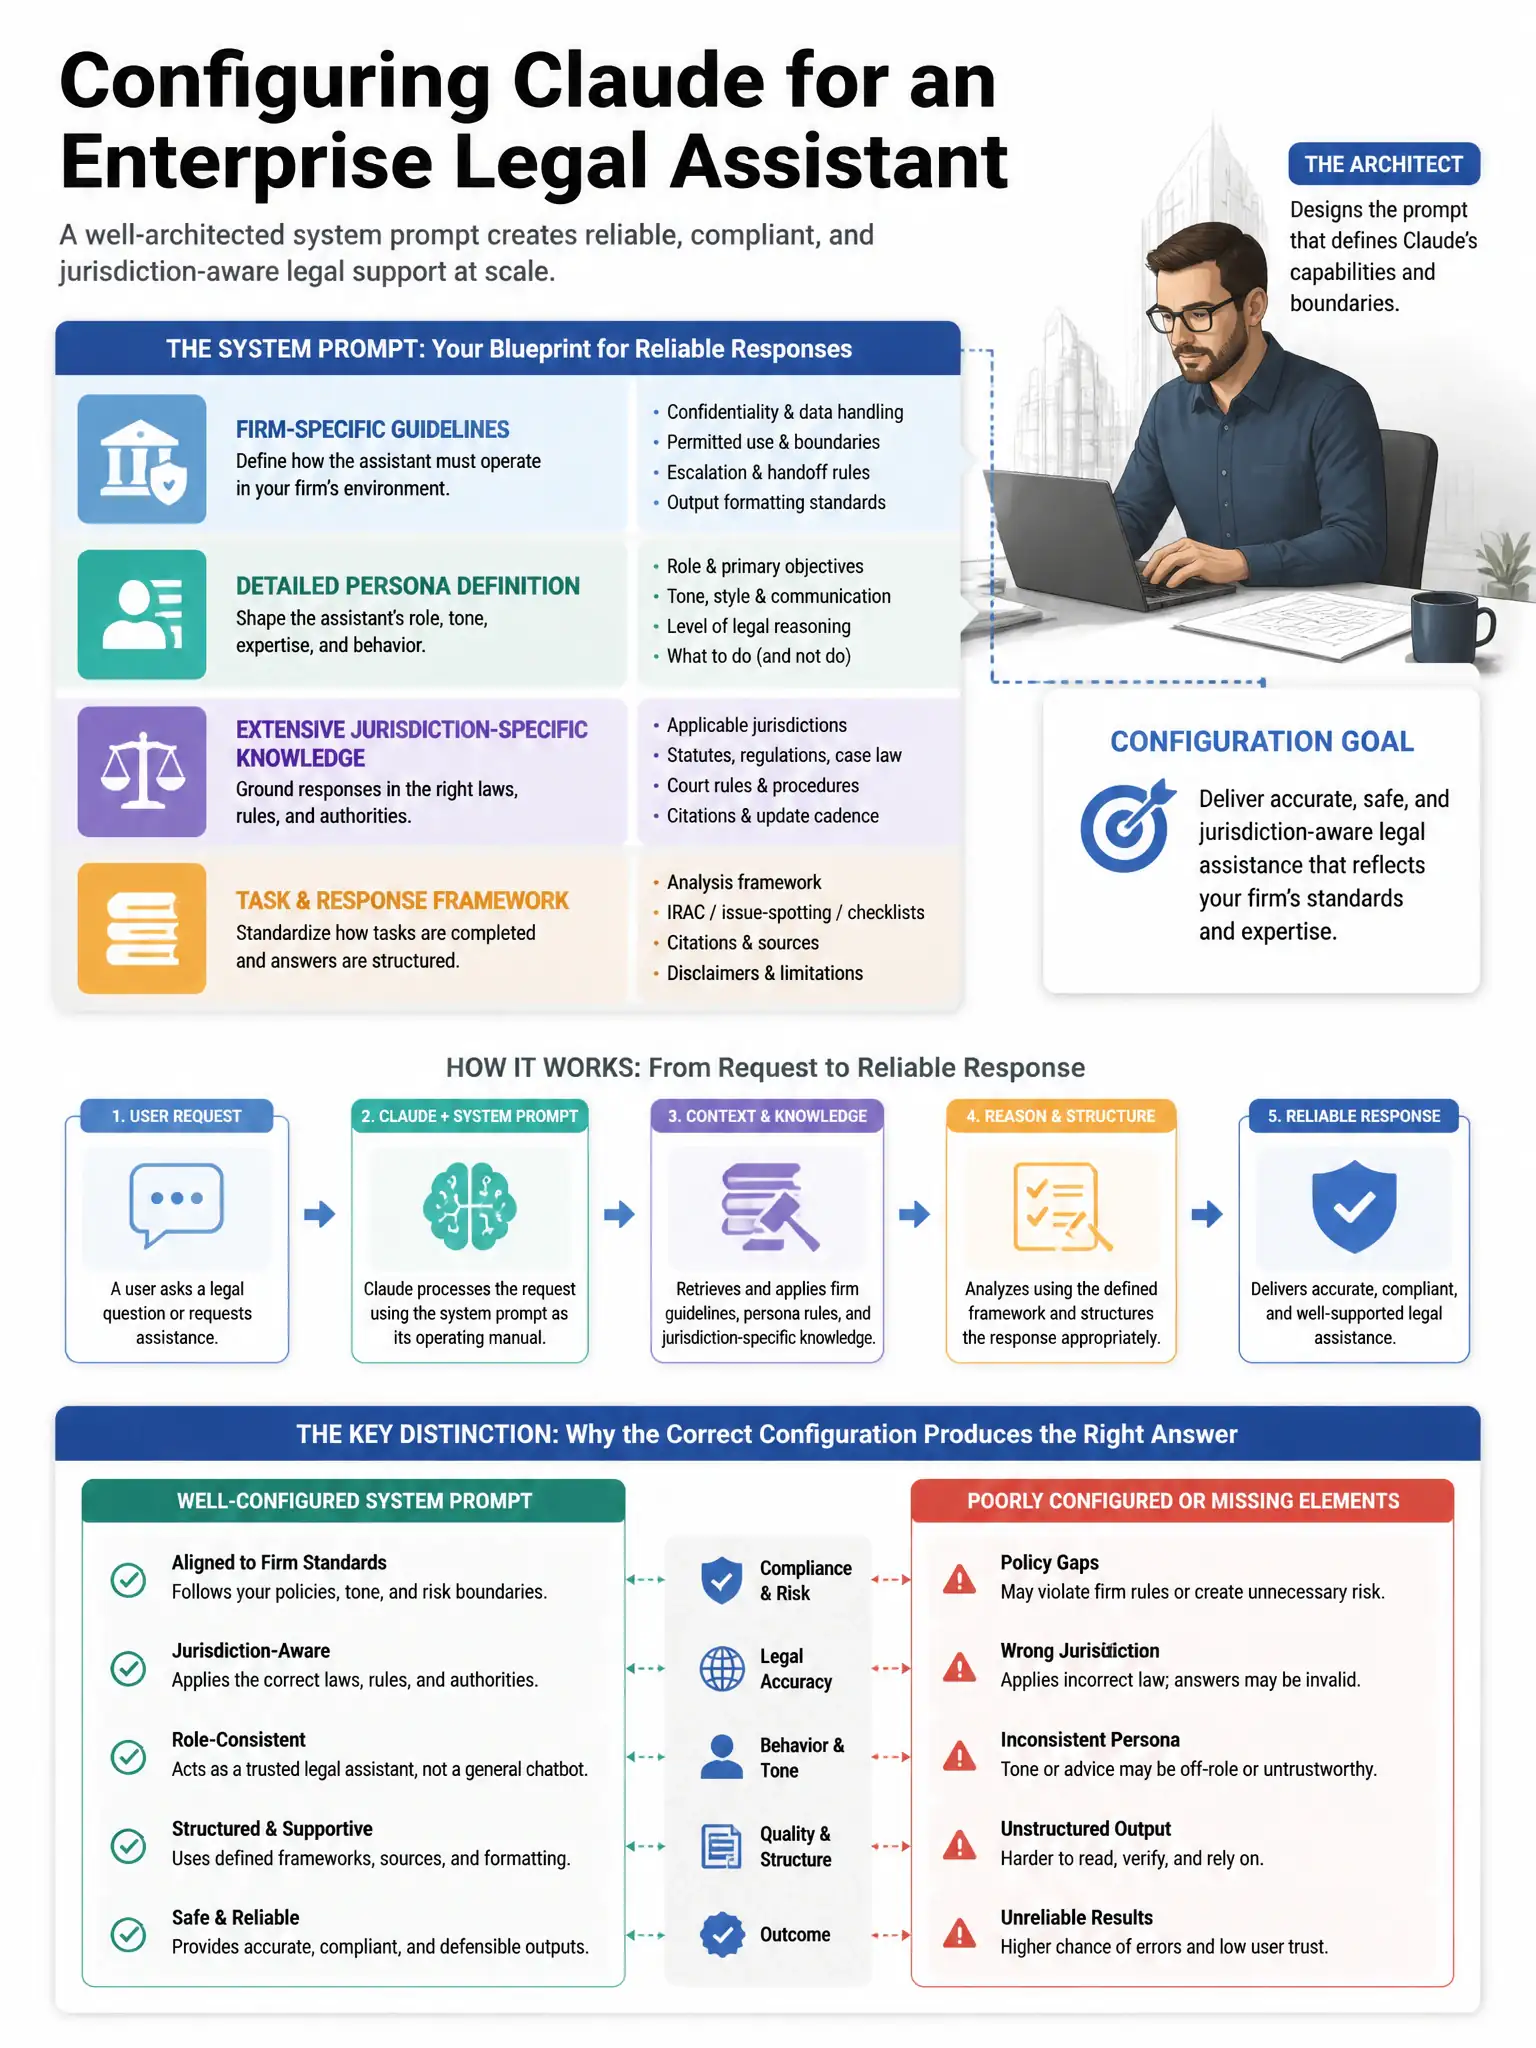
An architect is configuring Claude for an enterprise legal assistant. The system prompt contains firm-specific guidelines, a detailed persona definition, extensive jurisdiction-specific rules, formatting instructions, and a 50-document knowledge base excerpt. The combined system prompt is 28,000 tokens. The team observes that some instructions toward the end of the system prompt are being inconsistently followed. What is the most likely cause and correct remediation?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — long-context attention is not uniform. You'll see reduced attention to content in the middle of very long prompts, so put critical behavioral rules at the top and end, and move knowledge-base content to retrieval-augmented generation.
Full Explanation
The correct cause is that instructions in very long system prompts suffer from the lost-in-the-middle attention degradation pattern. At 28,000 tokens, the model can attend unevenly, and instructions toward the end can be inconsistently followed because attention is reduced in the middle of very long prompts. Placing critical behavioral rules at the top and end exploits primacy and recency effects. Moving the 50-document knowledge-base excerpt to retrieval-augmented generation is the correct architectural fix because it converts static embedding into dynamic retrieval and frees system-prompt space for instructions. The claim that the system prompt has exceeded maximum allowed size because Anthropic enforces hard 20,000-token system-prompt limit is wrong; Anthropic does not enforce such hard limit, and truncation behavior would not match described symptom of inconsistent following rather than consistent omission of specific block. The claim that the system prompt should be split across multiple system-role messages in the messages array is wrong because the Anthropic Messages API accepts only one system-role message; there is no multi-system-message architecture in the Messages API. The recommendation to increase temperature to 0.0 is wrong because temperature controls output randomness and has no effect on which parts of system prompt the model attends to.