
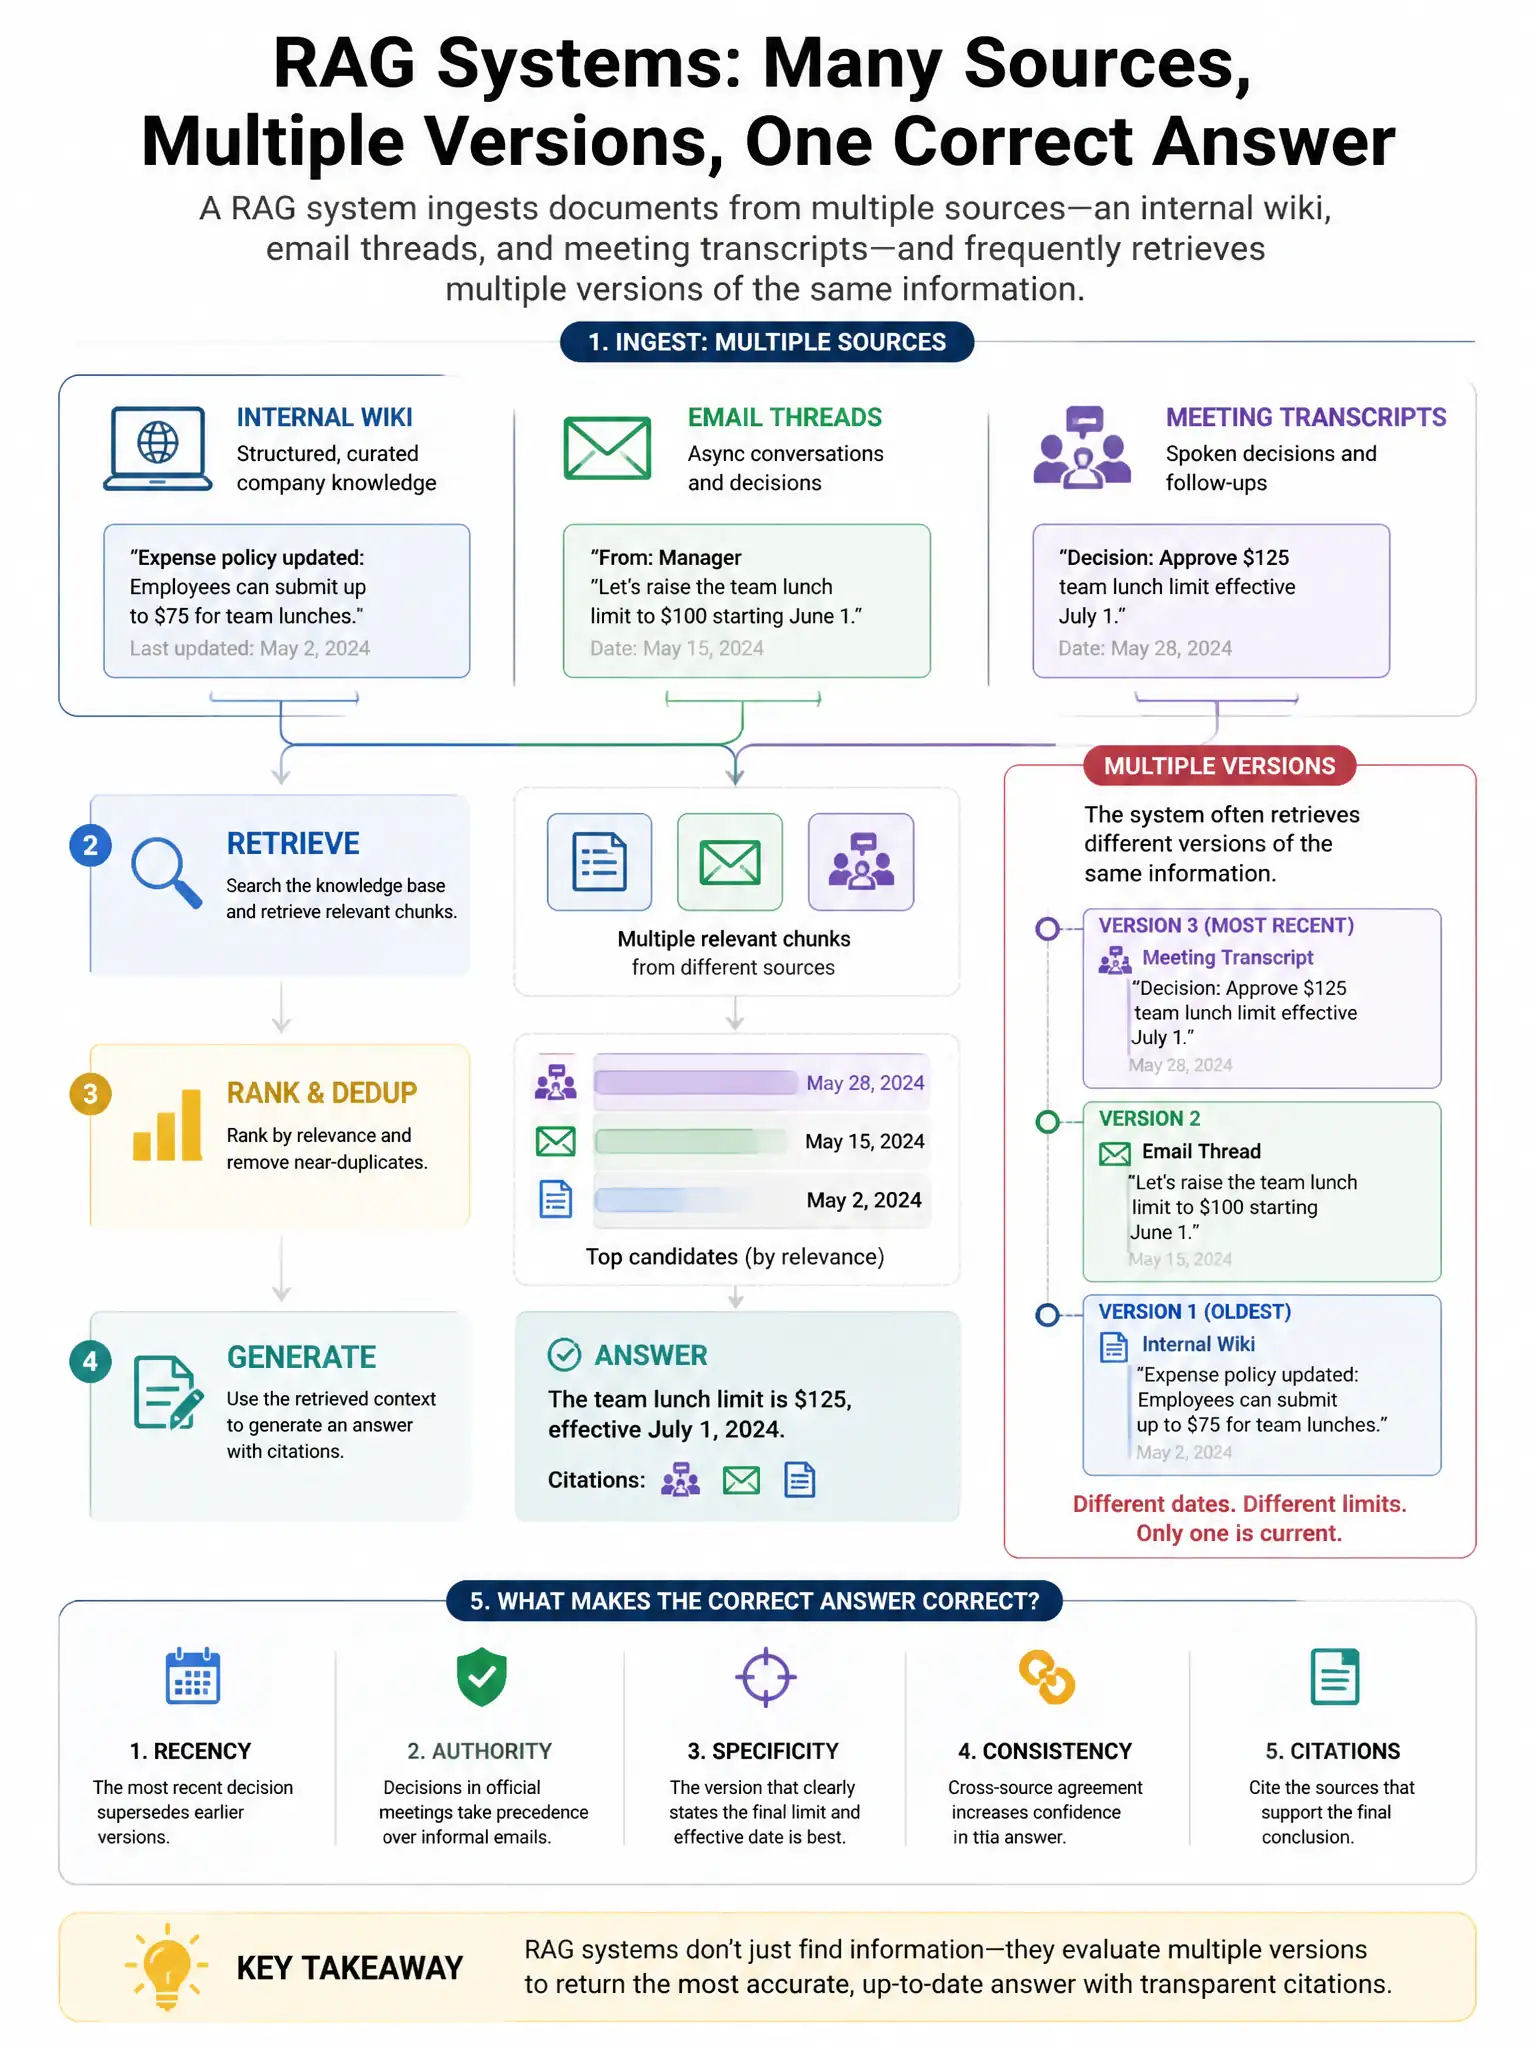
A RAG system ingests documents from multiple sources: an internal wiki, email threads, and meeting transcripts. The system frequently retrieves multiple versions of the same information (e.g., an email summarizing a meeting that is also in the transcript). This duplication causes Claude to give over-weighted responses emphasizing duplicated points. What deduplication strategy should the architect implement?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need near-duplicate detection with MinHash/LSH before indexing, then MMR at retrieval time to penalize chunks that repeat what's already selected. That stops duplicate content from bloating the index and from skewing Claude's context.
Full Explanation
The correct strategy is near-duplicate detection using MinHash/LSH on document shingles before indexing, combined with maximum marginal relevance (MMR) at retrieval time. Pre-indexing near-duplicate detection removes nearly identical documents before they enter the index, reducing index bloat. MMR at retrieval time handles cases where near-duplicates pass pre-indexing dedup by adding diversity to the retrieved set, penalizing documents that add little new information to the already-selected set. Together, these prevent duplicate information from both entering the index and appearing in the retrieved context. Exact string matching before indexing is wrong because it misses near-duplicates with minor formatting differences, different headers, or paraphrased content; an email summary and a meeting transcript can cover identical information without sharing exact strings. Storing only one source type, such as wikis only, and discarding emails and transcripts is wrong because it loses information unique to those sources; emails may contain decisions not in transcripts, and context from multiple sources is a feature, not a problem. Post-processing Claude's response to remove repeated points is wrong because it does not prevent the over-weighting from happening during generation; Claude has already over-weighted the duplicated information when forming its response.