
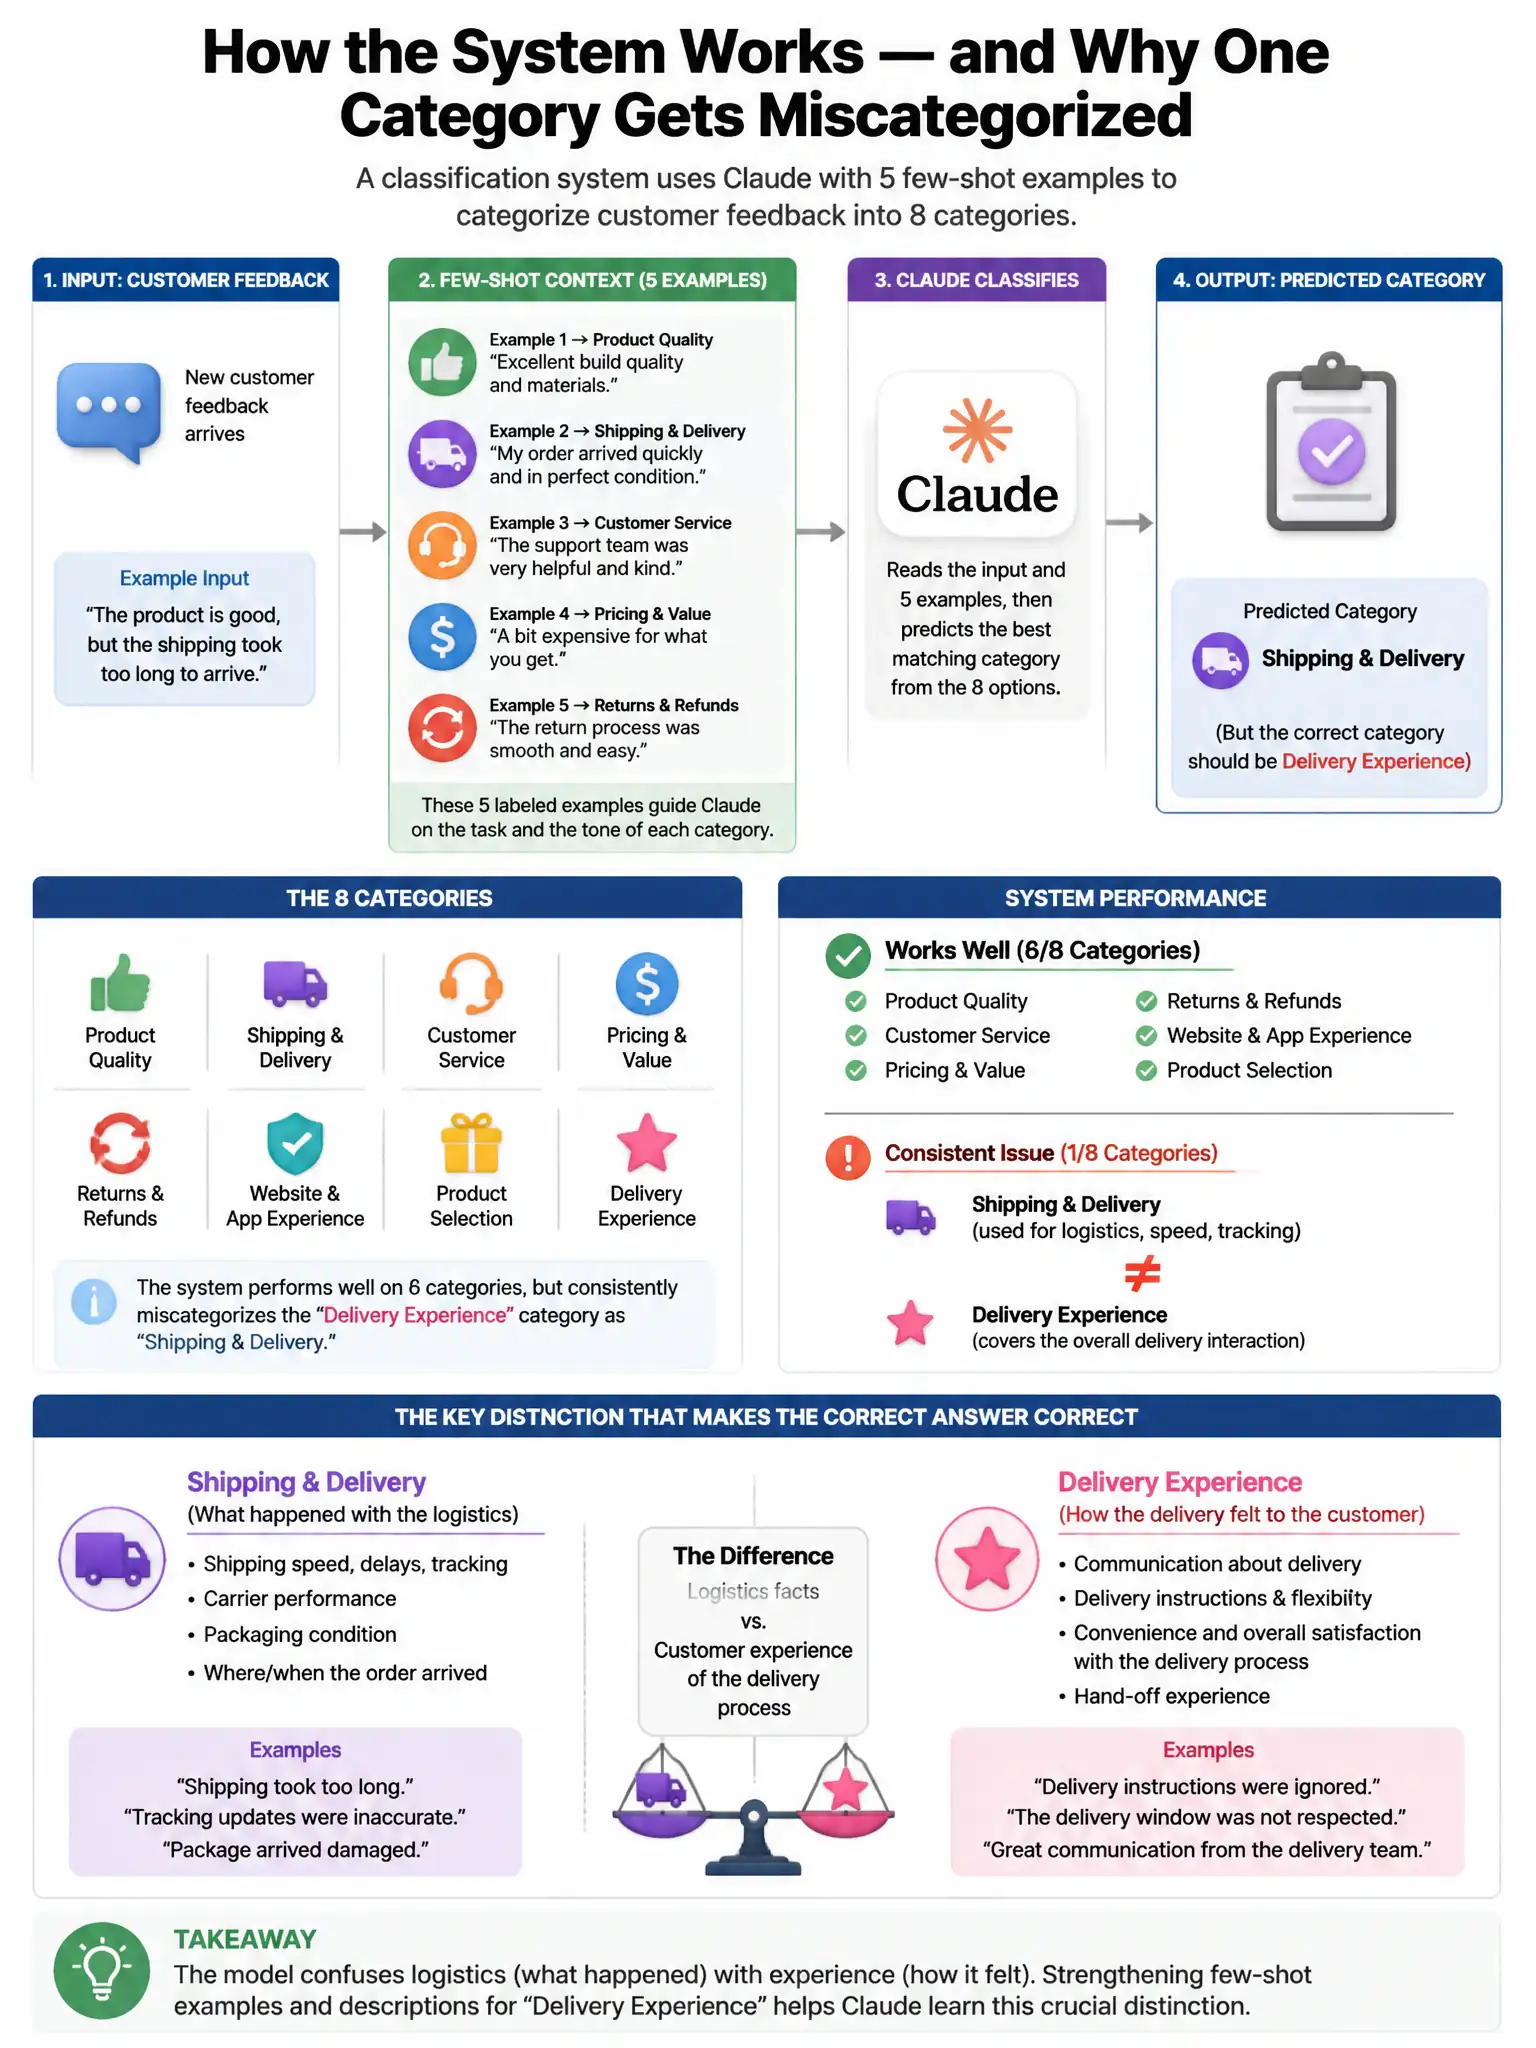
A classification system uses Claude with 5 few-shot examples to categorize customer feedback into 8 categories. The system works well for 6 categories but consistently miscategorizes 2 rare categories. Adding more examples for the rare categories would exceed the token budget. What is the most effective targeted fix?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want examples that show the boundary between the rare categories and their most-confused neighbors. Those adversarial examples teach the model the exact distinction it's missing, and they give you more signal per token than swapping in generic samples.
Full Explanation
The correct fix is to replace generic examples with adversarial examples that clearly demonstrate the boundary between the miscategorized rare categories and their most-confused neighbors. This targets the specific failure mode: when rare categories are being confused, the most informative demonstrations are those that lie near the decision boundary and highlight the distinguishing features. These boundary examples provide more signal per token than generic representatives of the category. Removing well-performing category examples to make room for rare category examples is wrong because it degrades performance on categories that already work, and net accuracy could decrease. Increasing temperature is wrong because higher temperature increases output randomness, which would degrade performance on the six well-performing categories without reliably fixing the rare category errors. Switching to a zero-shot prompt with detailed category descriptions is wrong because it loses the behavioral grounding that few-shot examples provide; detailed descriptions of rare categories are typically less effective than concrete demonstrations for abstract category distinctions.