
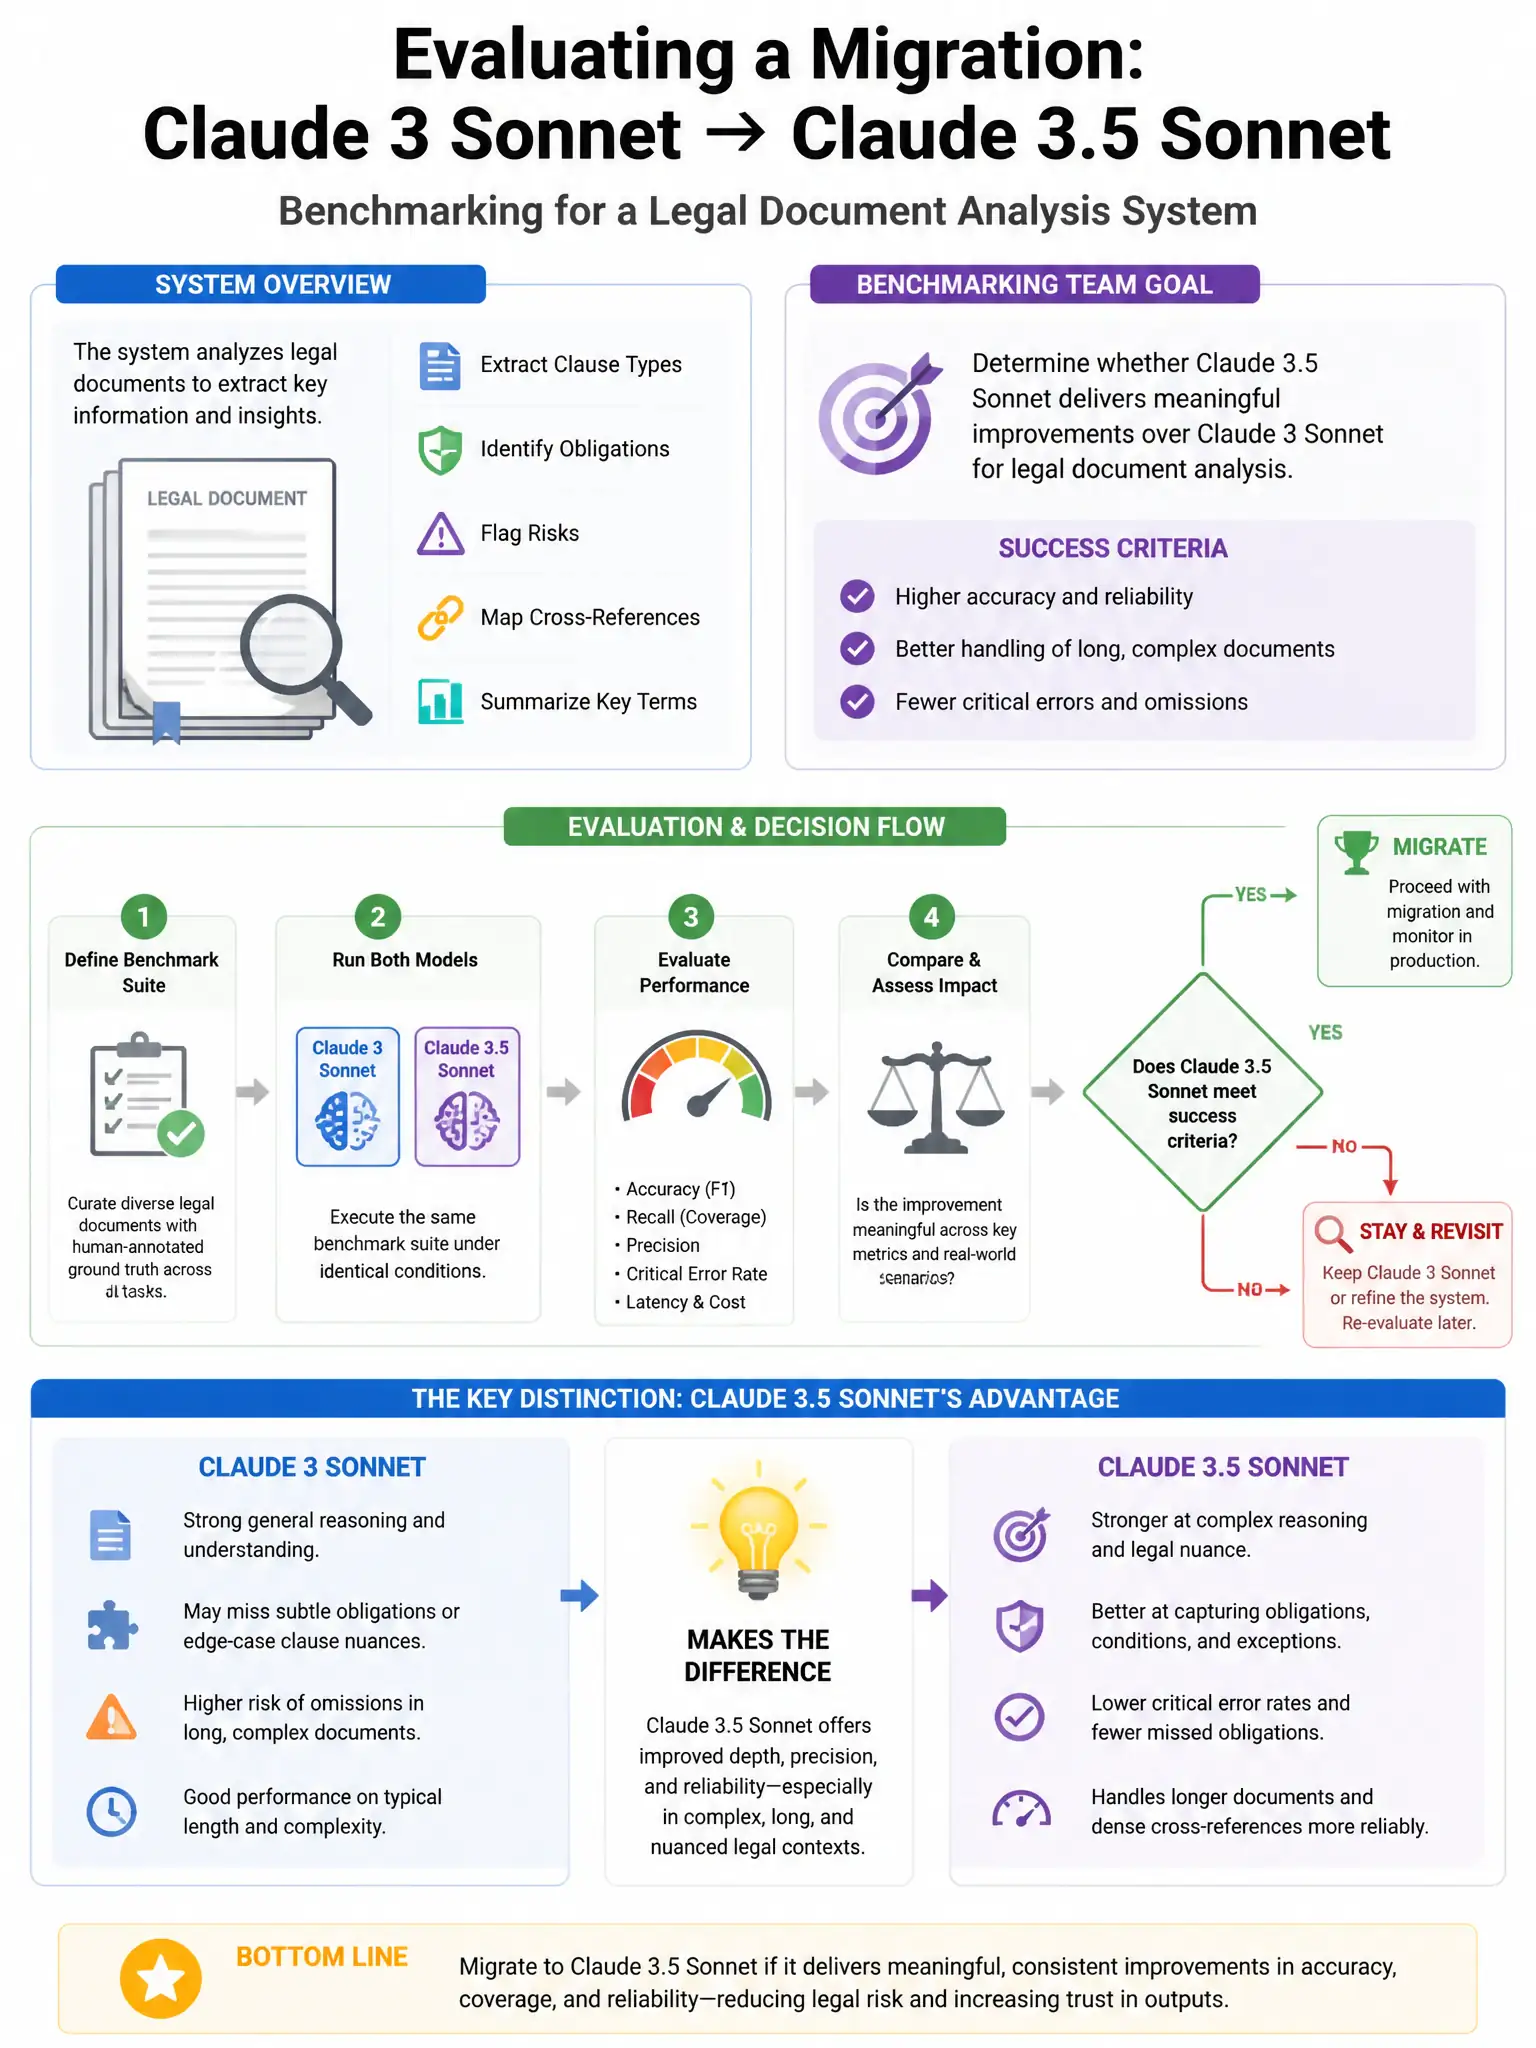
A benchmarking team is evaluating whether to migrate from claude-3-sonnet to claude-3-5-sonnet for a legal document analysis system. The system extracts clause types, identifies obligations, and flags potential risks. What evaluation methodology gives the most reliable signal for this migration decision?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need a golden test set of 200+ legal documents with expert-annotated ground truth, then measure F1 scores across clause types and obligation extraction. That gives objective, reproducible evidence against known correct answers, and the sample size gives you statistical power to detect real differences.
Full Explanation
The golden test set option is correct because a golden test set with expert annotations provides objective, reproducible measurement against known correct answers — F1 scores across clause types give quantitative evidence of extraction quality, and 200+ documents provides statistical power to detect real differences. The 10-document manual review option is wrong because 10 documents is insufficient for statistical significance, and manual review introduces human variability; cherry-picked documents may not represent the real distribution. The published legal NLP leaderboard option is wrong because published benchmarks use standardized tasks that may not reflect the specific clause types and obligation structures in this system's legal domain — benchmark performance rarely transfers directly to domain-specific tasks. The one-week production split-traffic option comparing user satisfaction scores is wrong because running a split-traffic test in production with untested models risks deploying degraded quality to real users on legal documents where errors have consequences; evaluation should happen before production deployment.