
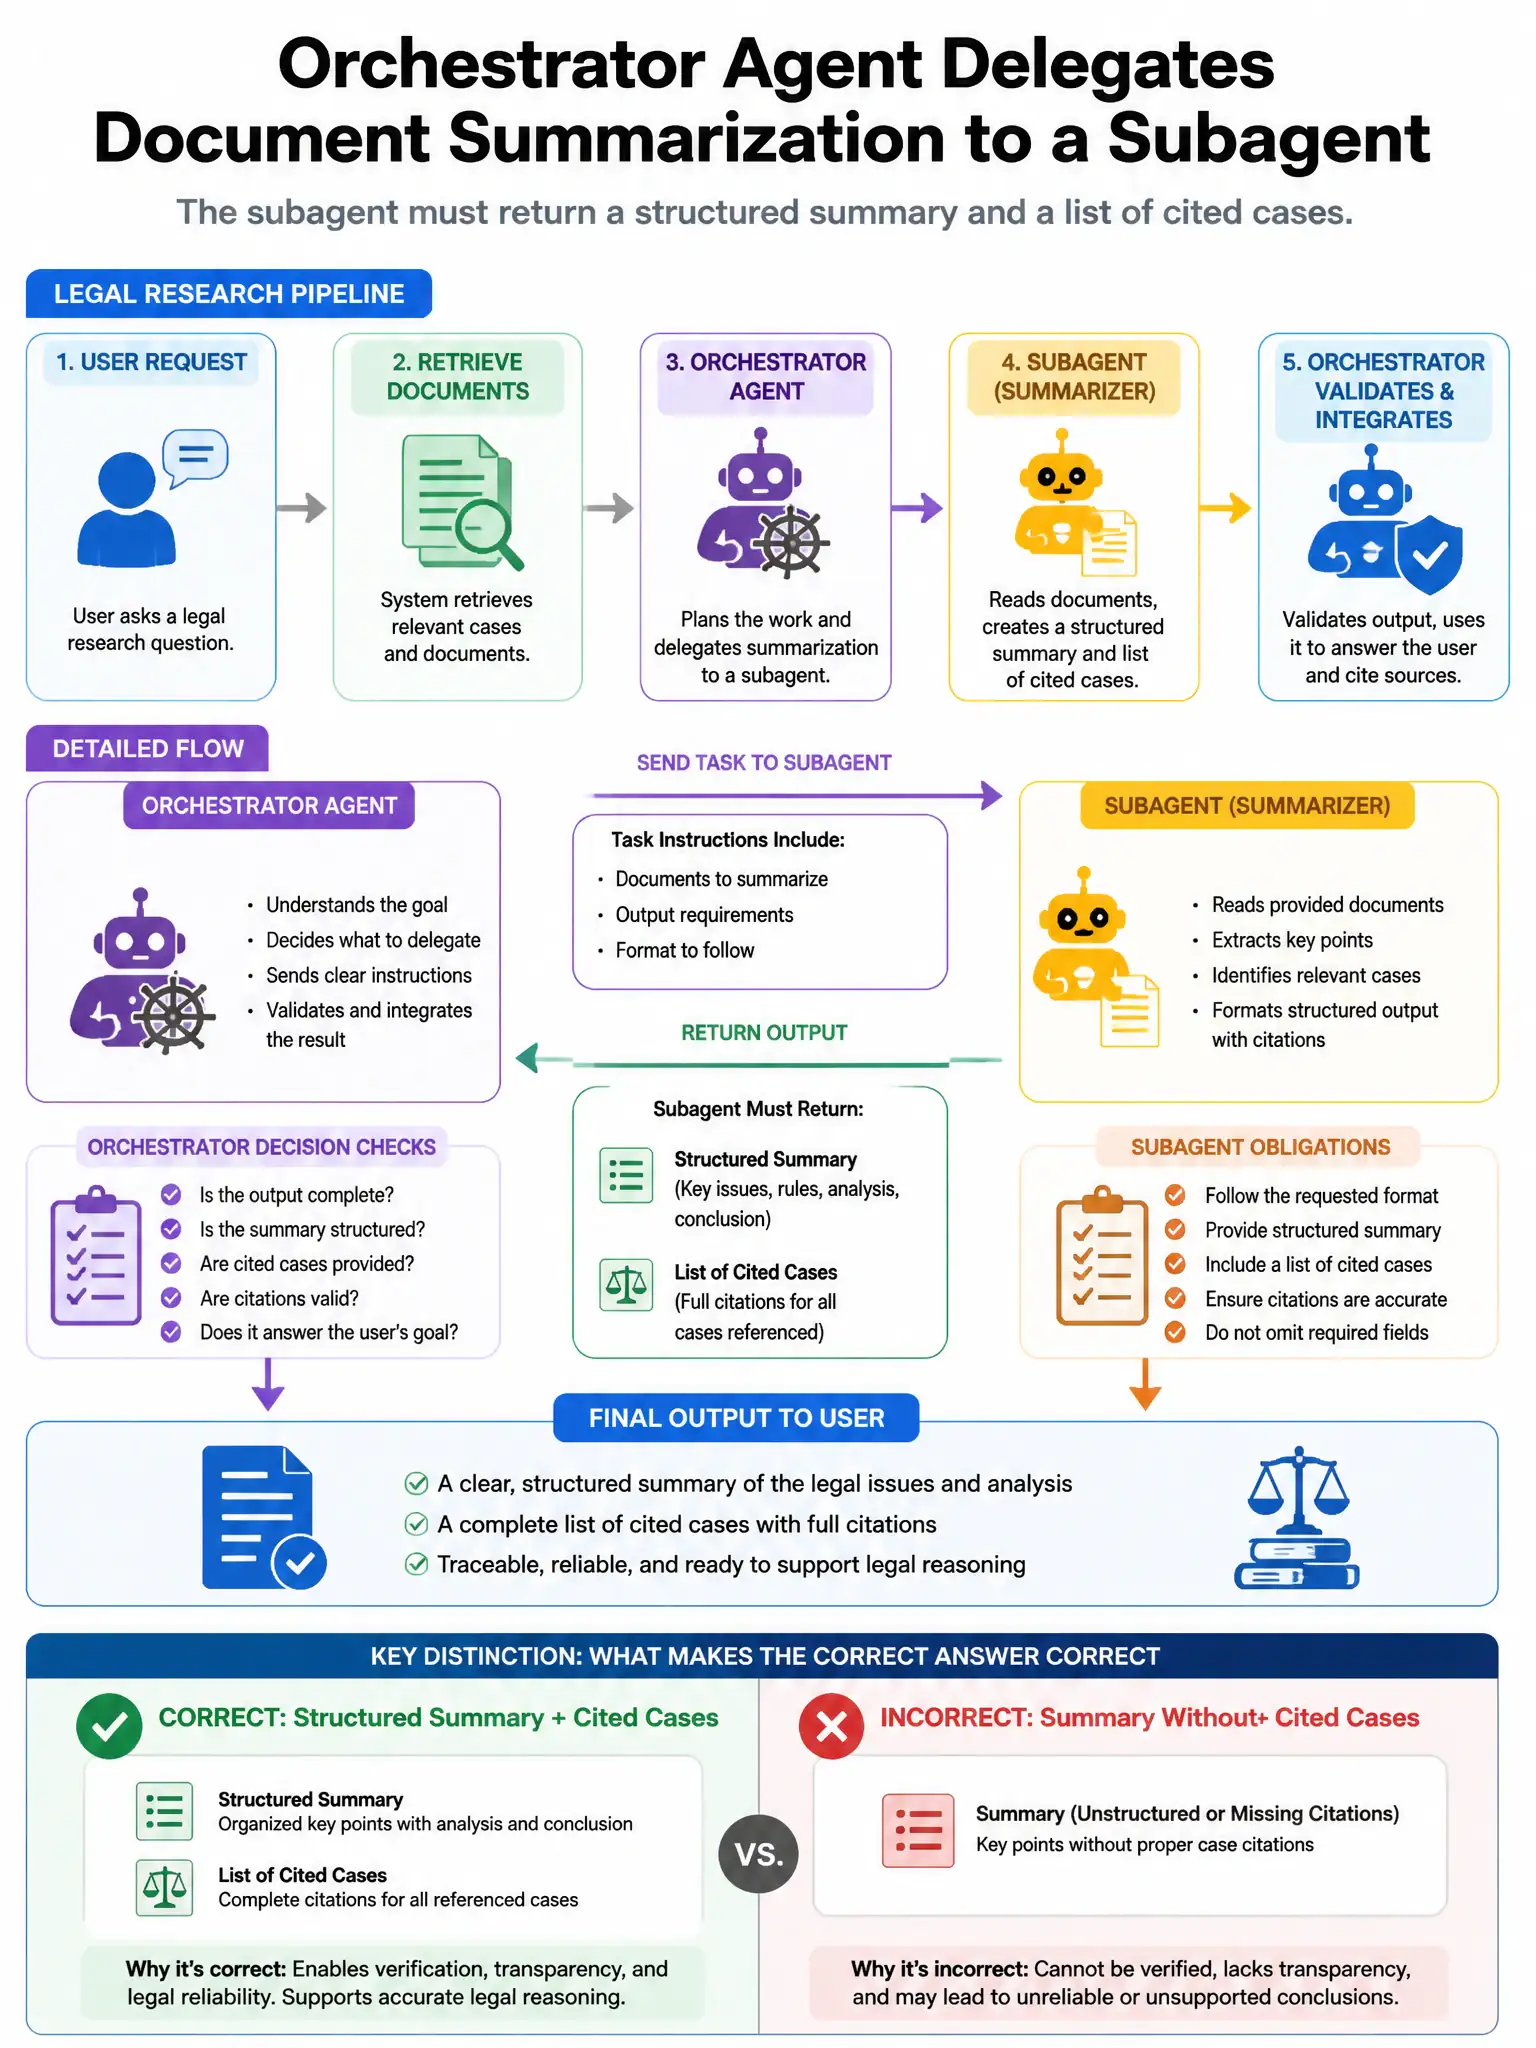
An orchestrator agent in a legal research pipeline delegates document summarization to a subagent. The subagent must return a structured summary and a list of cited cases. The orchestrator then uses the cited cases list to queue additional lookups. The subagent currently returns its response as free-form text. What communication pattern change makes the orchestrator's dependency on subagent output most robust?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you want the subagent to make its final action a structured_output tool call with a strict JSON schema. That gives you machine-parseable arguments with type guarantees, so the orchestrator can read the cited cases directly instead of scraping free-form text.
Full Explanation
Requiring the subagent to invoke a structured_output tool with a defined JSON schema as its final action produces machine-parseable output with strong type guarantees. The orchestrator reads tool_use.arguments rather than applying regex or string parsing to free-form text. This is robust to variations in phrasing, ordering, or formatting that would break delimiter-based parsing. The JSON schema can specify required fields (summary_text, cited_cases array) and field types, enabling validation. The delimiter-based approach is wrong because delimiter-based parsing is brittle — the model may include the delimiter string in the content (e.g., quoting a case name that contains dashes), change whitespace, or fail to generate the delimiter in edge cases. The follow-up-message approach is wrong because requiring a follow-up message doubles the API call count, adds latency, and still relies on free-form parsing of the follow-up response. The shared key-value store approach is wrong because using a shared key-value store adds infrastructure dependency and asynchronous complexity for what is essentially a synchronous communication pattern; it does not change the parsing robustness problem.