
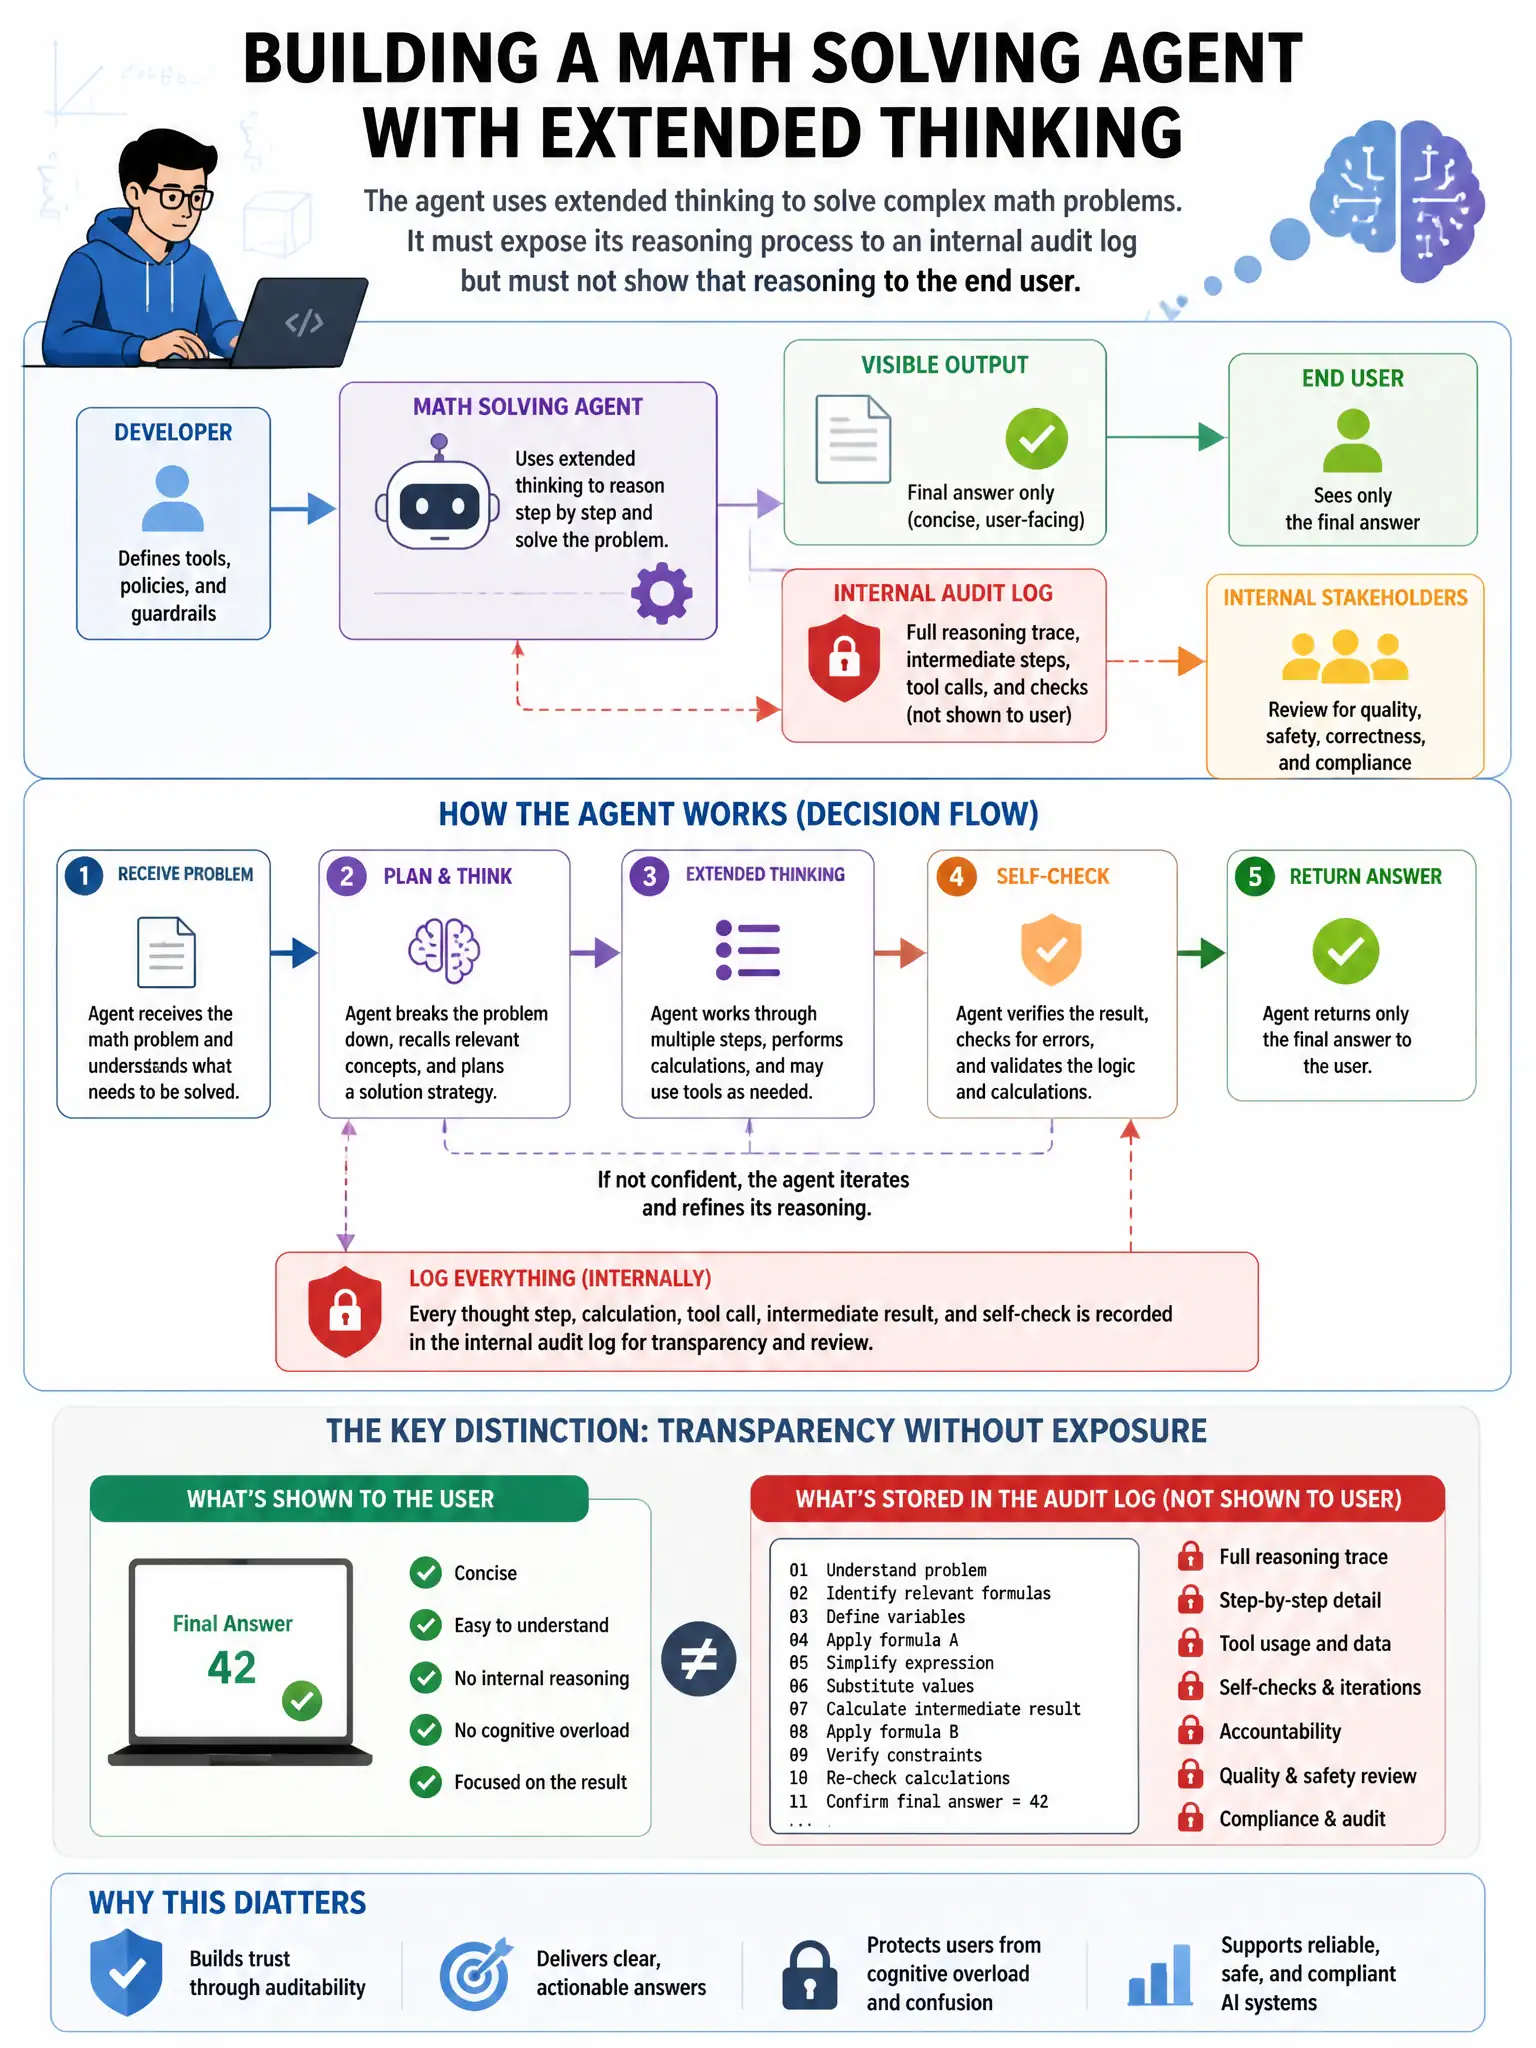
A developer is implementing an agent that uses extended thinking to solve complex math problems. The agent must expose its reasoning process to an internal audit log but must not show thinking blocks to end users. When reading the streaming response, how should the application differentiate thinking block content from final answer content?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you check the type field in each content_block_start event. Send 'thinking' deltas to the audit log and 'text' deltas to the user display.
Full Explanation
The correct approach is the one that uses the type field in each content_block_start event: thinking blocks have type 'thinking' and text blocks have type 'text'. When extended thinking is enabled, the stream includes blocks with type 'thinking' for the reasoning process and type 'text' for the final answer. The application maintains a state variable tracking the current block type and routes content_block_delta events to the appropriate handler — audit log for thinking, user display for text. This allows real-time streaming of both channels simultaneously. The option claiming thinking blocks are always the last content blocks is wrong because thinking blocks appear before text blocks in the stream, not last; the order is thinking → text, since the model generates reasoning before its final answer. The option claiming separate parallel HTTP responses is wrong because the API does not use multiple parallel HTTP responses; all content is delivered in a single SSE stream with typed events. The option claiming extended thinking content is only available in the non-streaming API response is wrong because the Anthropic API does support streaming with extended thinking enabled; thinking blocks appear in the stream with the type discriminator described above.