
An architect is designing a system prompt for a Claude instance that must generate SQL queries from natural language. The model occasionally generates queries using table names from its training knowledge rather than the actual database schema. What is the most reliable technique to ground Claude's SQL generation in the actual schema?
Select an answer to reveal the explanation.
Short Explanation
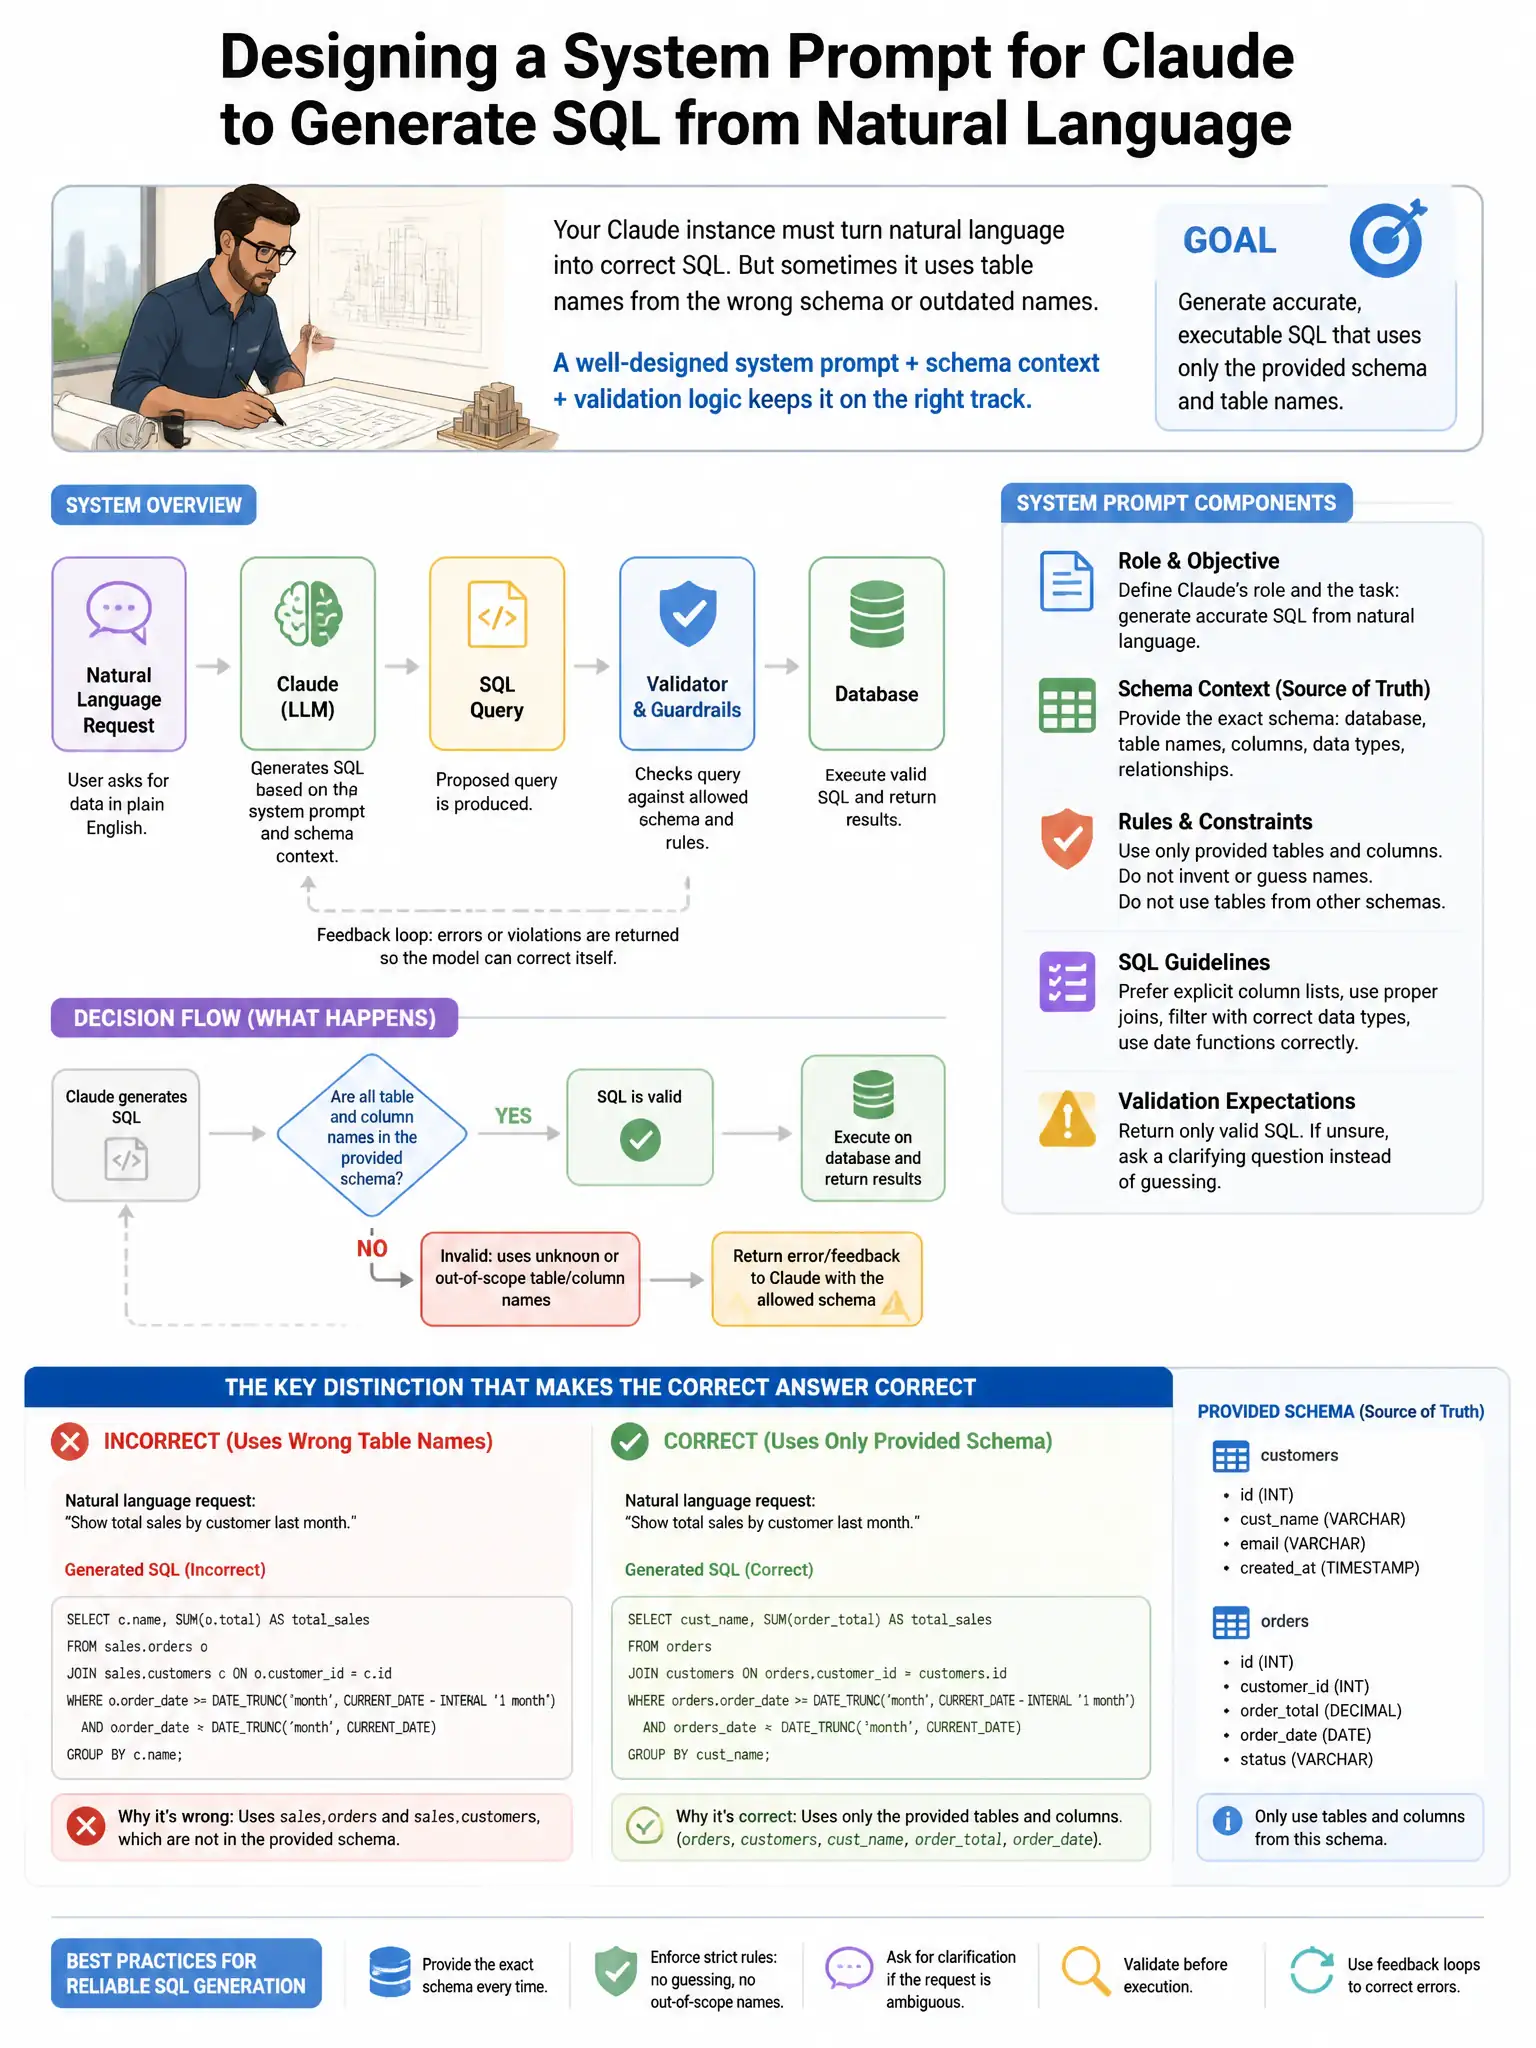
You need to give Claude the actual schema as explicit context, so the DDL-in-schema-tag approach is the right move. Putting the CREATE TABLE statements inside a <schema> tag and telling Claude to use only those tables and columns closes the training-data hallucination gap.
Full Explanation
The correct approach is to include the complete DDL (CREATE TABLE statements with column names, types, and constraints) inside a <schema> XML tag in the system prompt, and add a grounding instruction that SQL must only reference tables and columns present in the <schema> tag. Grounding SQL generation in the actual schema requires providing the schema as explicit context. Placing DDL in a clearly labeled <schema> XML tag makes the authoritative information structurally distinct and easy to reference; the explicit instruction to only reference tables and columns present in the schema closes the loophole that allows training-data hallucinations. This is the primary preventive control.
The few-shot approach is wrong because adding a few-shot example for each table in the database schema would require one example per table times the number of column combinations; at scale this is impractical and still susceptible to hallucination between examples.
The extended-thinking approach is wrong because extended thinking improves multi-step reasoning but does not provide the model with the actual schema; the model cannot think its way to the correct schema if it was never given the schema, so it would still reason from its training knowledge.
The EXPLAIN-based retry approach is wrong because running EXPLAIN on every generated SQL query and retrying when unknown tables are detected is a detect-and-retry pattern that adds latency and database round-trips; it is a valid fallback but not a substitute for the preventive approach of schema injection.