
An embedding model selection decision is being made for a RAG system that will serve multilingual queries (English, Spanish, Mandarin, Arabic) against a document corpus that is 90% English. Users query in their native language and expect documents in English to be retrieved. Which embedding model property is most critical for this use case?
Select an answer to reveal the explanation.
Short Explanation
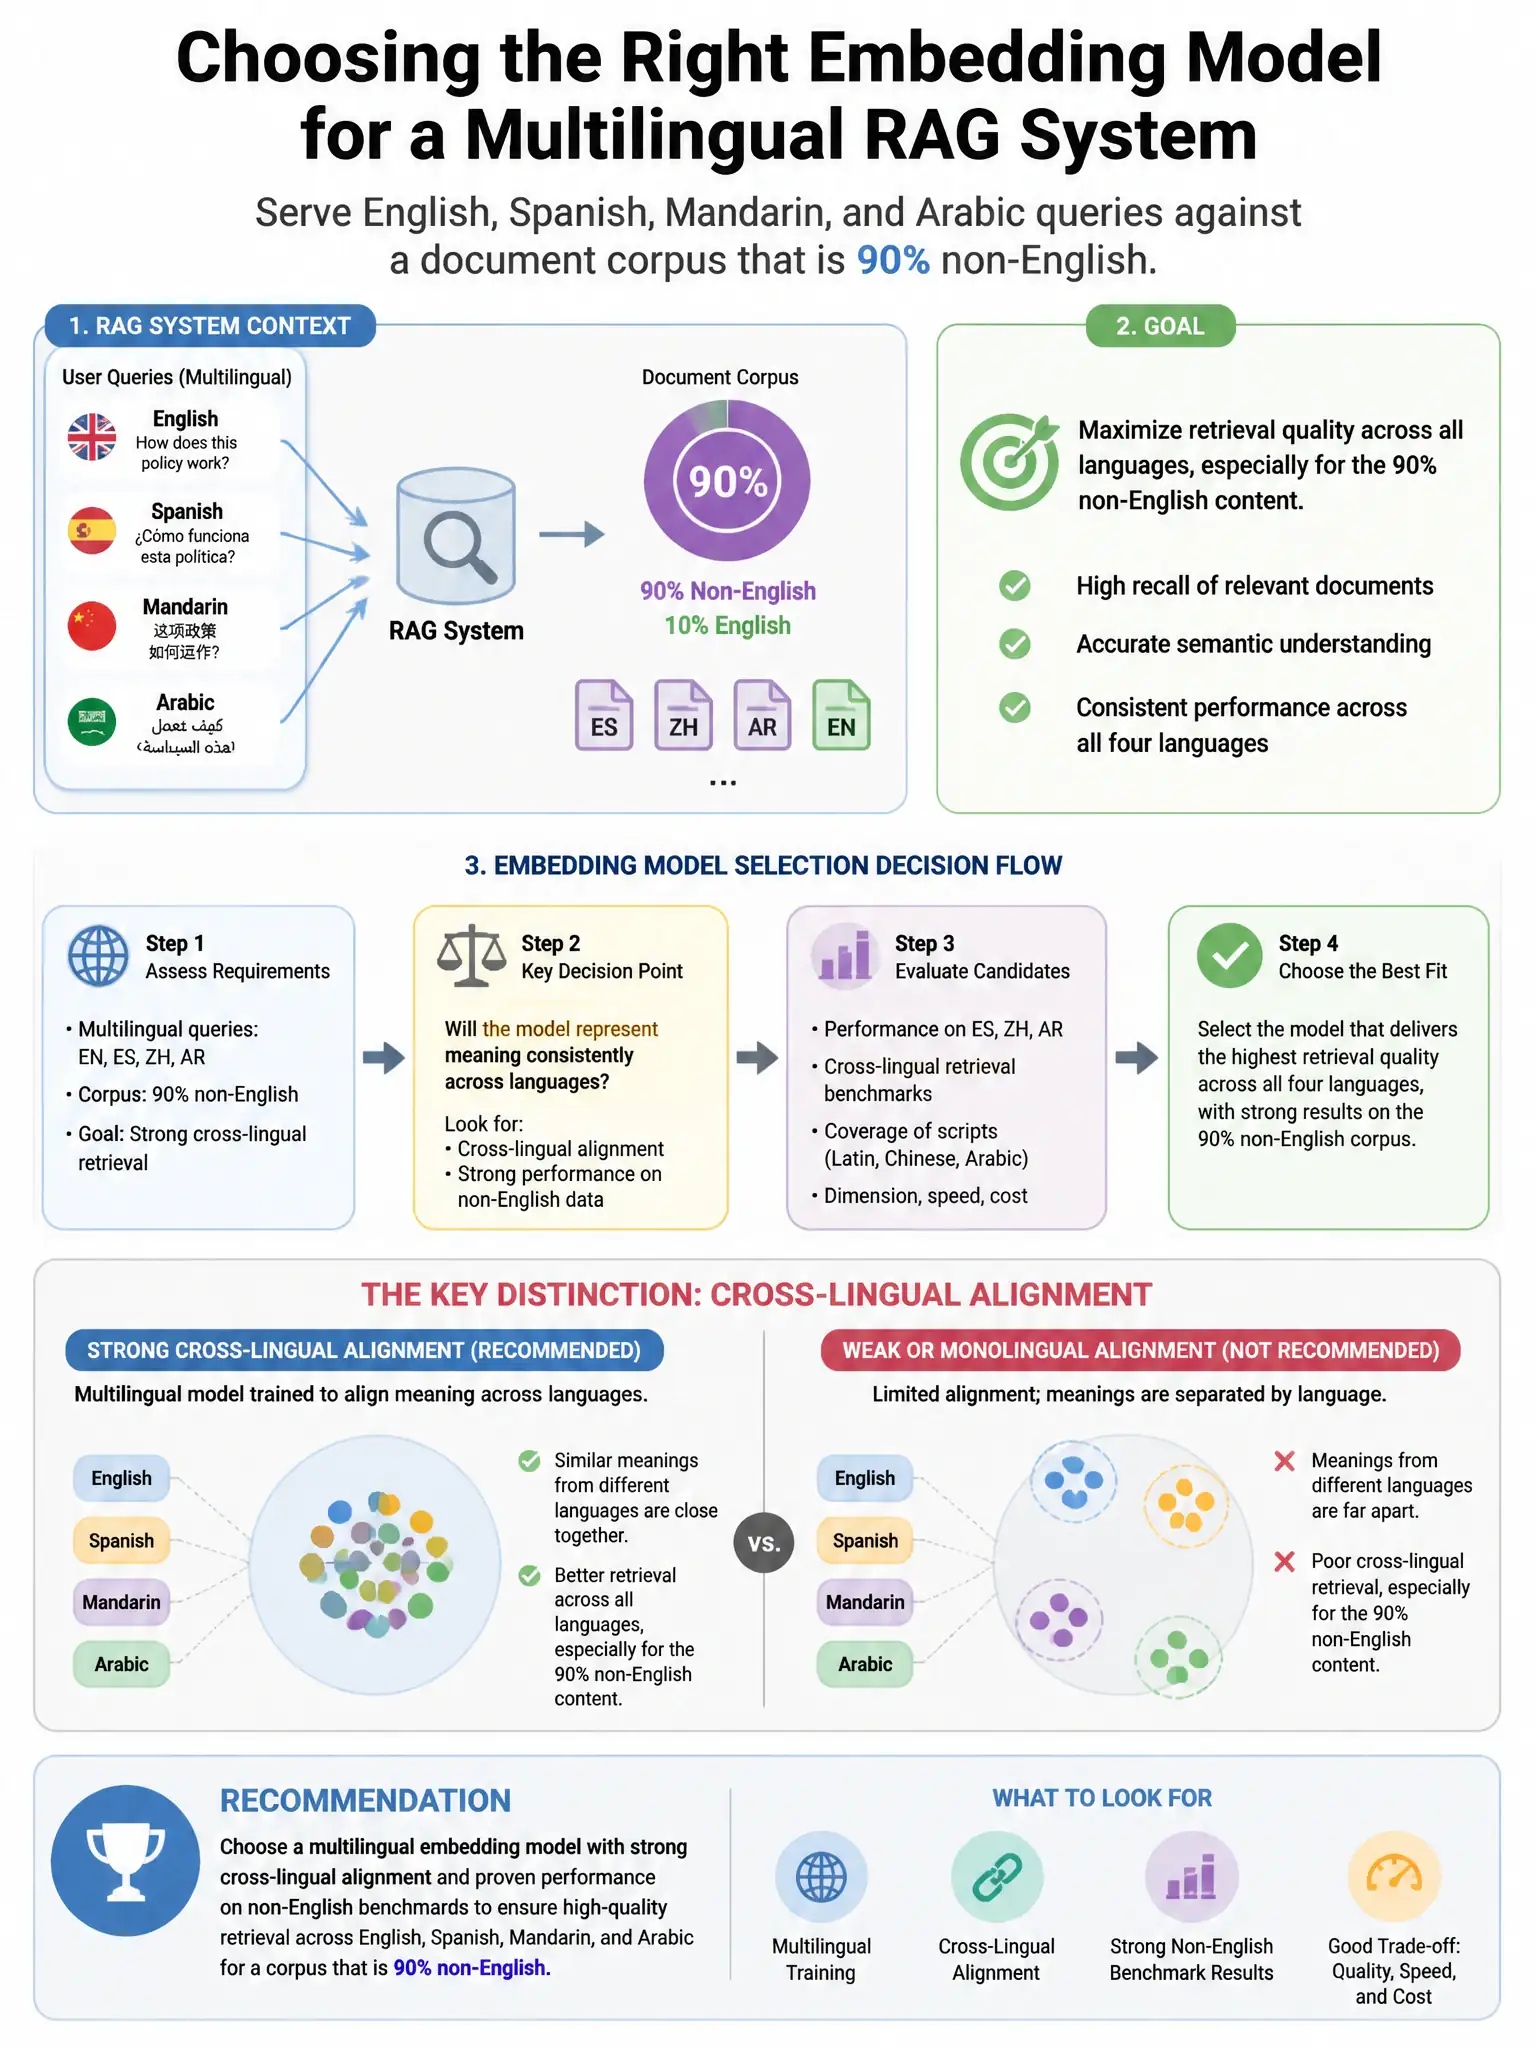
Here's the deal — you need cross-lingual retrieval, so pick the model pre-trained on a balanced multilingual corpus. That gives you a shared embedding space where Spanish, Mandarin, or Arabic queries land near English docs with the same meaning.
Full Explanation
The correct property is multilingual pre-training on a balanced multilingual corpus, producing a shared embedding space where semantically equivalent phrases in different languages map to nearby vectors. The core requirement is cross-lingual retrieval: a Spanish query must retrieve semantically matching English documents. This requires a multilingual embedding model trained on parallel or multilingual corpora such that the embedding space is language-agnostic — semantically equivalent content in different languages maps to nearby regions in the shared vector space.
The option about support for maximum context length (≥ 512 tokens per chunk) to accommodate long Arabic text segments is wrong because context length affects the chunk size that can be embedded but does not determine whether cross-lingual alignment works; it is a secondary concern after selecting a multilingual model. The option about using a cosine similarity metric rather than dot-product similarity, as cosine normalization is more effective for cross-lingual distance measurement, is wrong because cosine similarity vs. dot-product is an indexing and scoring choice that can be configured independently of the model; neither metric inherently provides cross-lingual capability, and the choice between them does not determine retrieval language generalization. The option about high vector dimensionality (≥ 1,536 dimensions) to provide sufficient representational capacity for cross-lingual semantic alignment is wrong because dimensionality affects representational capacity in general but is not the property that enables cross-lingual alignment; a high-dimensional monolingual English model cannot align Spanish queries to English documents regardless of dimensionality.