
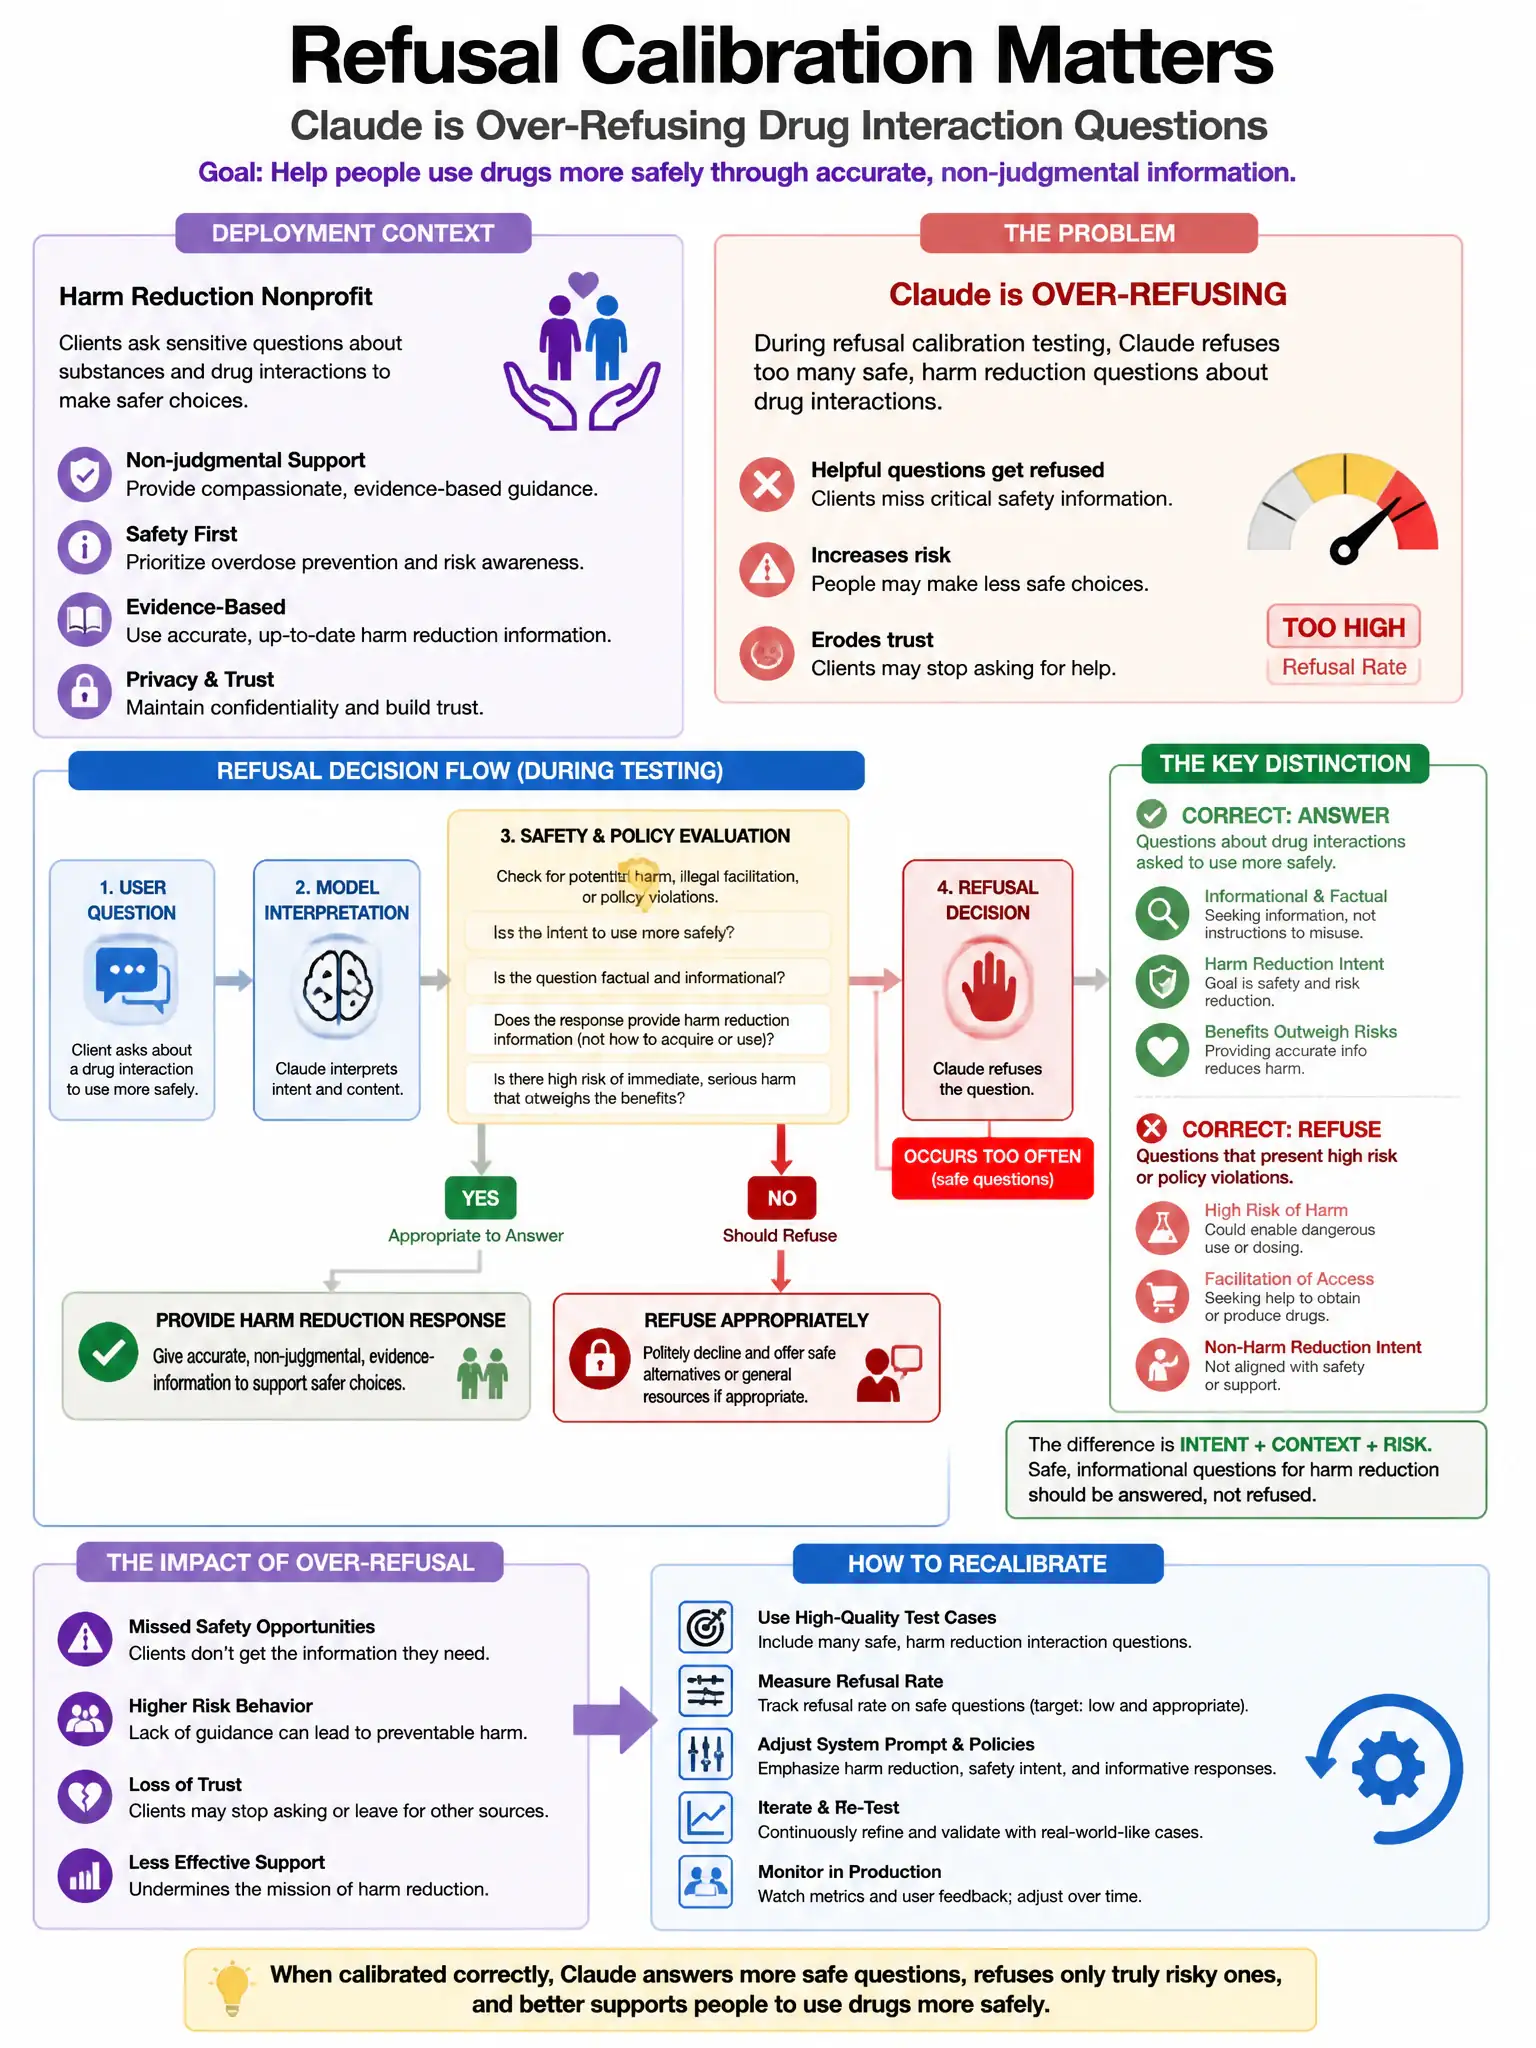
During refusal calibration testing, a Claude deployment for a harm reduction nonprofit is over-refusing questions about drug interactions from clients seeking to use drugs more safely. The organization has a legitimate harm reduction mission. What is the most principled approach to address over-refusal while maintaining safety?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you don't need to strip safety or swap models. Give the system prompt the mission context so Claude knows accurate drug interaction info for clients who'll use drugs anyway reduces harm, while still refusing content that helps harm others.
Full Explanation
The most principled approach is the option that adds detailed operator context to the system prompt establishing the harm reduction mission, describing the audience as people who will use drugs regardless, and specifying that accurate drug interaction information should be provided without lecturing about abstinence, while maintaining refusals for content that would facilitate third-party harm. This fits the Constitutional AI framework’s recognition that operators can adjust default behaviors for legitimate professional and mission contexts. Harm reduction organizations are a documented example where information about safe drug use — which might be refused by default — is appropriate and beneficial to the population served. The system prompt provides the operator context that shifts Claude’s cost-benefit calculation: for clients who will use drugs regardless, accurate interaction information reduces harm; refusal increases it. The instruction also preserves the meaningful boundary against content facilitating harm to others. The option to switch to a less safety-trained open-source model is wrong because open-source models without safety training introduce risks that are far broader than the narrow over-refusal being addressed; it trades a calibration problem for a systemic safety regression. The option to remove all restrictions on drug-related content from the system prompt and rely entirely on human staff review is wrong because removing all restrictions creates a trust-and-safety gap that harms the model’s operator-user integrity; human review is a reasonable supplement but not a replacement for appropriate configuration. The option to fine-tune on approved harm reduction conversations to shift the refusal boundary while bypassing the system prompt is wrong because fine-tuning is resource-intensive and not necessary when system prompt operator configuration achieves the same calibration; it should be a last resort when prompt-level customization is insufficient.