
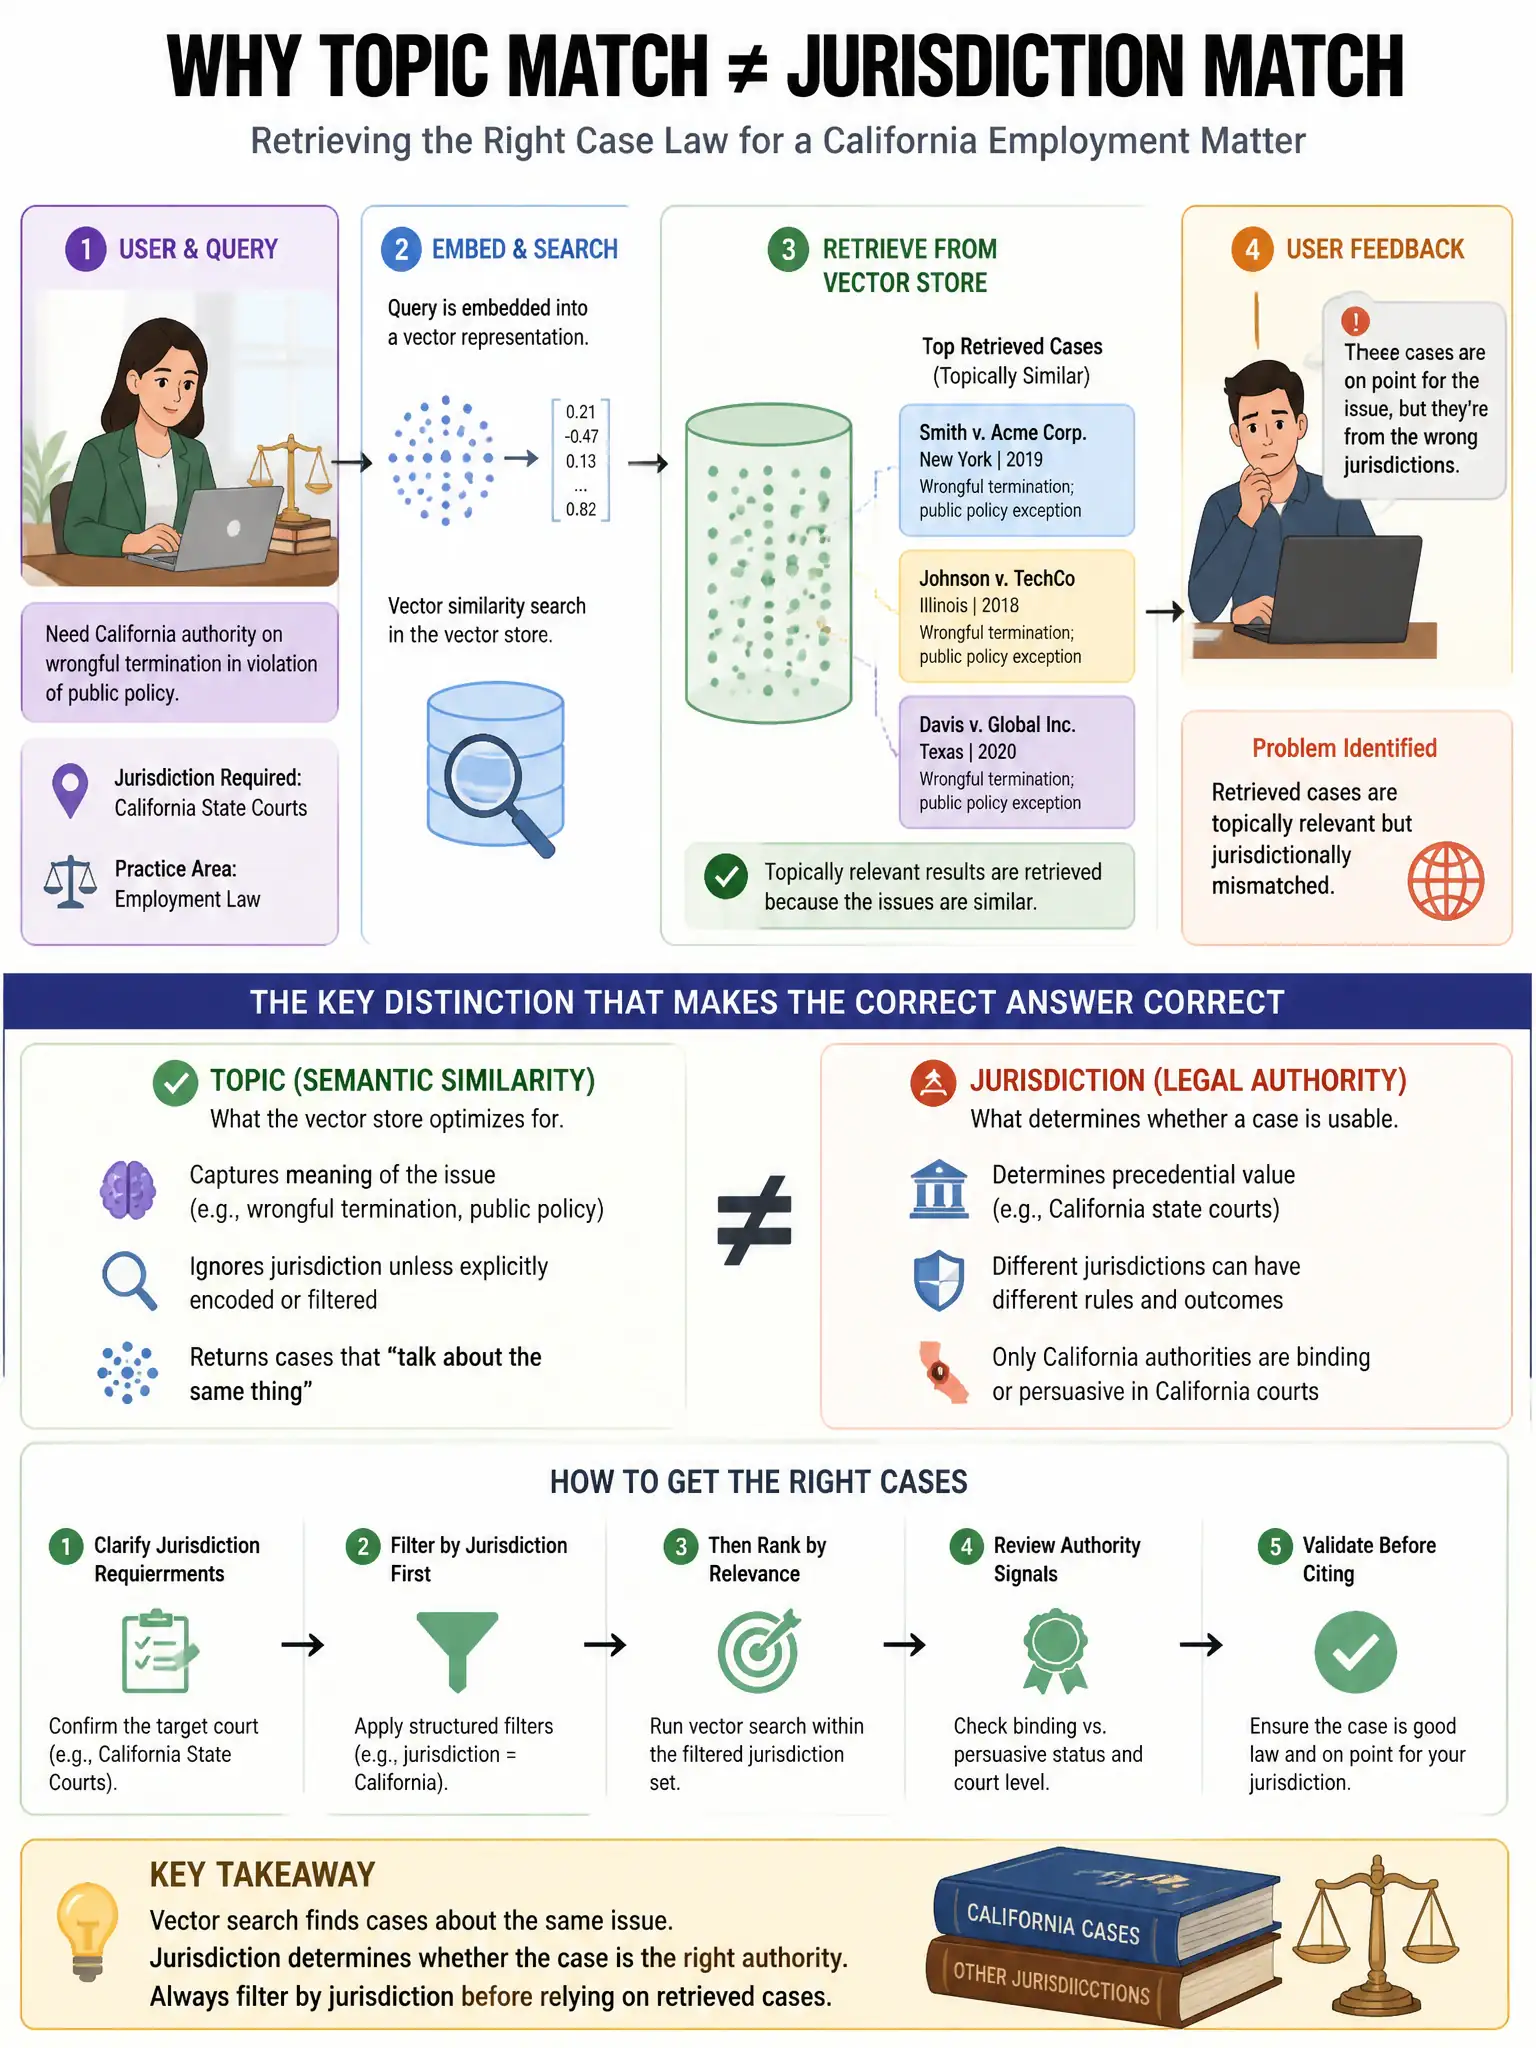
A legal research assistant retrieves case law from a vector store. Users report that retrieved cases are topically relevant but jurisdictionally mismatched — a California employment case is retrieved for a New York labor question. The vector store supports metadata filtering. What change addresses this with the least retrieval quality regression?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need a hard pre-filter on the jurisdiction metadata field before vector search, because jurisdiction is a hard categorical constraint, not a soft relevance signal. That way, only documents tagged with the query's jurisdiction are candidates for approximate nearest-neighbor retrieval, eliminating jurisdiction mismatches without hurting within-jurisdiction ranking quality.
Full Explanation
The correct change is to apply a hard pre-filter on the jurisdiction metadata field before vector search so only documents tagged with the query's jurisdiction are candidates for approximate nearest-neighbor retrieval. Jurisdiction is a hard categorical constraint, not a soft relevance signal. Pre-filtering on metadata ensures the search only considers documents matching the required jurisdiction, eliminating the class of mismatches entirely without degrading within-jurisdiction ranking quality. This is the standard pattern when a metadata attribute is a hard exclusion criterion.
The approach of adding jurisdiction as a concatenated prefix to each chunk's text before embedding is wrong because it only partially encodes jurisdictional identity and does not guarantee correctness; the embedding space is continuous, so a California case with many overlapping terms could still outscore a New York case.
The two-stage retrieval approach—running broad approximate nearest-neighbor search with no filter to retrieve the top 50 candidates, then applying a metadata filter for jurisdiction and reranking the filtered set by score—is wrong because retrieving 50 broad candidates and post-filtering is less efficient and risks dropping below an adequate candidate count after filtering, especially for rare jurisdictions.
The approach of increasing retrieved documents from 5 to 25 and prompting the large language model to select only jurisdictionally appropriate cases, using Claude as a post-retrieval filter, is wrong because it introduces unnecessary model calls, adds latency and cost, and relies on model behavior rather than deterministic metadata logic for what should be a deterministic constraint.