
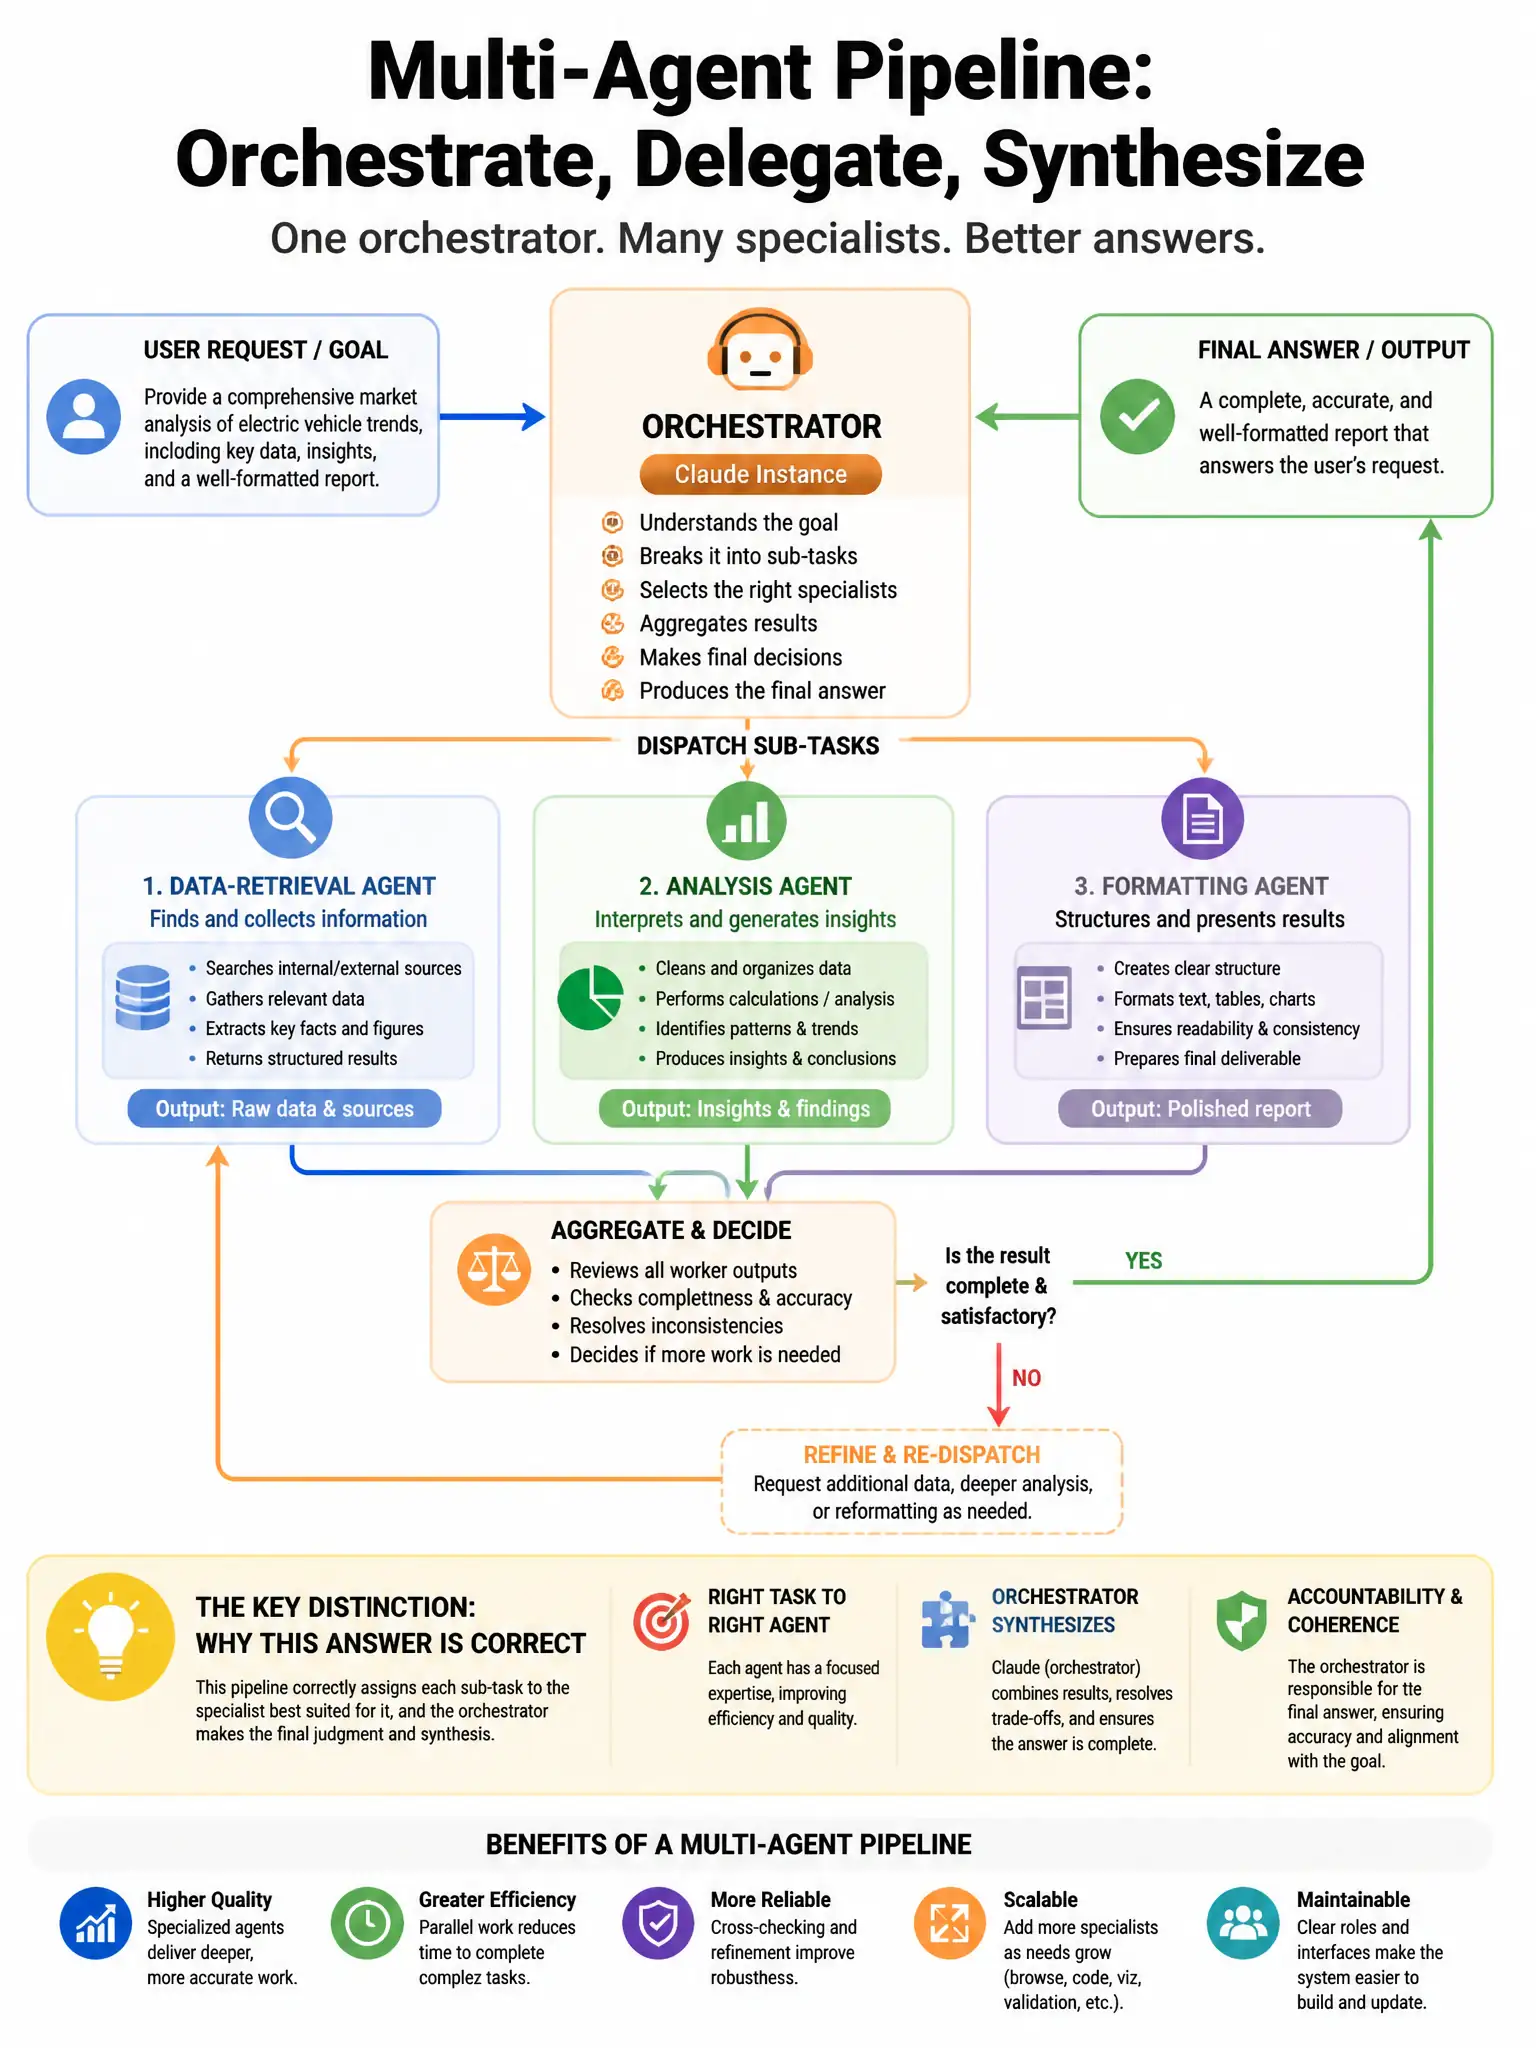
A multi-agent pipeline has an orchestrator Claude instance that dispatches sub-tasks to three specialized worker agents (data-retrieval, analysis, formatting). The orchestrator passes task context to each worker via tool_result content blocks. During a load test, the formatting agent begins receiving stale data from a prior run because the orchestrator is reusing a conversation thread across multiple pipeline executions. What is the root cause and correct fix?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you're getting stale data because the orchestrator is reusing the same messages array, so old tool_result blocks ride along into the next run. Start each pipeline execution with a fresh conversation thread and a clean messages array.
Full Explanation
The correct answer is the option stating that the orchestrator is carrying prior-run tool_result blocks in the messages array across executions, and that each pipeline run should begin a new conversation thread with a clean messages array. The Claude API is stateless — the messages array the client sends is the entire conversation history. If an orchestrator reuses the same messages array and appends to it across multiple pipeline runs, the prior run's tool_result blocks remain in the context window, contaminating the next run's input to workers. The fix is to start a fresh messages array for each pipeline execution. The cache_control breakpoint option is wrong because cache_control breakpoints manage prompt caching costs, not data freshness; they do not invalidate or clear tool_result content. The system-prompt option is wrong because system prompts are also sent on every API call and do not represent a different statefulness model; using them for task context does not solve the problem of accumulated messages. The max_tokens-to-zero option is wrong because max_tokens controls output length, not conversation state; setting it to zero would not flush context and would also prevent any output.