
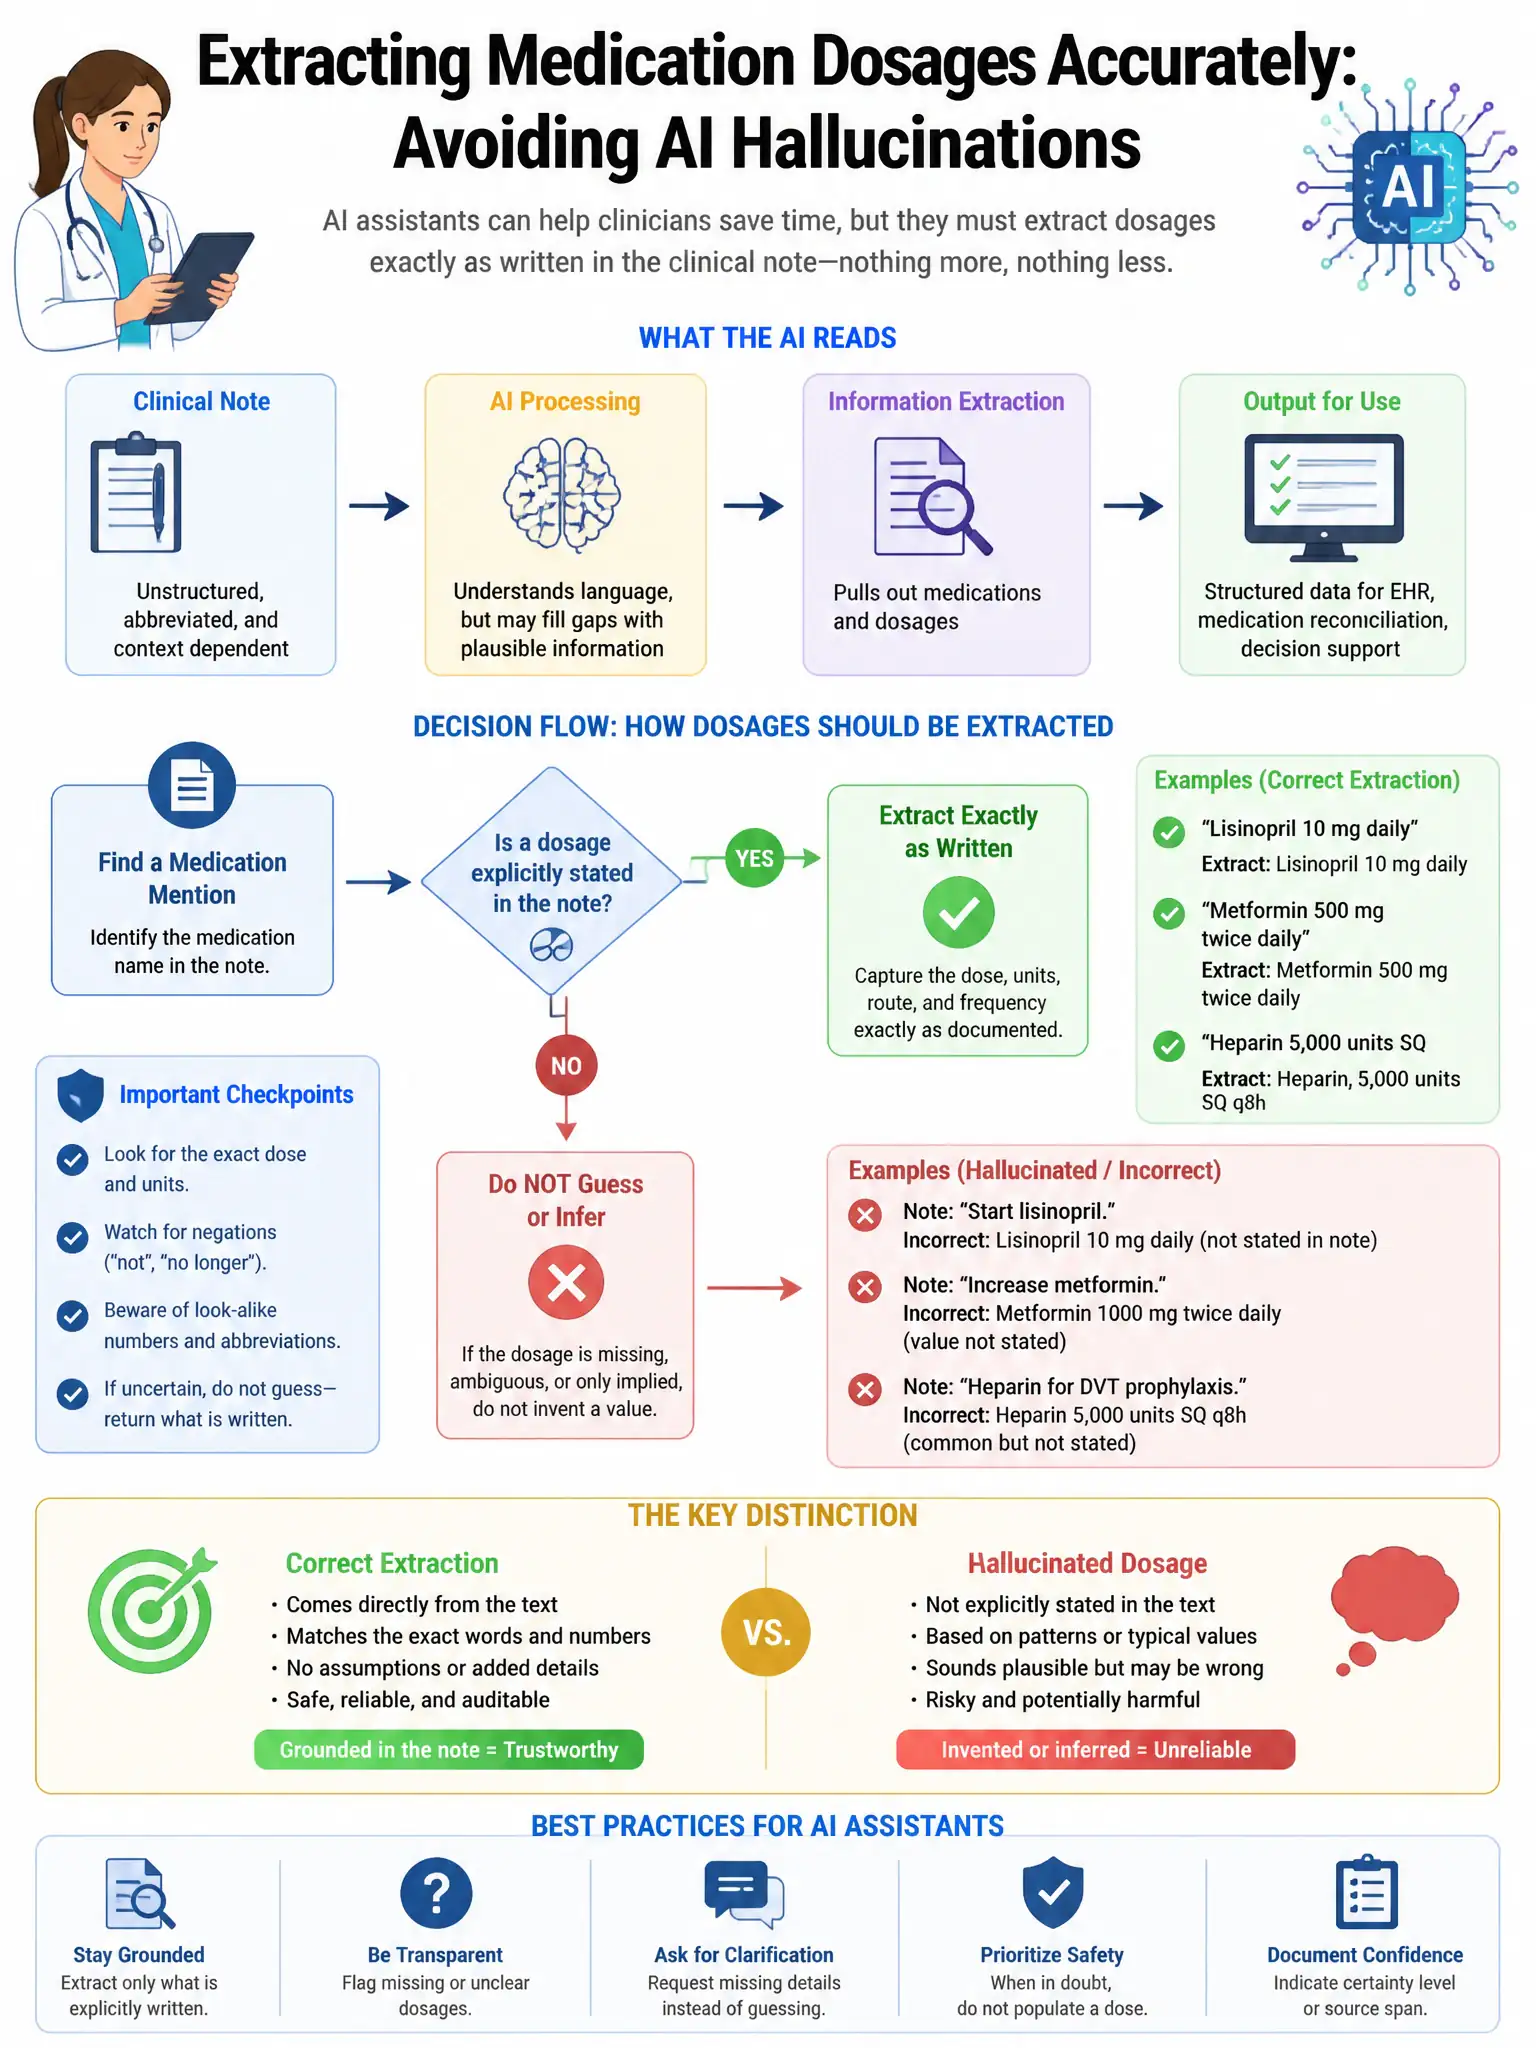
An AI assistant for medical professionals needs to accurately extract medication dosages from clinical notes. The system occasionally hallucinates dosages that appear plausible but are not in the note (e.g., stating '500mg twice daily' when the note says 'standard dose'). The engineering team has tried: (1) explicit anti-hallucination instructions ('only extract what is explicitly stated'), (2) temperature: 0, (3) few-shot examples. The hallucination rate is still 4% on ambiguous notes. The team is debating two approaches: A) force Claude to quote the exact source text supporting each extraction, B) add a second validation pass with Claude to verify each extraction. Which approach is architecturally superior for this specific failure mode?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — requiring the model to quote the exact source text for each extraction is architecturally superior for this failure mode. You're forcing grounding at generation time, so Claude has to find a real character sequence in the note before it can produce a valid output. If the dosage isn't stated, there's nothing to quote, and a bad quote is easy to catch downstream.
Full Explanation
The source-quotation approach is architecturally superior for this specific failure mode — ambiguous notes where Claude is inferring dosages that are not explicitly stated. Requiring Claude to output the exact verbatim text supporting each extraction creates a self-grounding constraint at generation time: the model must find a specific character sequence in the note to produce a valid output. Hallucinated dosages cannot be grounded in a quote that doesn't exist, and a misquote is immediately detectable downstream. The downstream system can verify quotes against the source text deterministically through string matching, providing a reliable quality gate without a second LLM call. The validation-pass approach is weaker because a second model call with fresh context may still use the same model and the same biases, so it can confirm a hallucination — for example, agreeing that a dosage is stated when it is not. Validation-by-same-model for factual grounding is a known weakness, even though it can avoid changes to the primary extraction architecture. The combined source-quotation-plus-validation approach adds cost and complexity, including human escalation when the validator disagrees with the extractor; it may be better than validation alone, but the question asks which approach is architecturally superior as the primary approach. The pre-tagged XML-span approach only works when dosages follow predictable patterns, and the ambiguous notes causing the 4% hallucination rate are exactly the cases that would evade regex matching.