
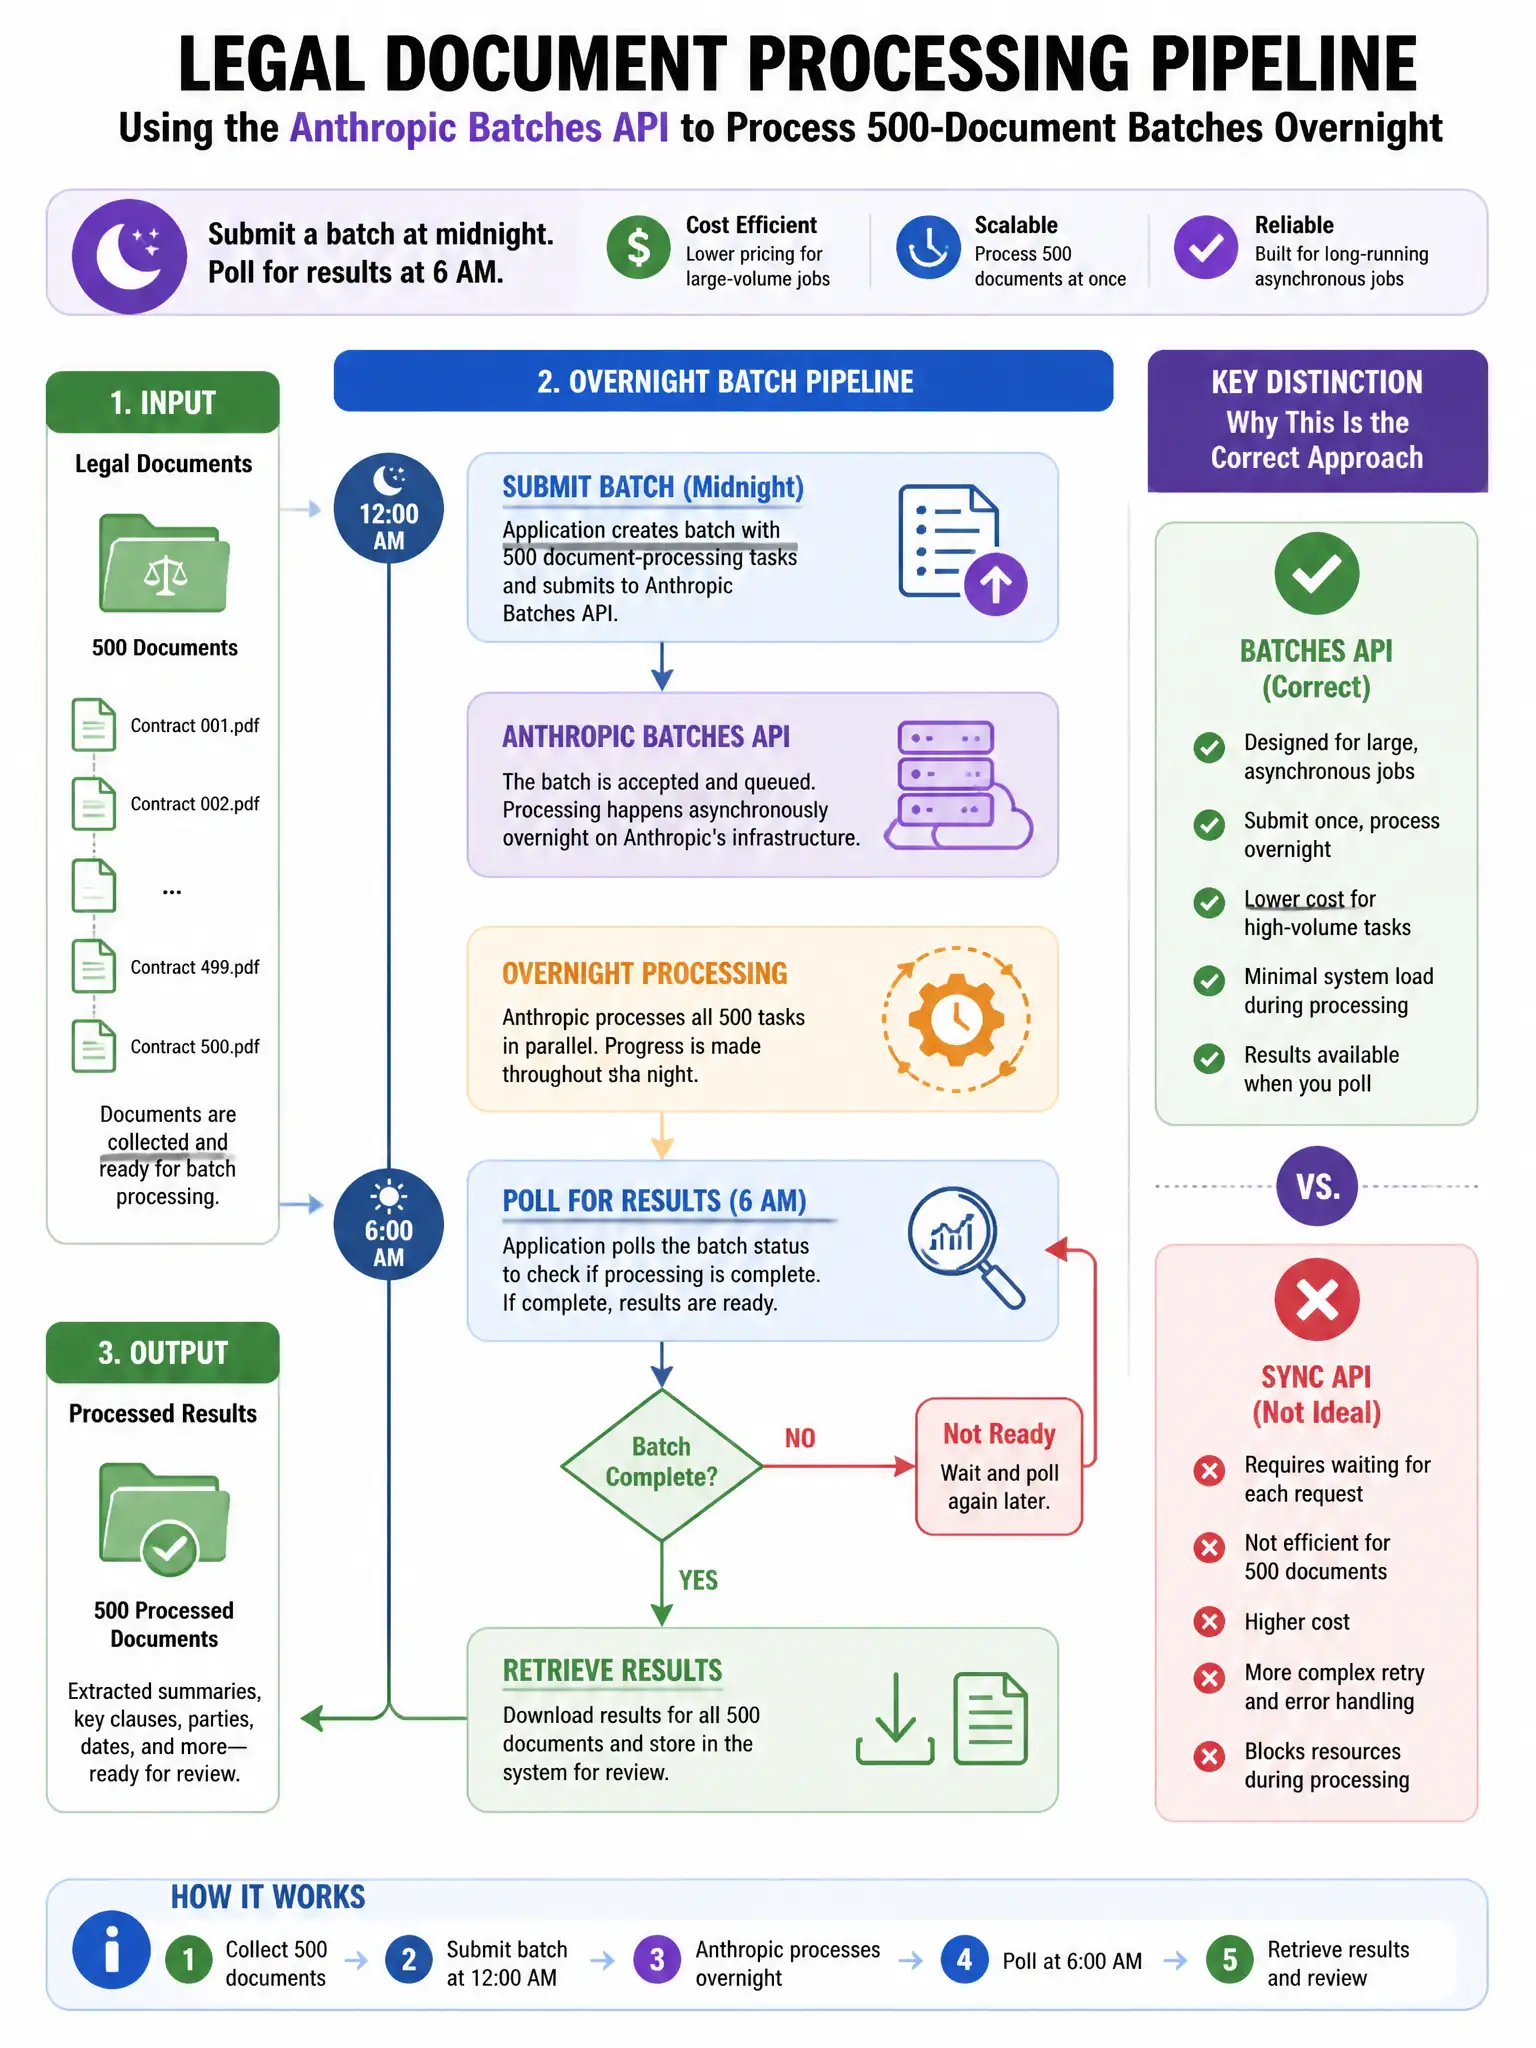
A legal document processing pipeline uses the Anthropic Batches API to process 500-document batches overnight. The system submits a batch at midnight and polls for results at 6 AM. Recently, the team discovered that batches are returning with a mix of 'succeeded' and 'errored' results — approximately 3-5% error rate per batch. The errored requests include a mixture of invalid_request_error and overloaded_error types. What is the correct handling architecture for production reliability?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you need to split errors by type. Discard invalid_request_error results because malformed inputs will fail again, and resubmit overloaded_error results in a follow-up batch after applying input validation fixes to the invalid set.
Full Explanation
The correct production handling for mixed batch errors requires error-type discrimination. invalid_request_error results from malformed inputs (too many tokens, invalid parameters, unsupported content types) — resubmitting them will always produce the same error, wasting batch quota. These should be discarded from the retry batch immediately or quarantined for human review and input remediation, with input validation fixes applied to the invalid_request set before any future submission. overloaded_error results are transient — the request was valid but the system was temporarily overloaded during processing; these should be resubmitted in a follow-up batch. This two-path handling maximizes batch efficiency and ensures eventual consistency. The larger-batch claim is factually incorrect — there is no documented prioritization benefit for larger batch sizes, and it doesn't address error type handling. The synchronous retry approach that resubmits all failed requests individually via the real-time Messages API is valid in some architectures but expensive — the question asks for production reliability architecture where cost efficiency matters; a follow-up batch is more appropriate. The native retry-policy claim describes fictional API functionality — the Batches API does not have a native retry_config parameter as described.