
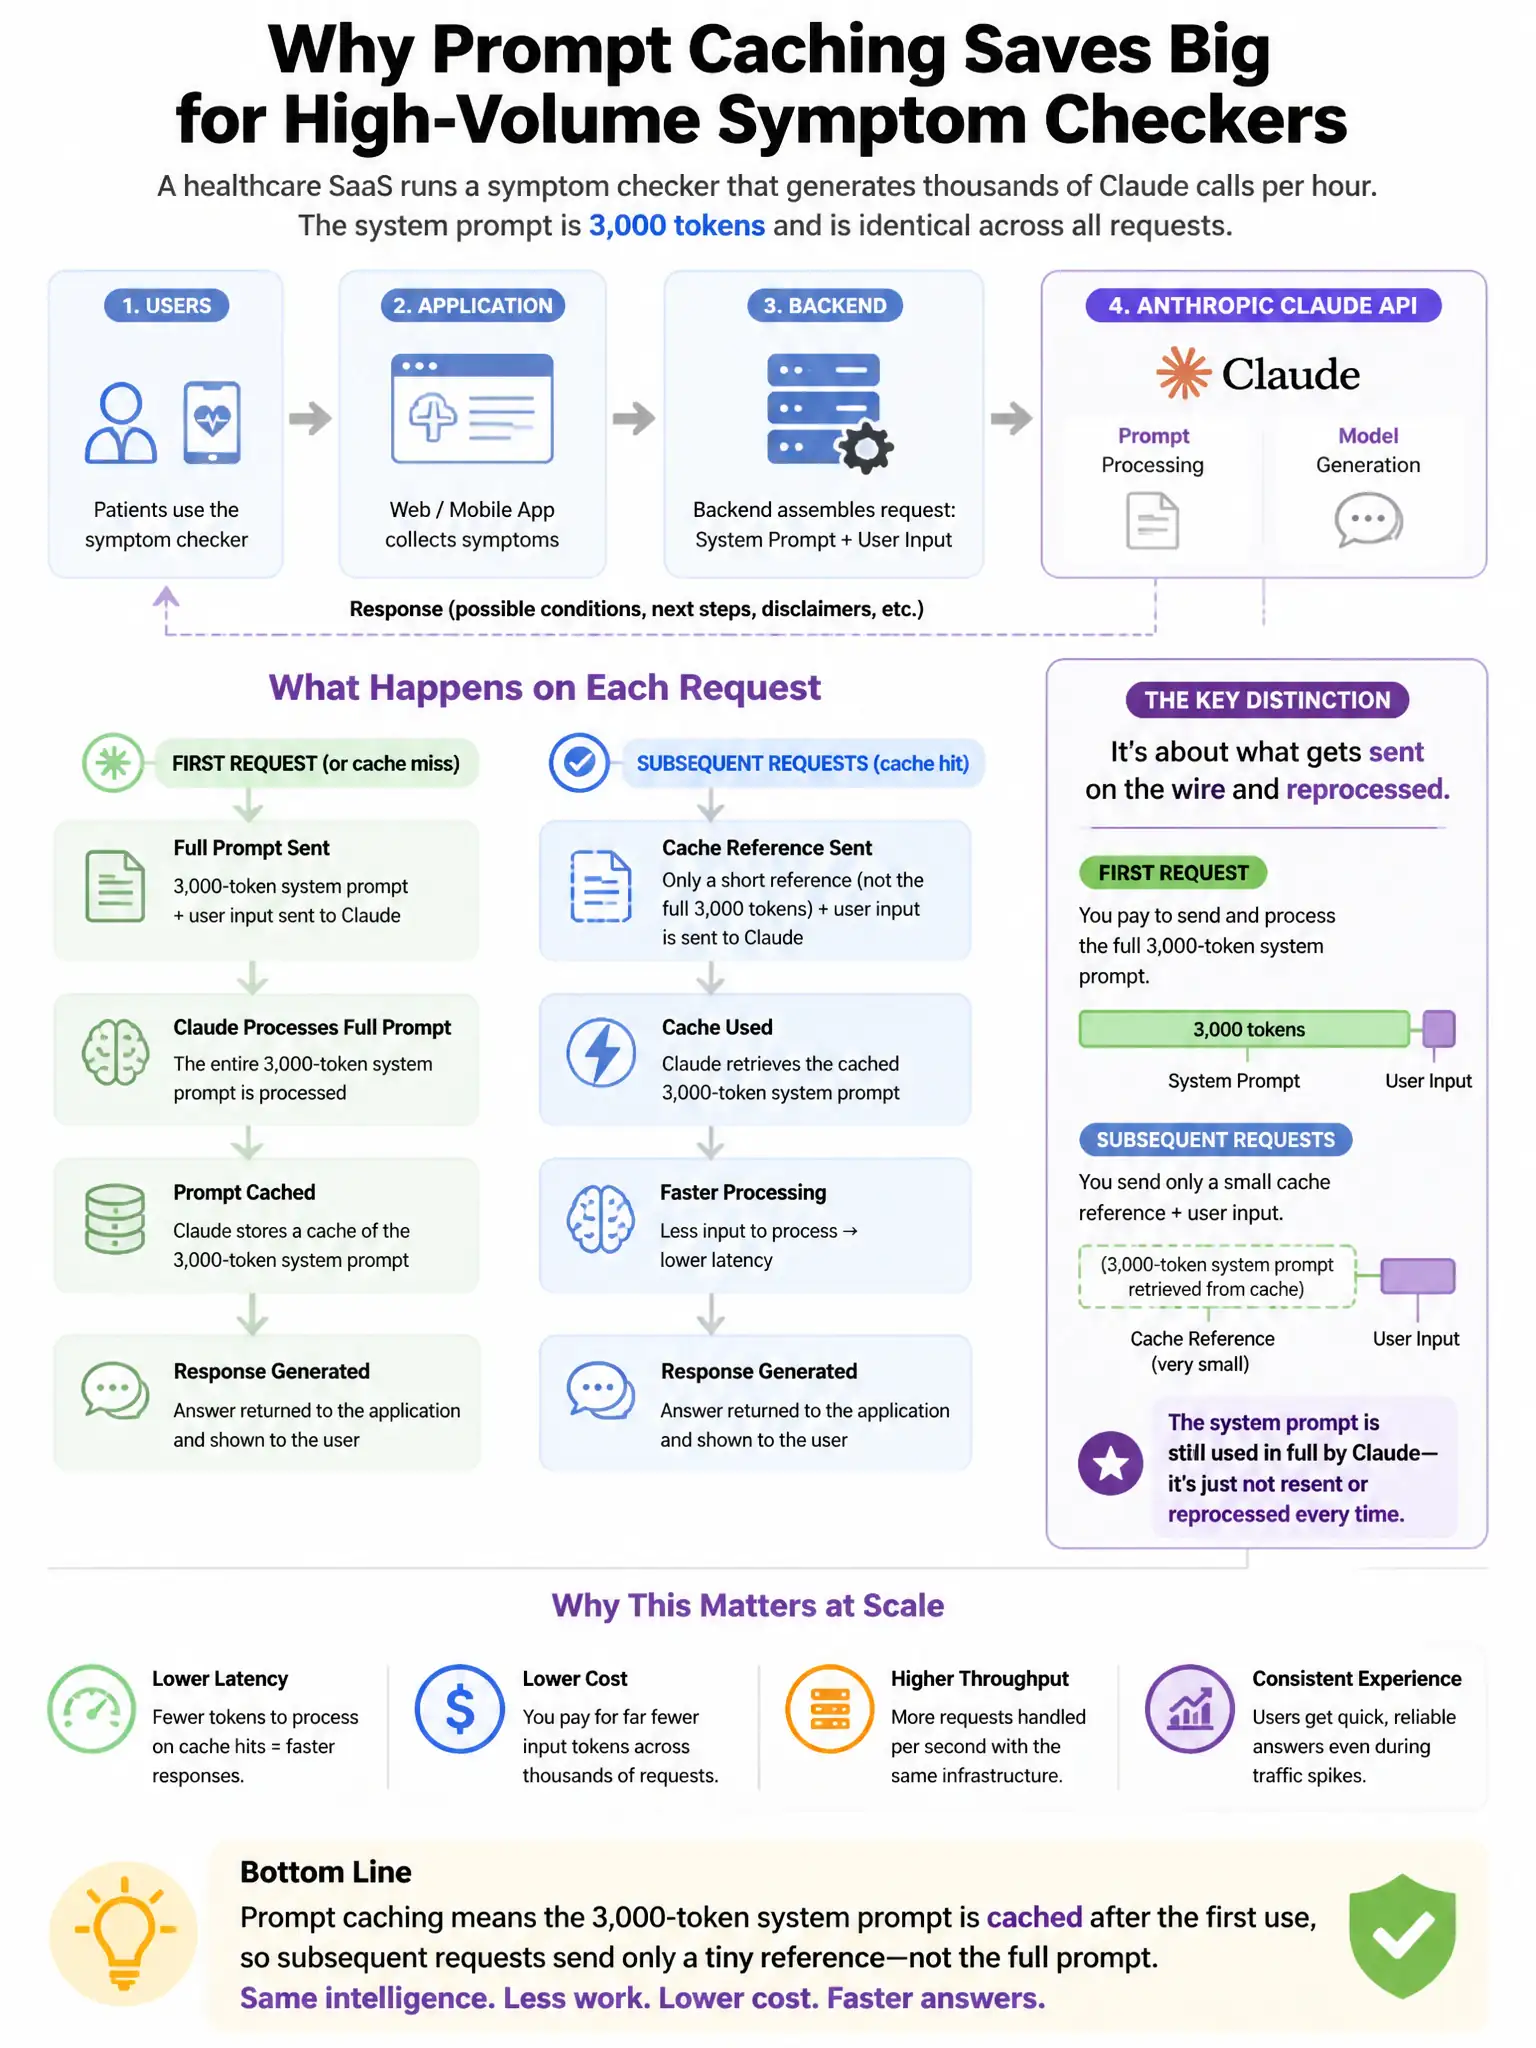
A healthcare SaaS company runs a symptom checker that generates thousands of Claude calls per hour. The system prompt is 3,000 tokens and is identical across all requests. They are paying for the system prompt tokens on every single API call. A colleague suggests enabling prompt caching using cache_control: {"type": "ephemeral"} on the system prompt. The team wants to understand the economic tradeoff. Cached read pricing is approximately 10% of standard input pricing. Cache write operations have the same cost as normal input but the cache TTL is 5 minutes. Their average request rate is 200 requests per minute. What is the expected cost reduction on system prompt tokens?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — at 200 requests/minute, the 5-minute cache window covers about 1,000 calls: one full-price write plus 999 reads at 10% cost. That averages to roughly 10% of the original system-prompt cost, so you're looking at about 90% reduction.
Full Explanation
At 200 requests/minute over the 5-minute TTL window, each cache instance serves about 1,000 requests: one cache write at full input cost plus 999 cache reads at 10% of standard input cost. The per-request average is (1 1.0 + 999 0.1) / 1000 = 0.1009, about 10% of original cost, so the reduction is about 90%. The 10%-reduction claim misframes the math: cached reads cost 10% of standard, but after amortizing the write the total is about 10% of original, meaning 90% saved. The no-reduction claim is wrong because at 200 requests/minute the cache stays warm; the 5-minute TTL is easily maintained and the write is amortized across about 1,000 reads. The 50%-reduction claim would fit extremely low request rates with frequent misses, but here the hit rate approaches 99.9%.