
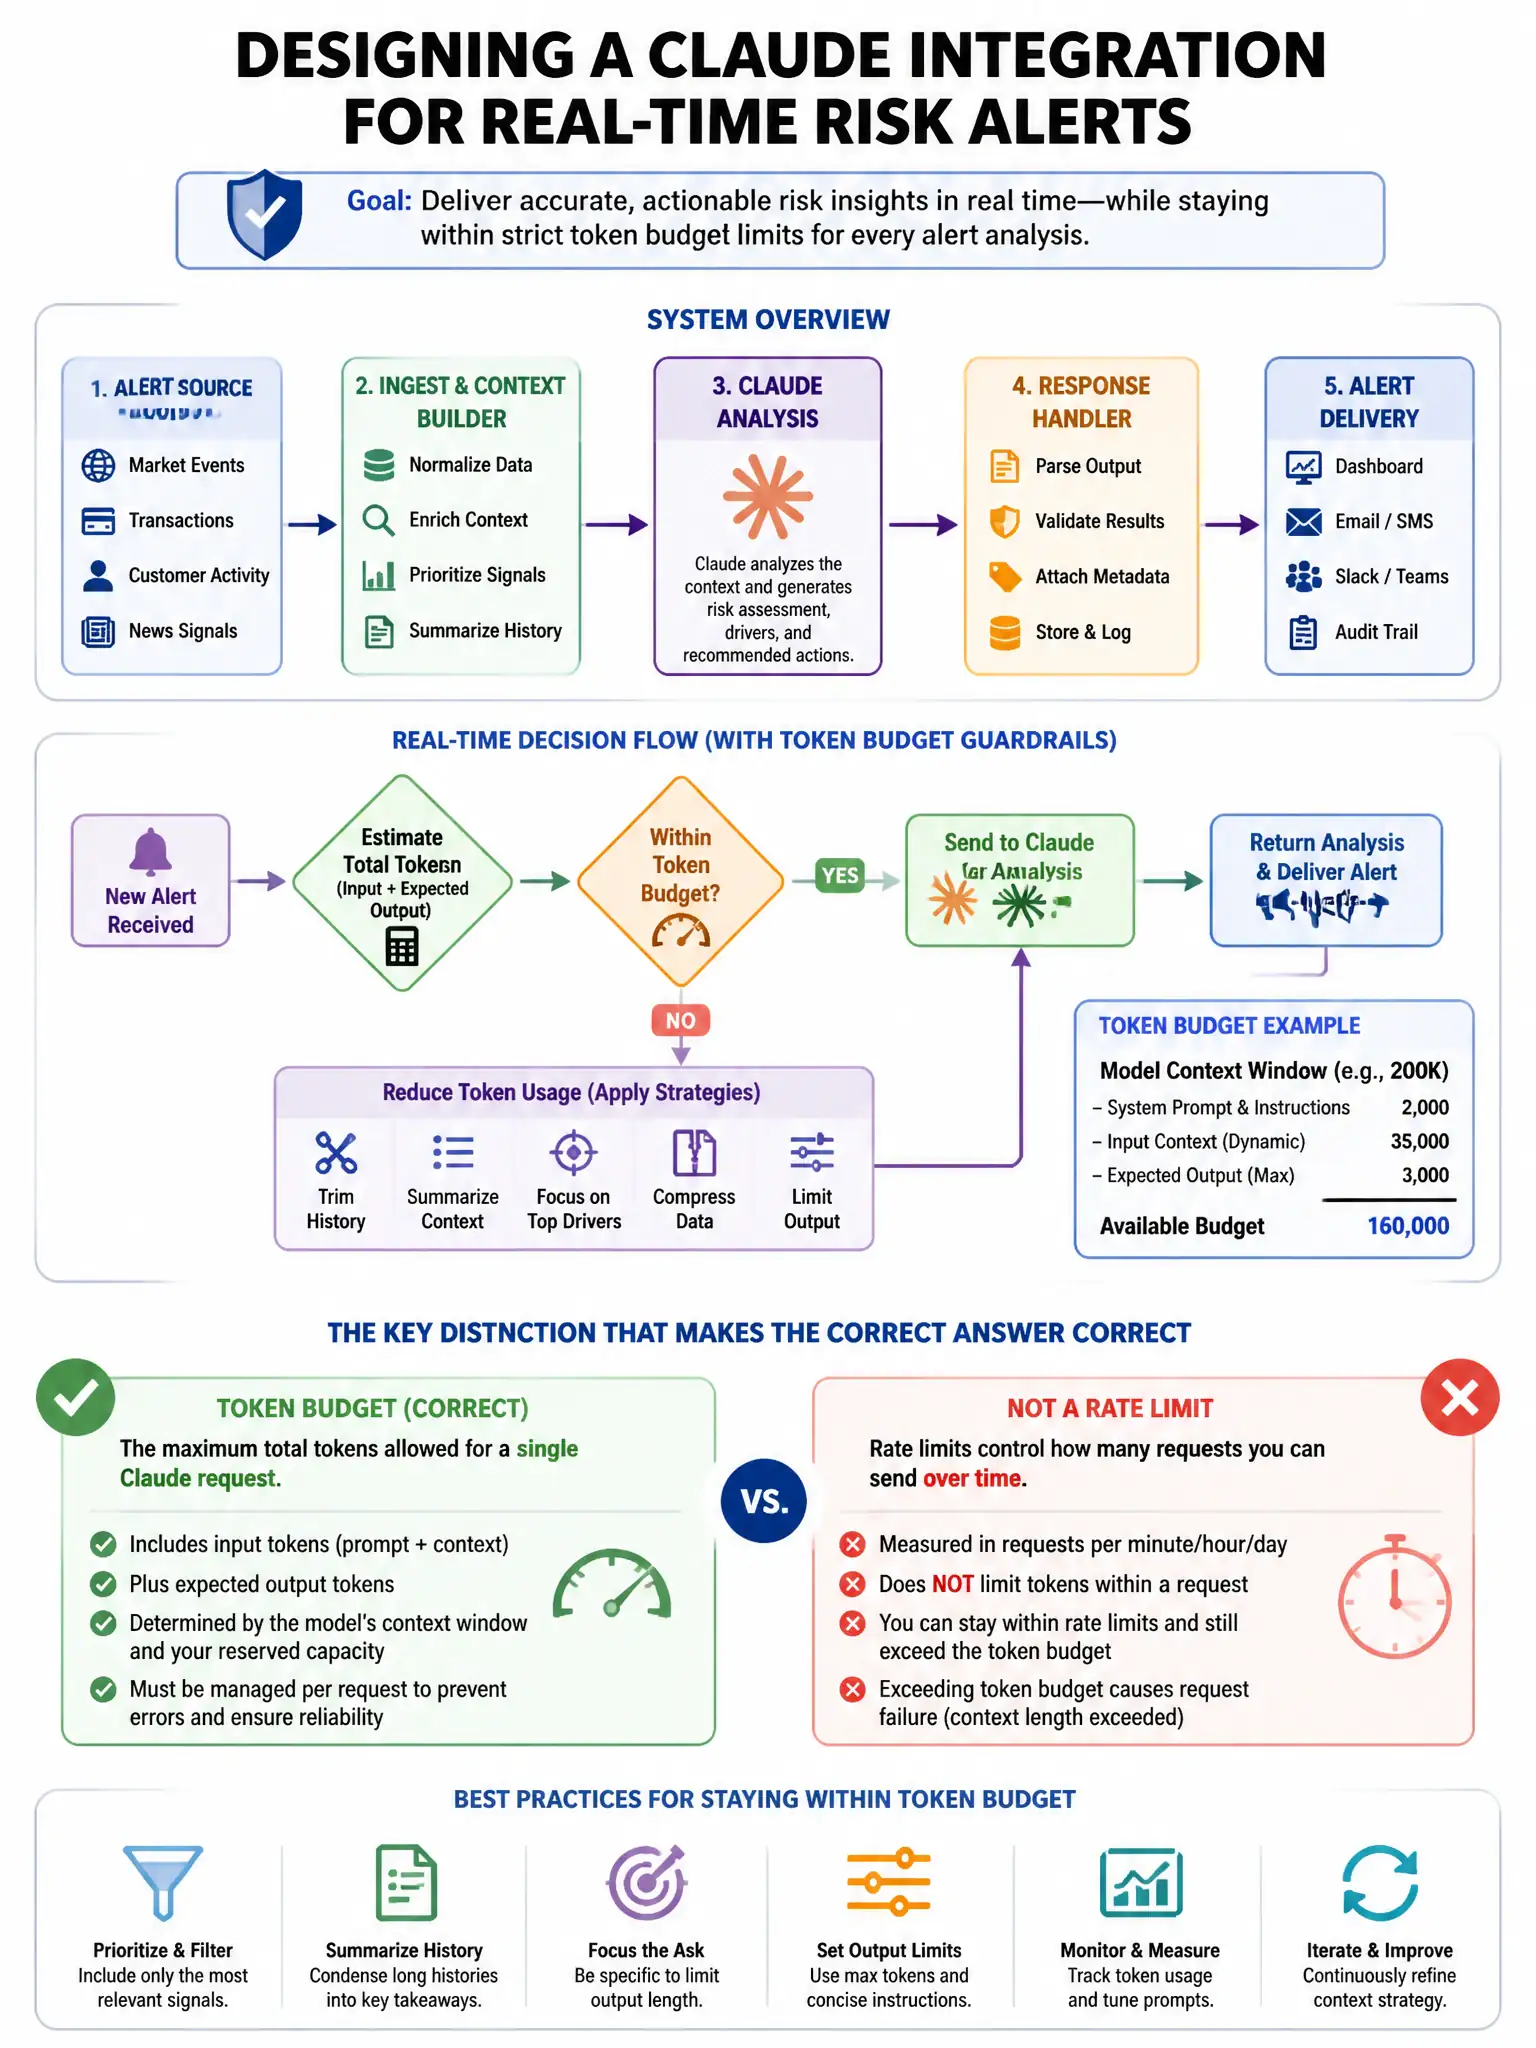
A financial services company is designing a Claude integration for real-time risk alerts. Their system must handle token budget constraints carefully: each alert analysis must stay within a specific token budget to control costs. When Claude produces a response that approaches the max_tokens limit and appears truncated, the current implementation silently delivers the truncated response to downstream risk systems. This has caused incidents where incomplete risk assessments were acted upon. What is the correct error handling approach?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — you check the API response's stop_reason field. If it says max_tokens instead of end_turn, you treat the alert as incomplete and retry with a bigger limit or use a fallback workflow. That keeps truncated risk assessments from sneaking downstream.
Full Explanation
The stop_reason field is the definitive signal for how Claude's generation ended. end_turn means Claude voluntarily stopped (natural completion). max_tokens means generation was forcibly cut off. For risk assessments, a max_tokens stop is a data quality event, not normal operation — the assessment is provably incomplete. The correct handling is to either increase max_tokens and retry, or trigger a fallback (e.g., human review, simplified prompt) rather than silently delivering incomplete output. The approach of increasing max_tokens to 8,192 for all requests wastes tokens on short responses and may still truncate unusually long analyses. The approach of adding a system-prompt suffix instructing Claude to always complete within a fixed number of sentences is unreliable — Claude may misjudge response length and the instruction doesn't prevent truncation when the actual content requires more tokens. The approach of post-processing all responses with a sentence-completeness classifier and appending a warning label can detect some truncations but is heuristic; checking stop_reason is authoritative and requires no inference.