
A team is building a classification system where Claude must categorize customer support tickets into one of 12 defined categories. Claude sometimes creates new categories not in the defined list. Which technique provides the strongest guarantee of constraining output to the defined taxonomy?
Select an answer to reveal the explanation.
Short Explanation
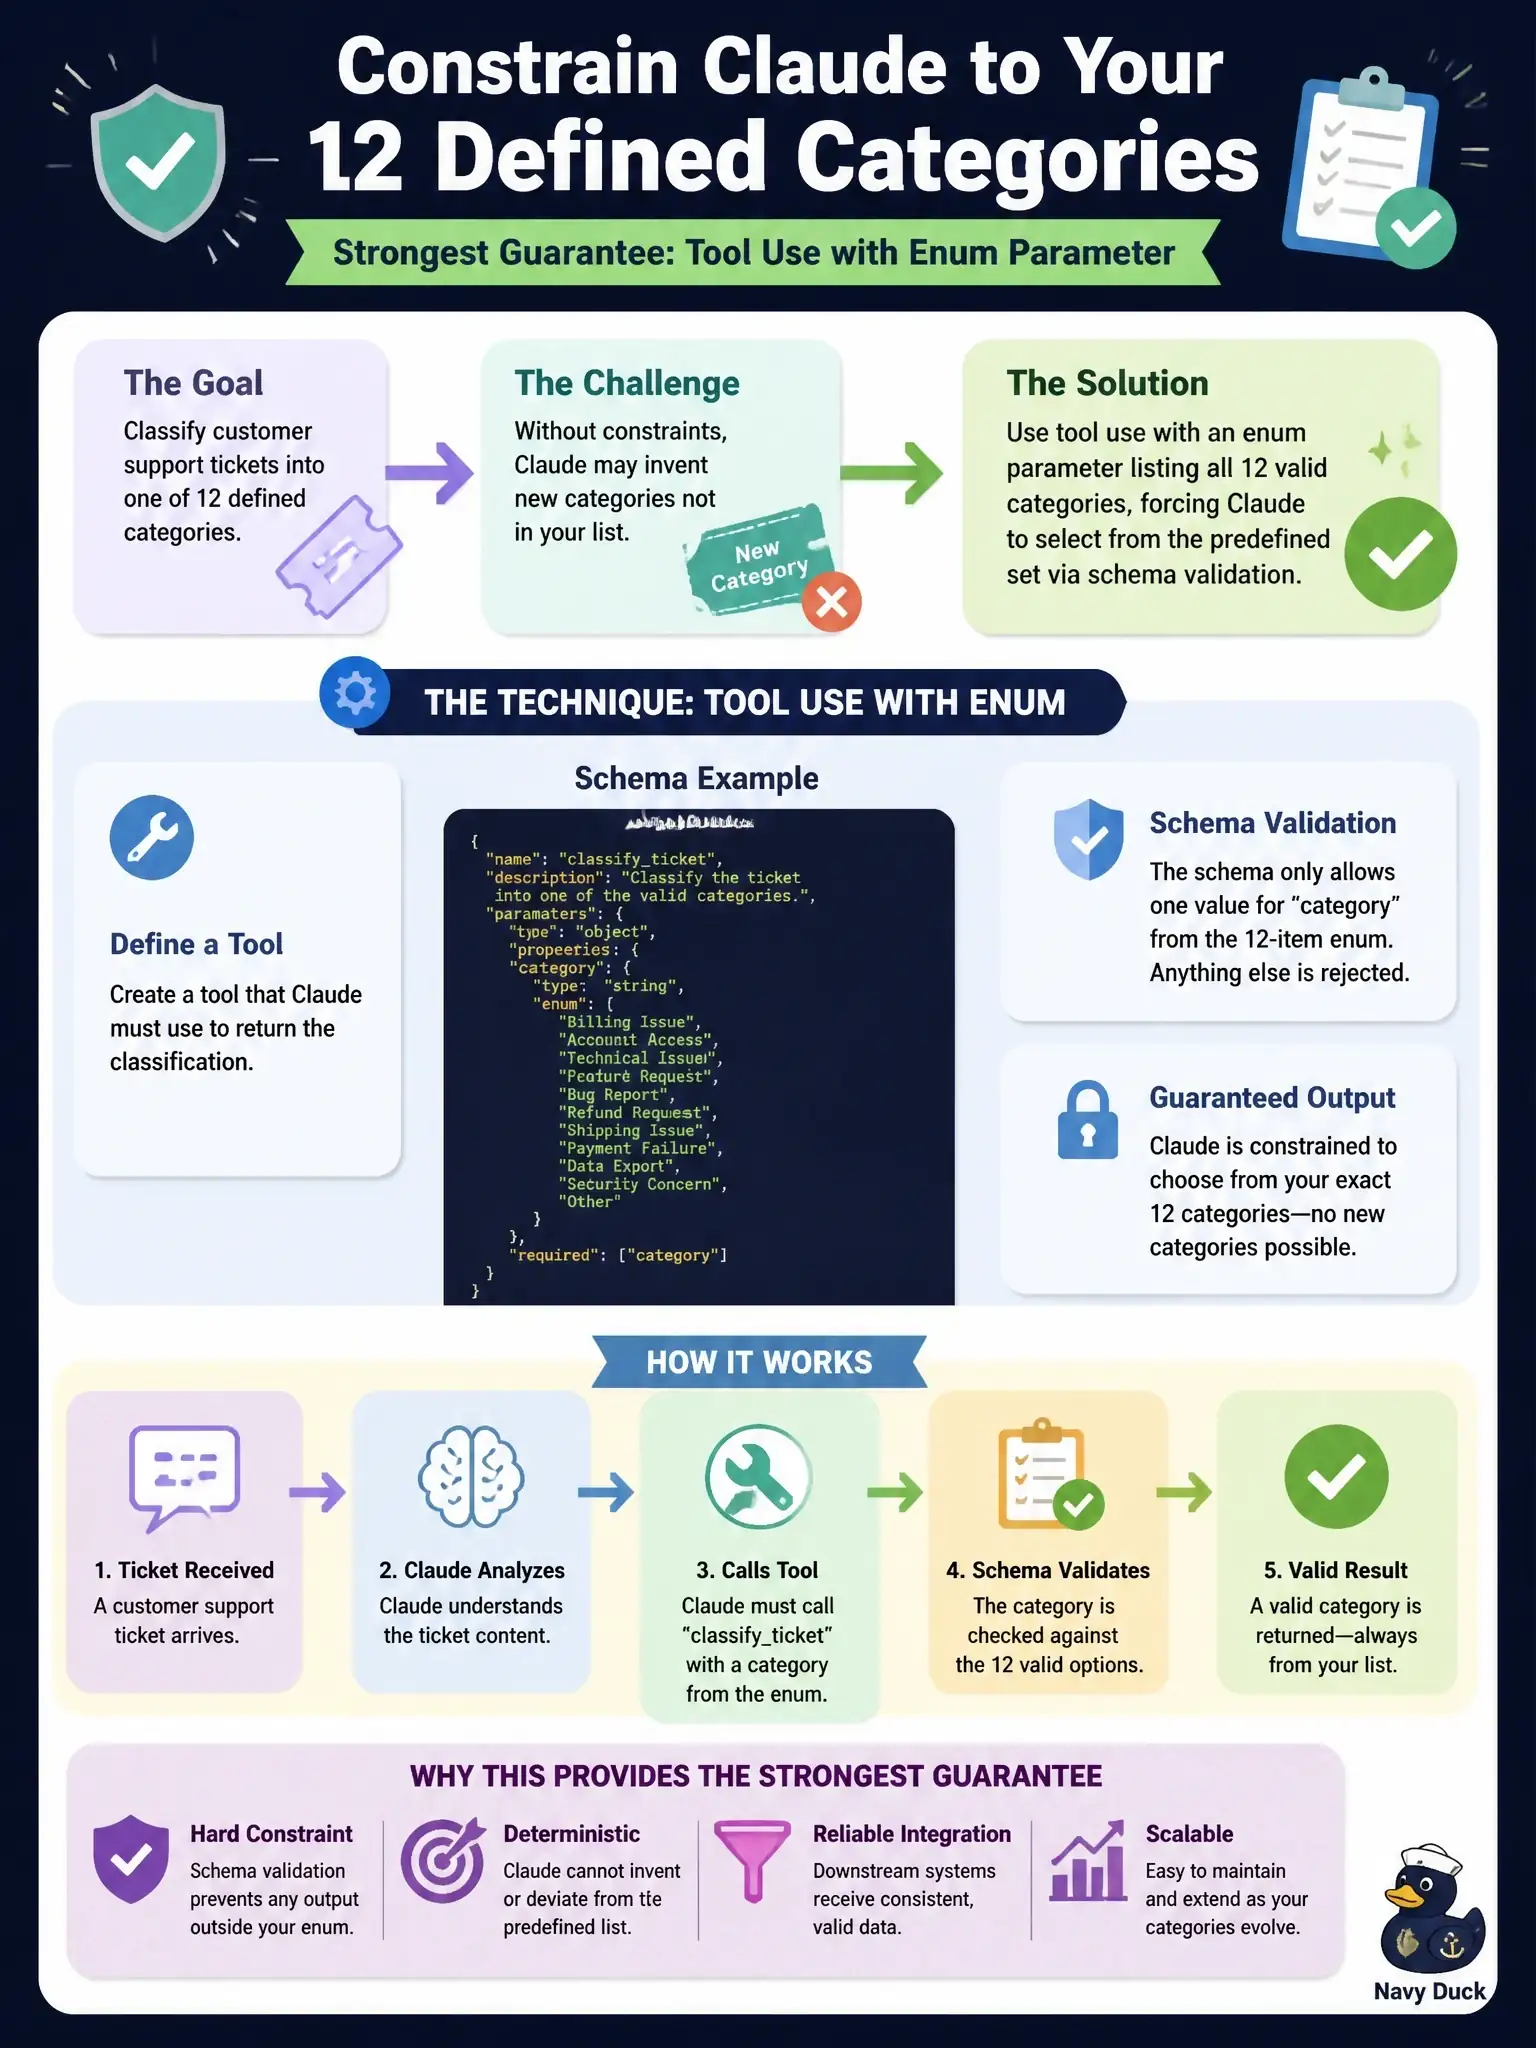
You want the tool-use enum method because schema validation forces Claude to pick one of the 12 categories. Temperature 0, prompt lists, XML tags, and self-checks are softer and can still drift.
Full Explanation
The strongest guarantee comes from using tool use with a tool that has an enum parameter listing all 12 valid categories, forcing Claude to select from the predefined set via schema validation. JSON schema enums are validated at the API level, so Claude cannot return a category outside the defined list without triggering a schema validation error. This is a hard constraint rather than a prompt-following expectation. The approach that lists the 12 categories in the system prompt and sets temperature to 0 is insufficient because temperature 0 reduces randomness but doesn't prevent schema violations or invented categories. The approach that enumerates the 12 categories with XML tags, uses a prefilled assistant response beginning with <category>, and includes a few-shot example is reliable through prompt engineering, but it is a softer constraint that can be overcome in edge cases. The approach that instructs Claude to check that its chosen category appears in the list of 12 before writing its final answer is also weaker because it relies on Claude's own self-check rather than an external validation layer. If an invalid category is catastrophic, such as misrouting a critical ticket, use the enum method; if occasional 'unclear' or 'other' classifications are acceptable, the tag-based method allows that flexibility.