
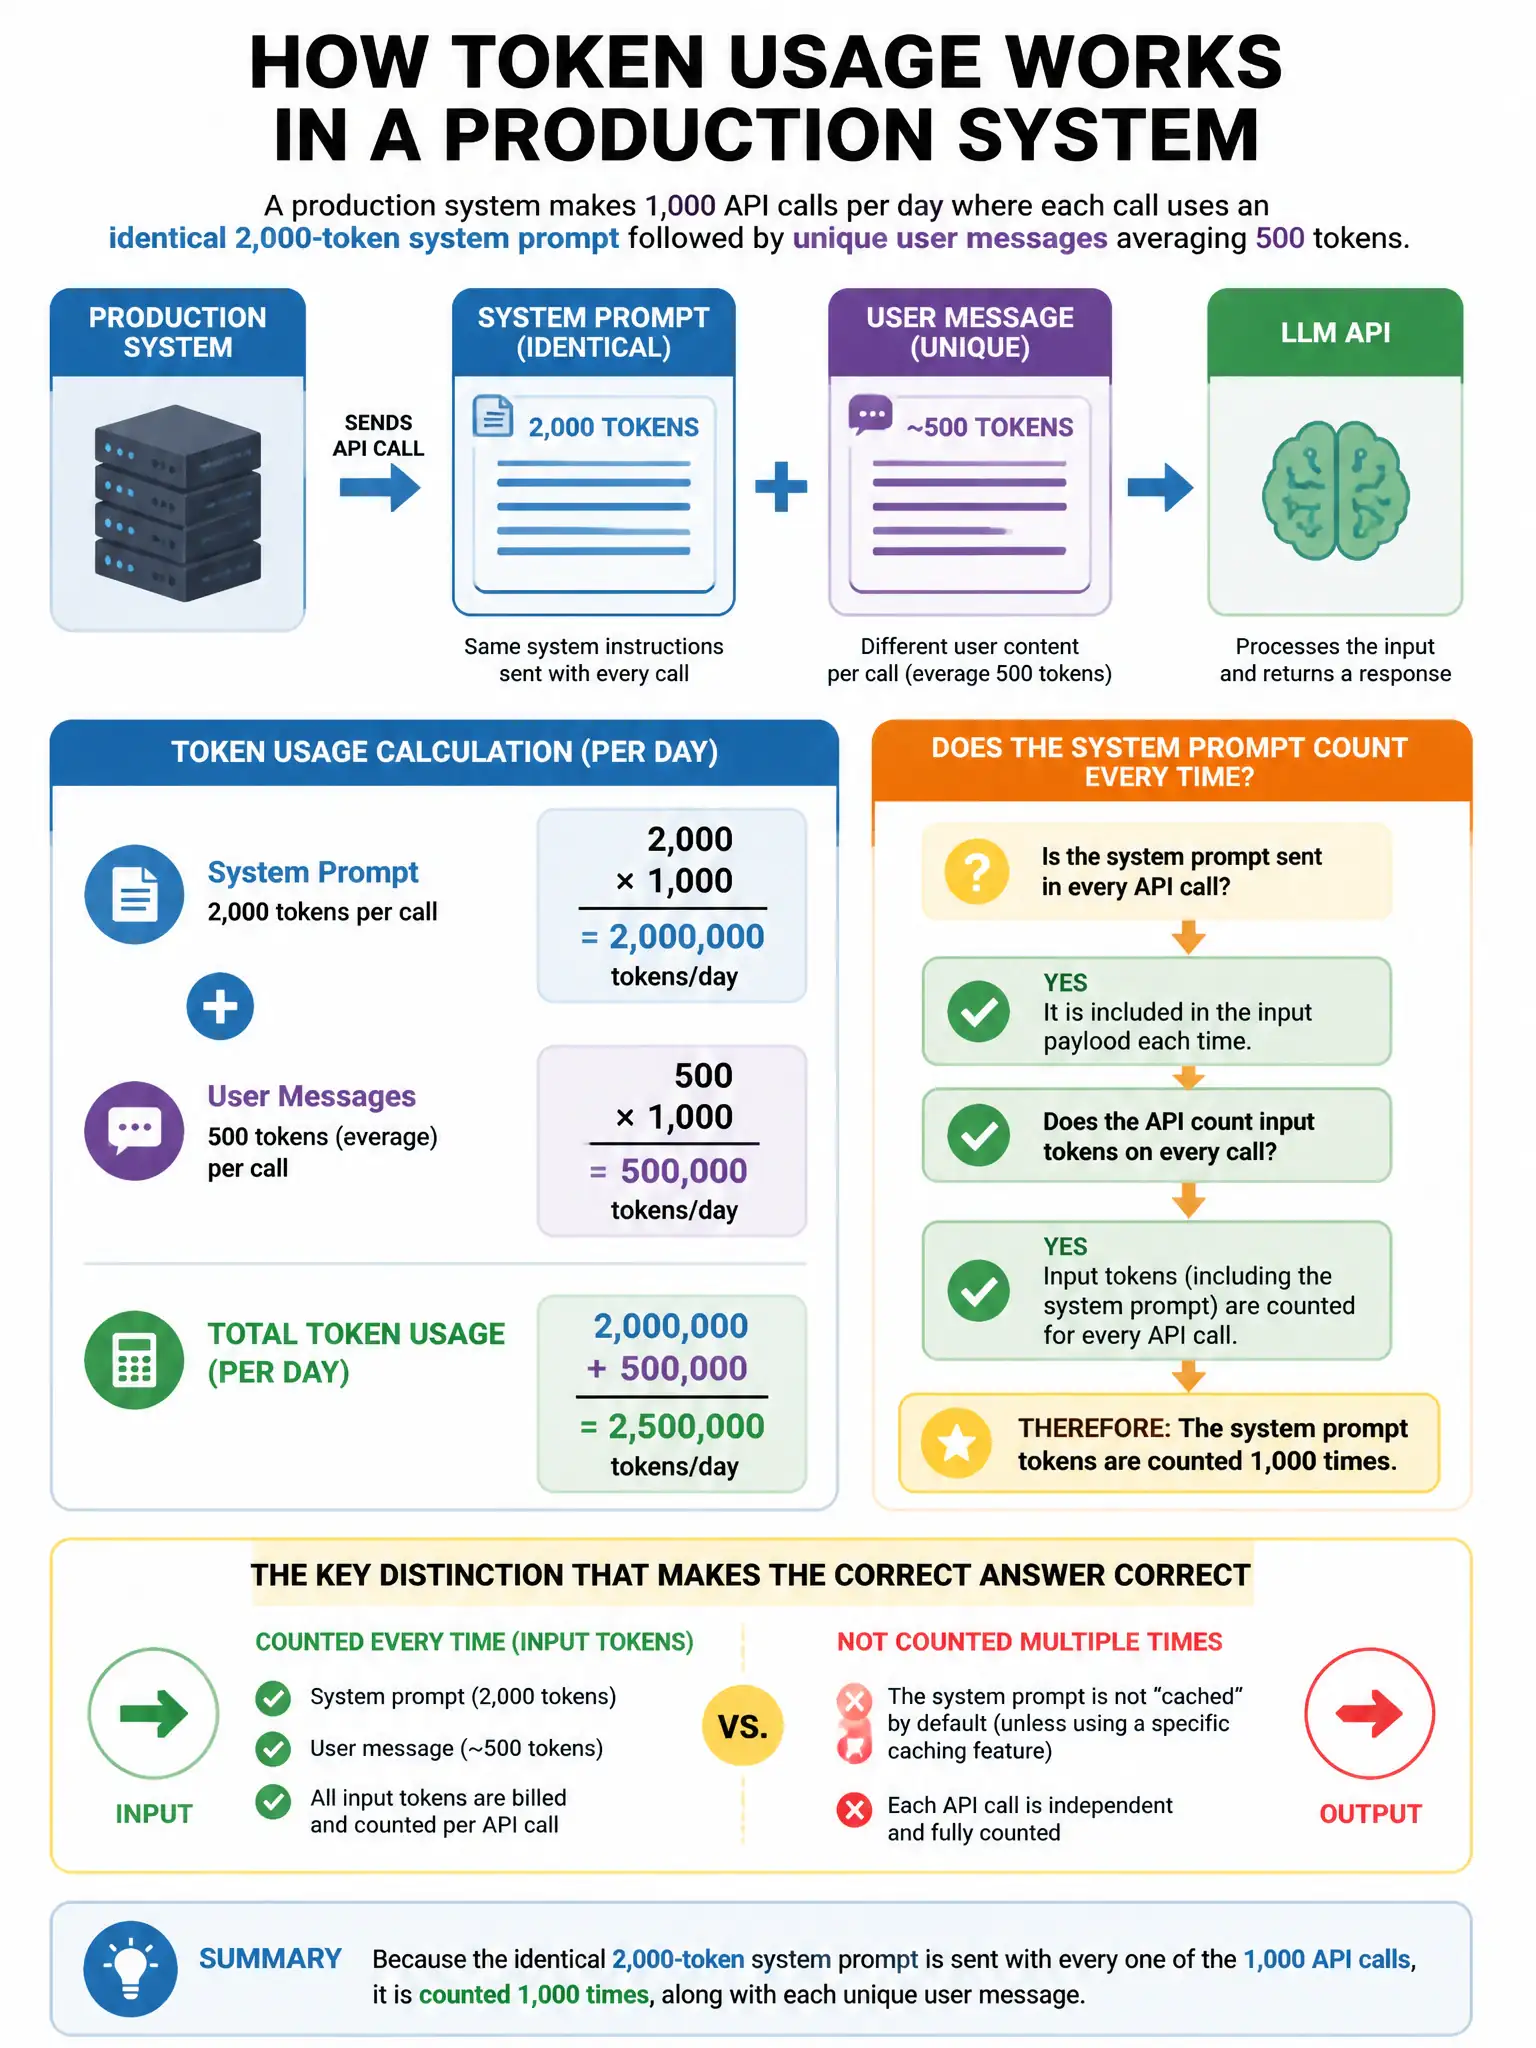
A production system makes 1,000 API calls per day where each call uses an identical 2,000-token system prompt followed by unique user messages averaging 500 tokens. The architect wants to reduce input token costs. Which feature should be applied?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal — apply ephemeral cache control to the system prompt. Anthropic caches the prompt's KV state, so later calls within the cache TTL get charged reduced cache read prices instead of full input token prices.
Full Explanation
Prompt caching is the correct solution. By adding cache_control: {type: 'ephemeral'} to the system prompt content block, Anthropic caches the computed KV state of the prompt. Subsequent calls within the cache TTL (approximately 5 minutes, reset on each cache hit) are charged cache read prices — significantly lower than full input token pricing. With 1,000 calls/day sharing a 2,000-token system prompt, the savings are substantial. The compression approach reduces token count slightly but at the cost of instruction quality; savings are modest and the tradeoff is poor. The move-to-user-message approach doesn't reduce costs — the tokens are still processed as input regardless of their message role. The split-across-calls approach is architecturally incorrect — each call needs all instructions to operate correctly, and splitting breaks the instruction context.