
A developer wants to build a system where Claude reads and analyzes content from websites. What architecture is required?
Select an answer to reveal the explanation.
Short Explanation
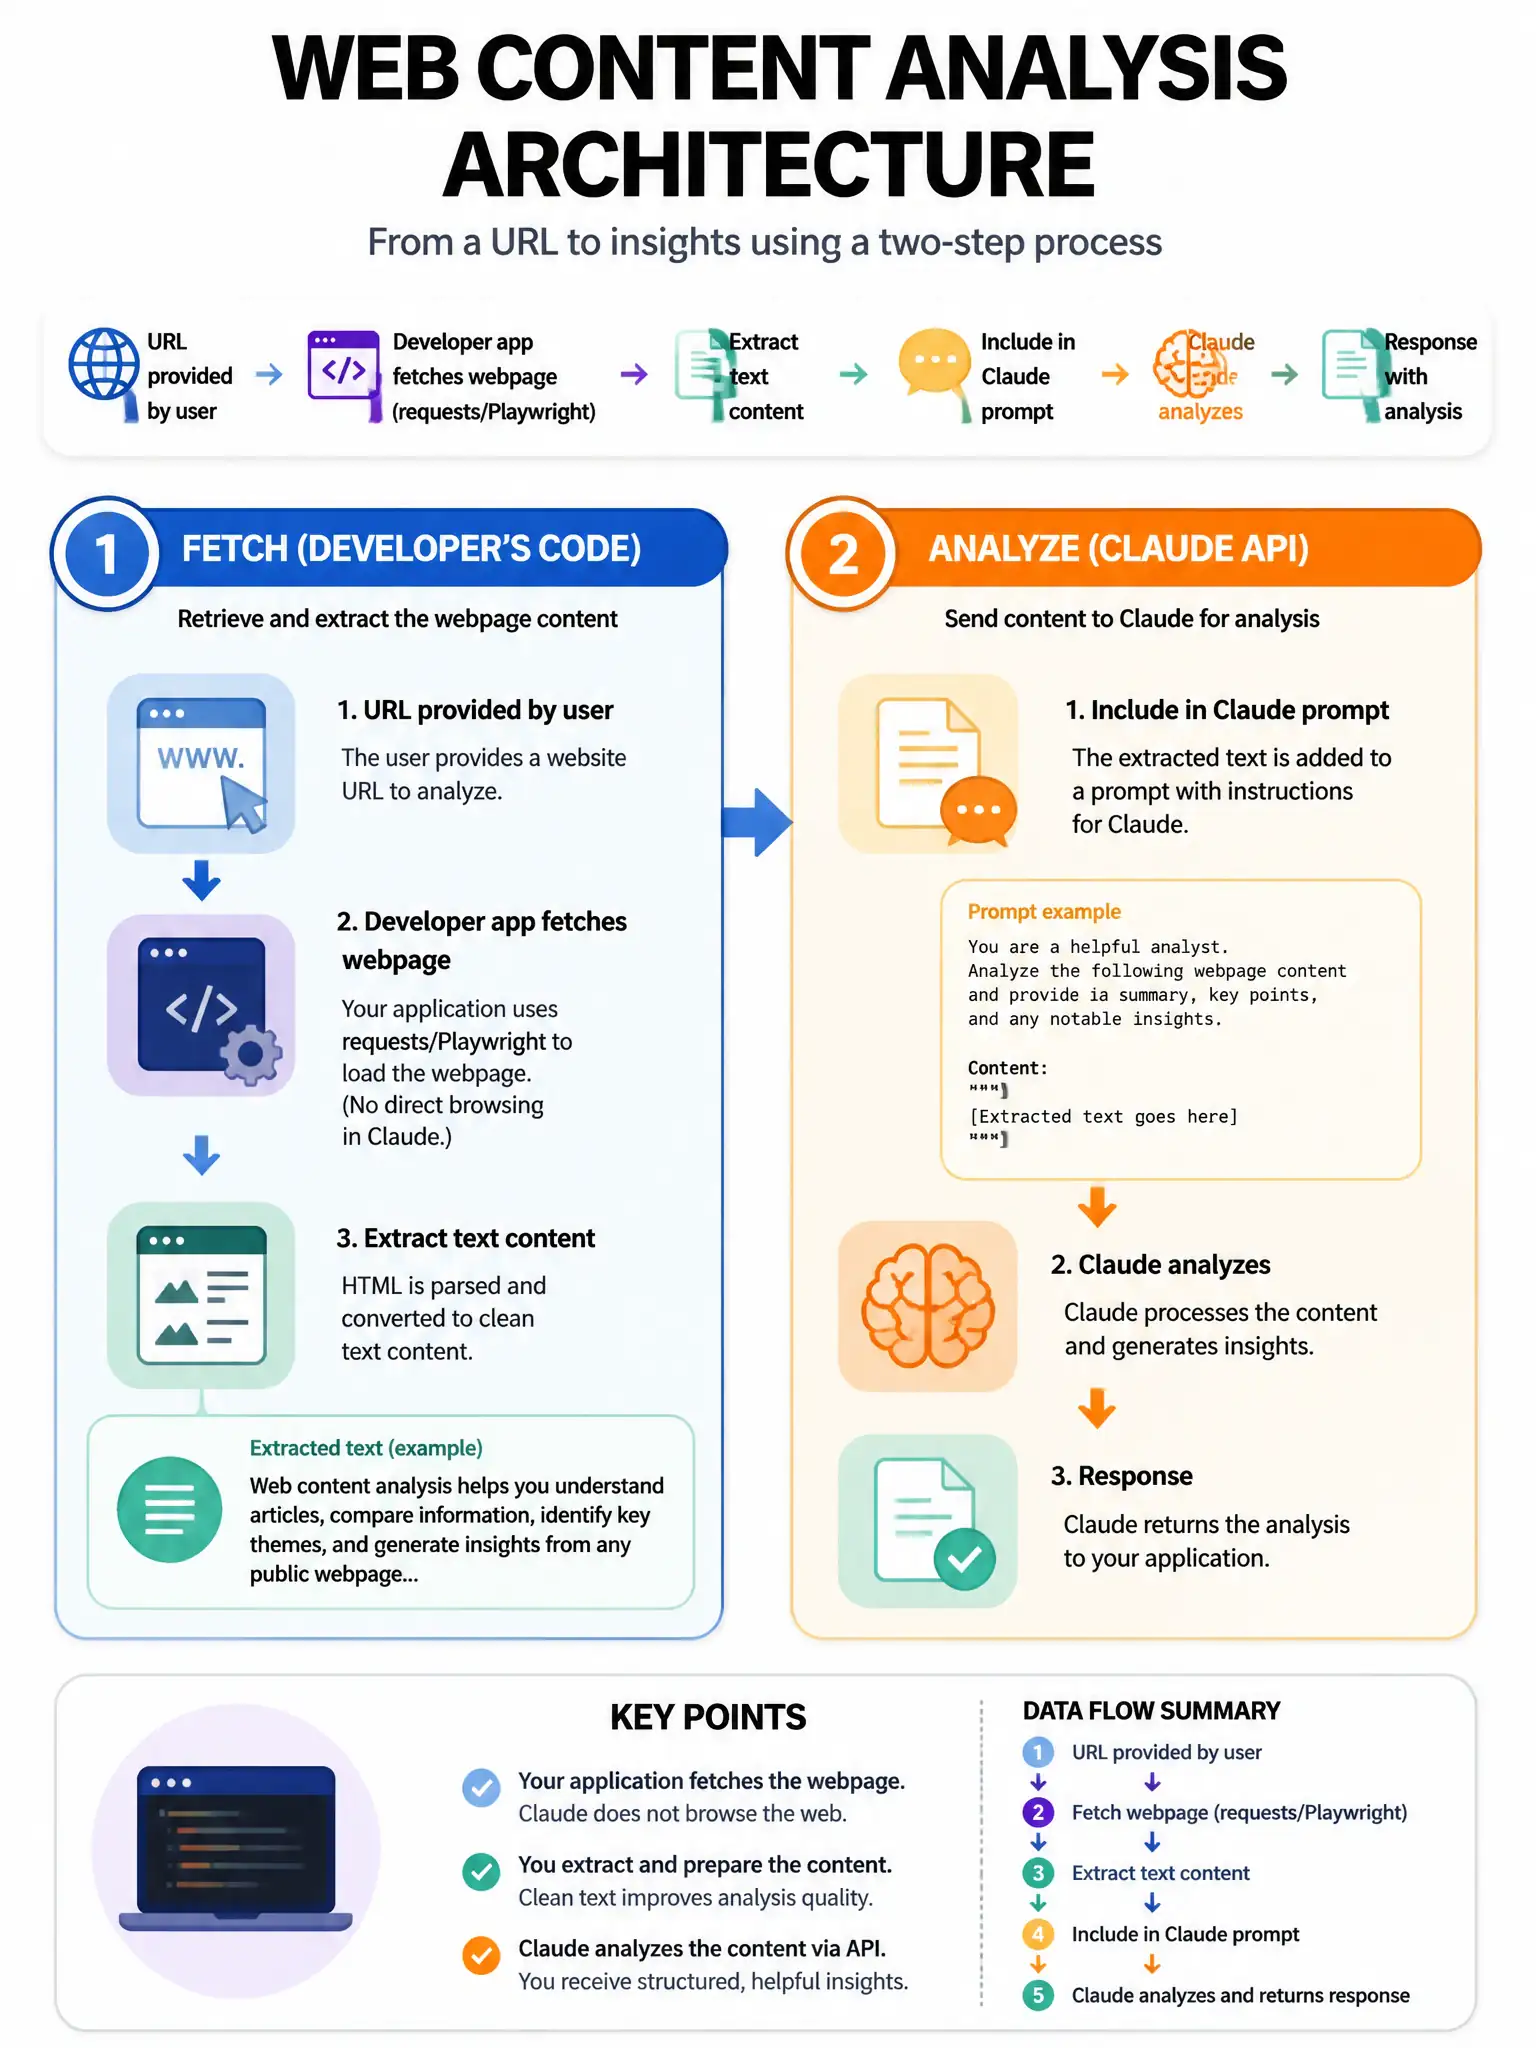
Claude can't browse URLs on its own. You need to fetch the page yourself, extract the text, and pass that text into the Claude API prompt. Claude analyzes the content you provide.
Full Explanation
Claude has no built-in web fetching capability in the standard API. For web content analysis, the architecture is: your application fetches the webpage using an HTTP library (requests in Python, fetch in Node.js), extracts meaningful text content (using BeautifulSoup, Playwright, Puppeteer, or a content extraction API), includes the extracted text in the Claude API prompt, and Claude analyzes the text. Some Claude-powered products implement web search as a tool at the product layer, but this is not a base API feature. The approach of simply providing the URL to Claude is wrong because Claude can't fetch URLs. The approach requiring a special web browsing mode activated by a 'browse_web: true' parameter is wrong because it invents a non-existent parameter. The approach saying this is not possible is wrong because it is possible, just requires the developer to do the fetching.