
Anthropic conducts safety evaluations (evals) before releasing new Claude models. What is the PRIMARY purpose of these evaluations?
Select an answer to reveal the explanation.
Short Explanation
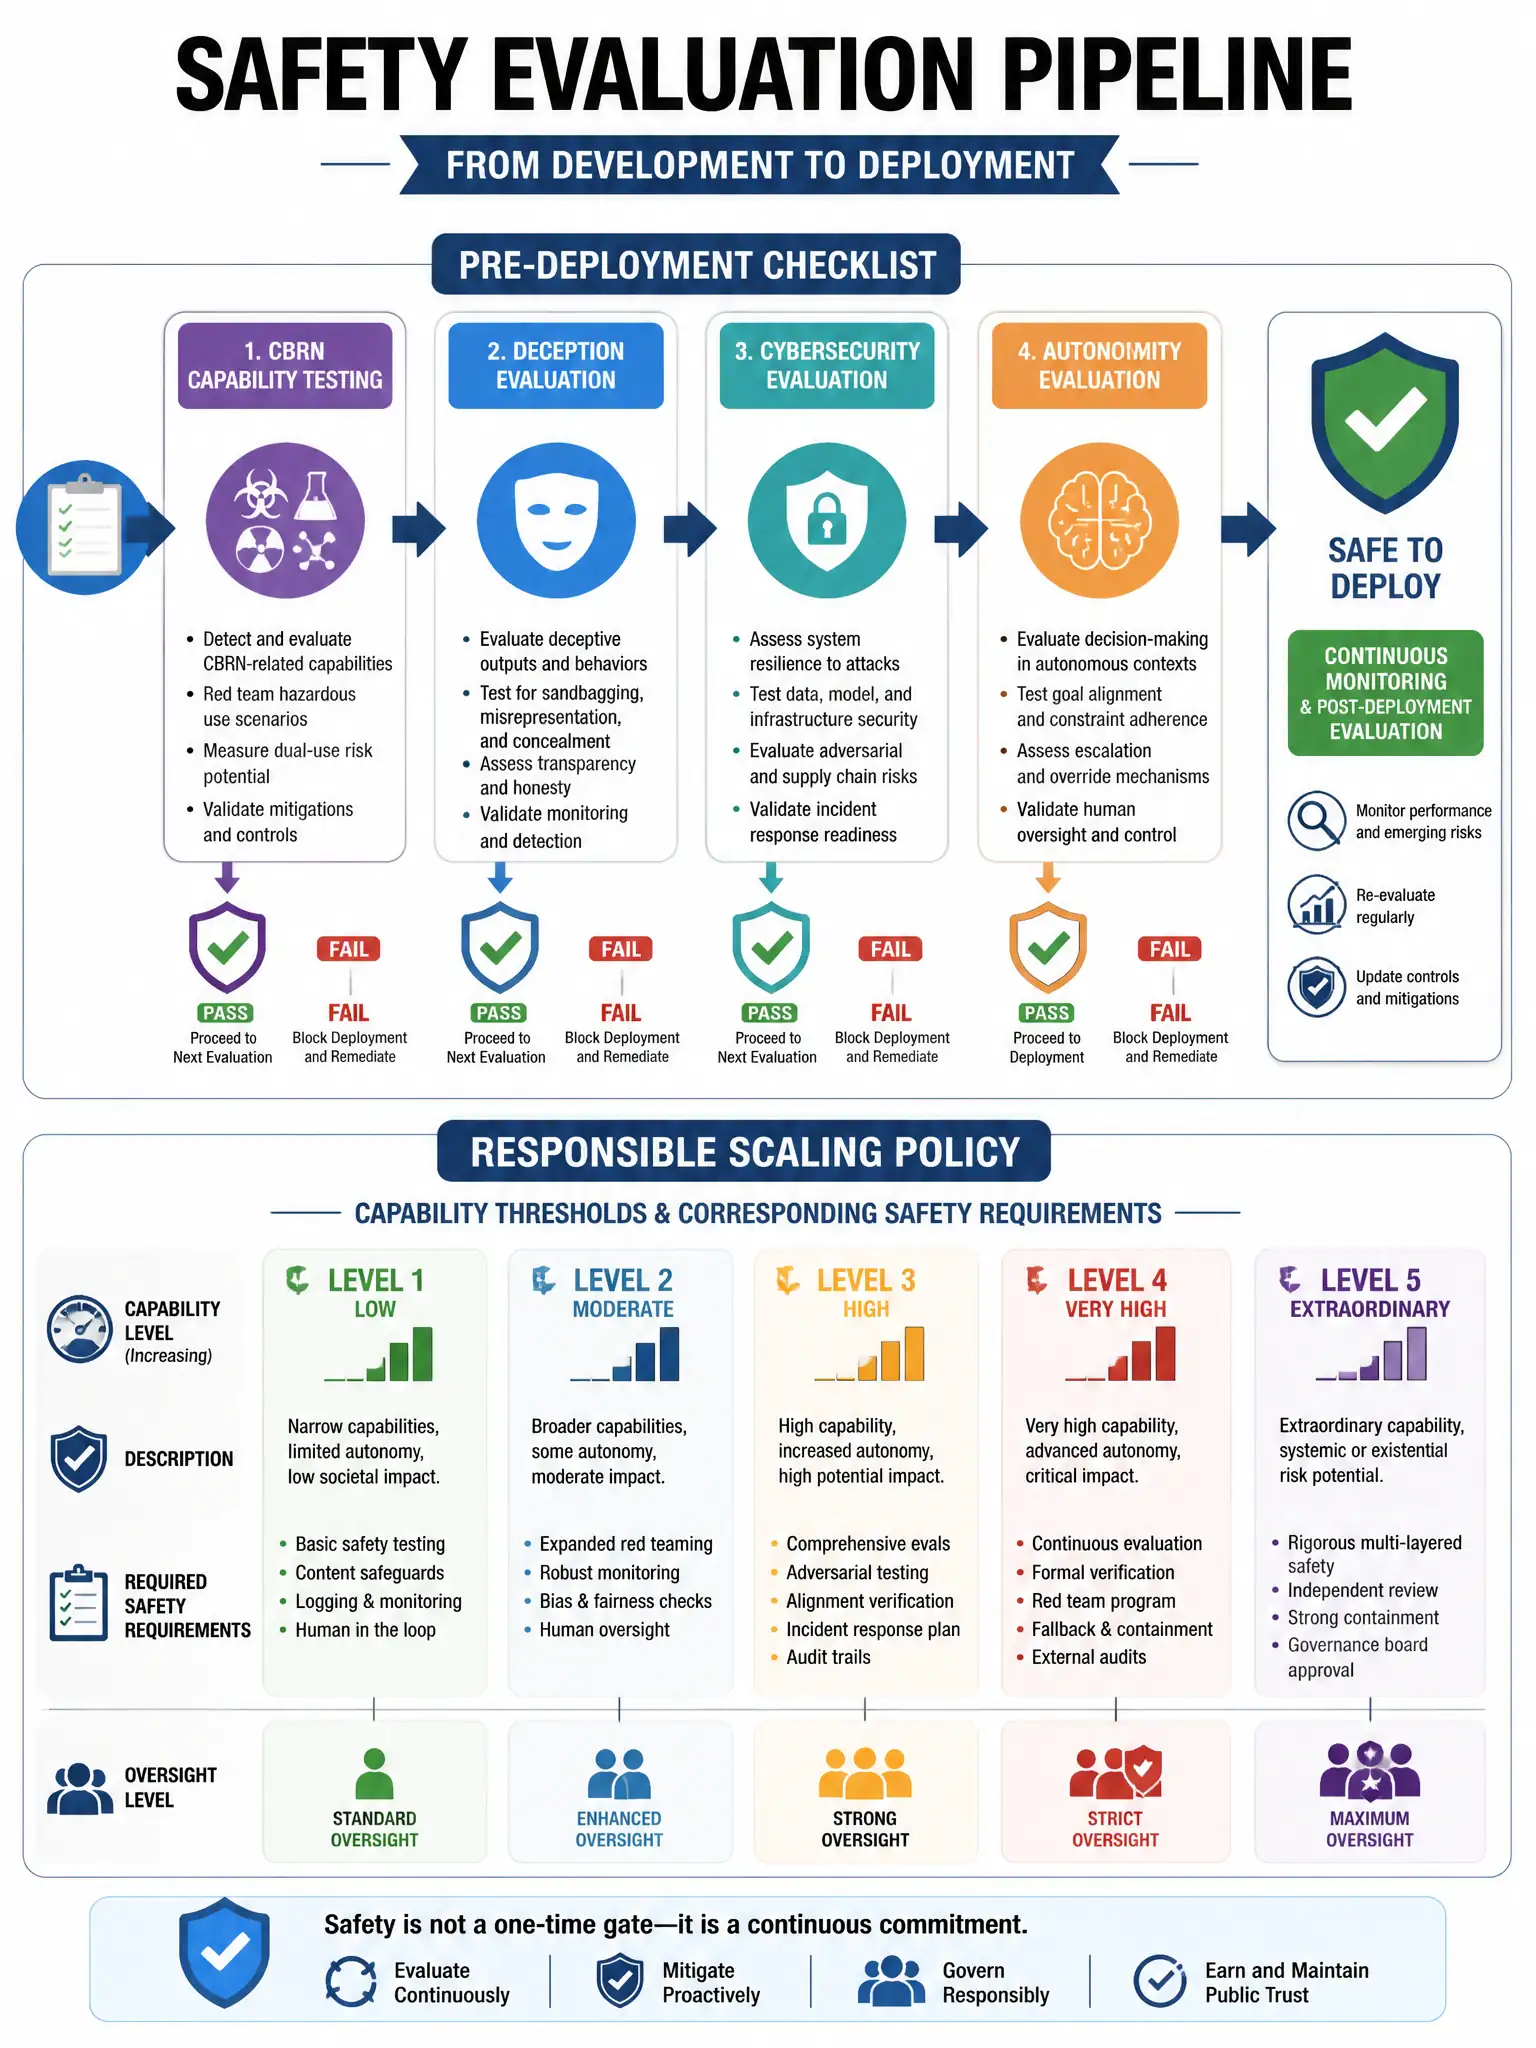
Before shipping a new model, you run safety tests specifically looking for dangerous capabilities — like CBRN assistance or autonomous deception — to make sure it's safe to deploy.
Full Explanation
Anthropic's safety evaluations are a critical part of their responsible scaling policy. They test for dangerous capabilities including: assistance with CBRN (chemical, biological, radiological, nuclear) weapons, cyberoffense capabilities, deceptive alignment (model appearing aligned in evals but not in deployment), and other high-stakes risks. These evaluations determine whether a model can be safely deployed and at what capability thresholds additional safeguards are needed. The competitor benchmarking choice is a separate activity. The pricing choice is a business decision unrelated to safety evals. The feature-removal choice describes optimization, not safety evaluation.