
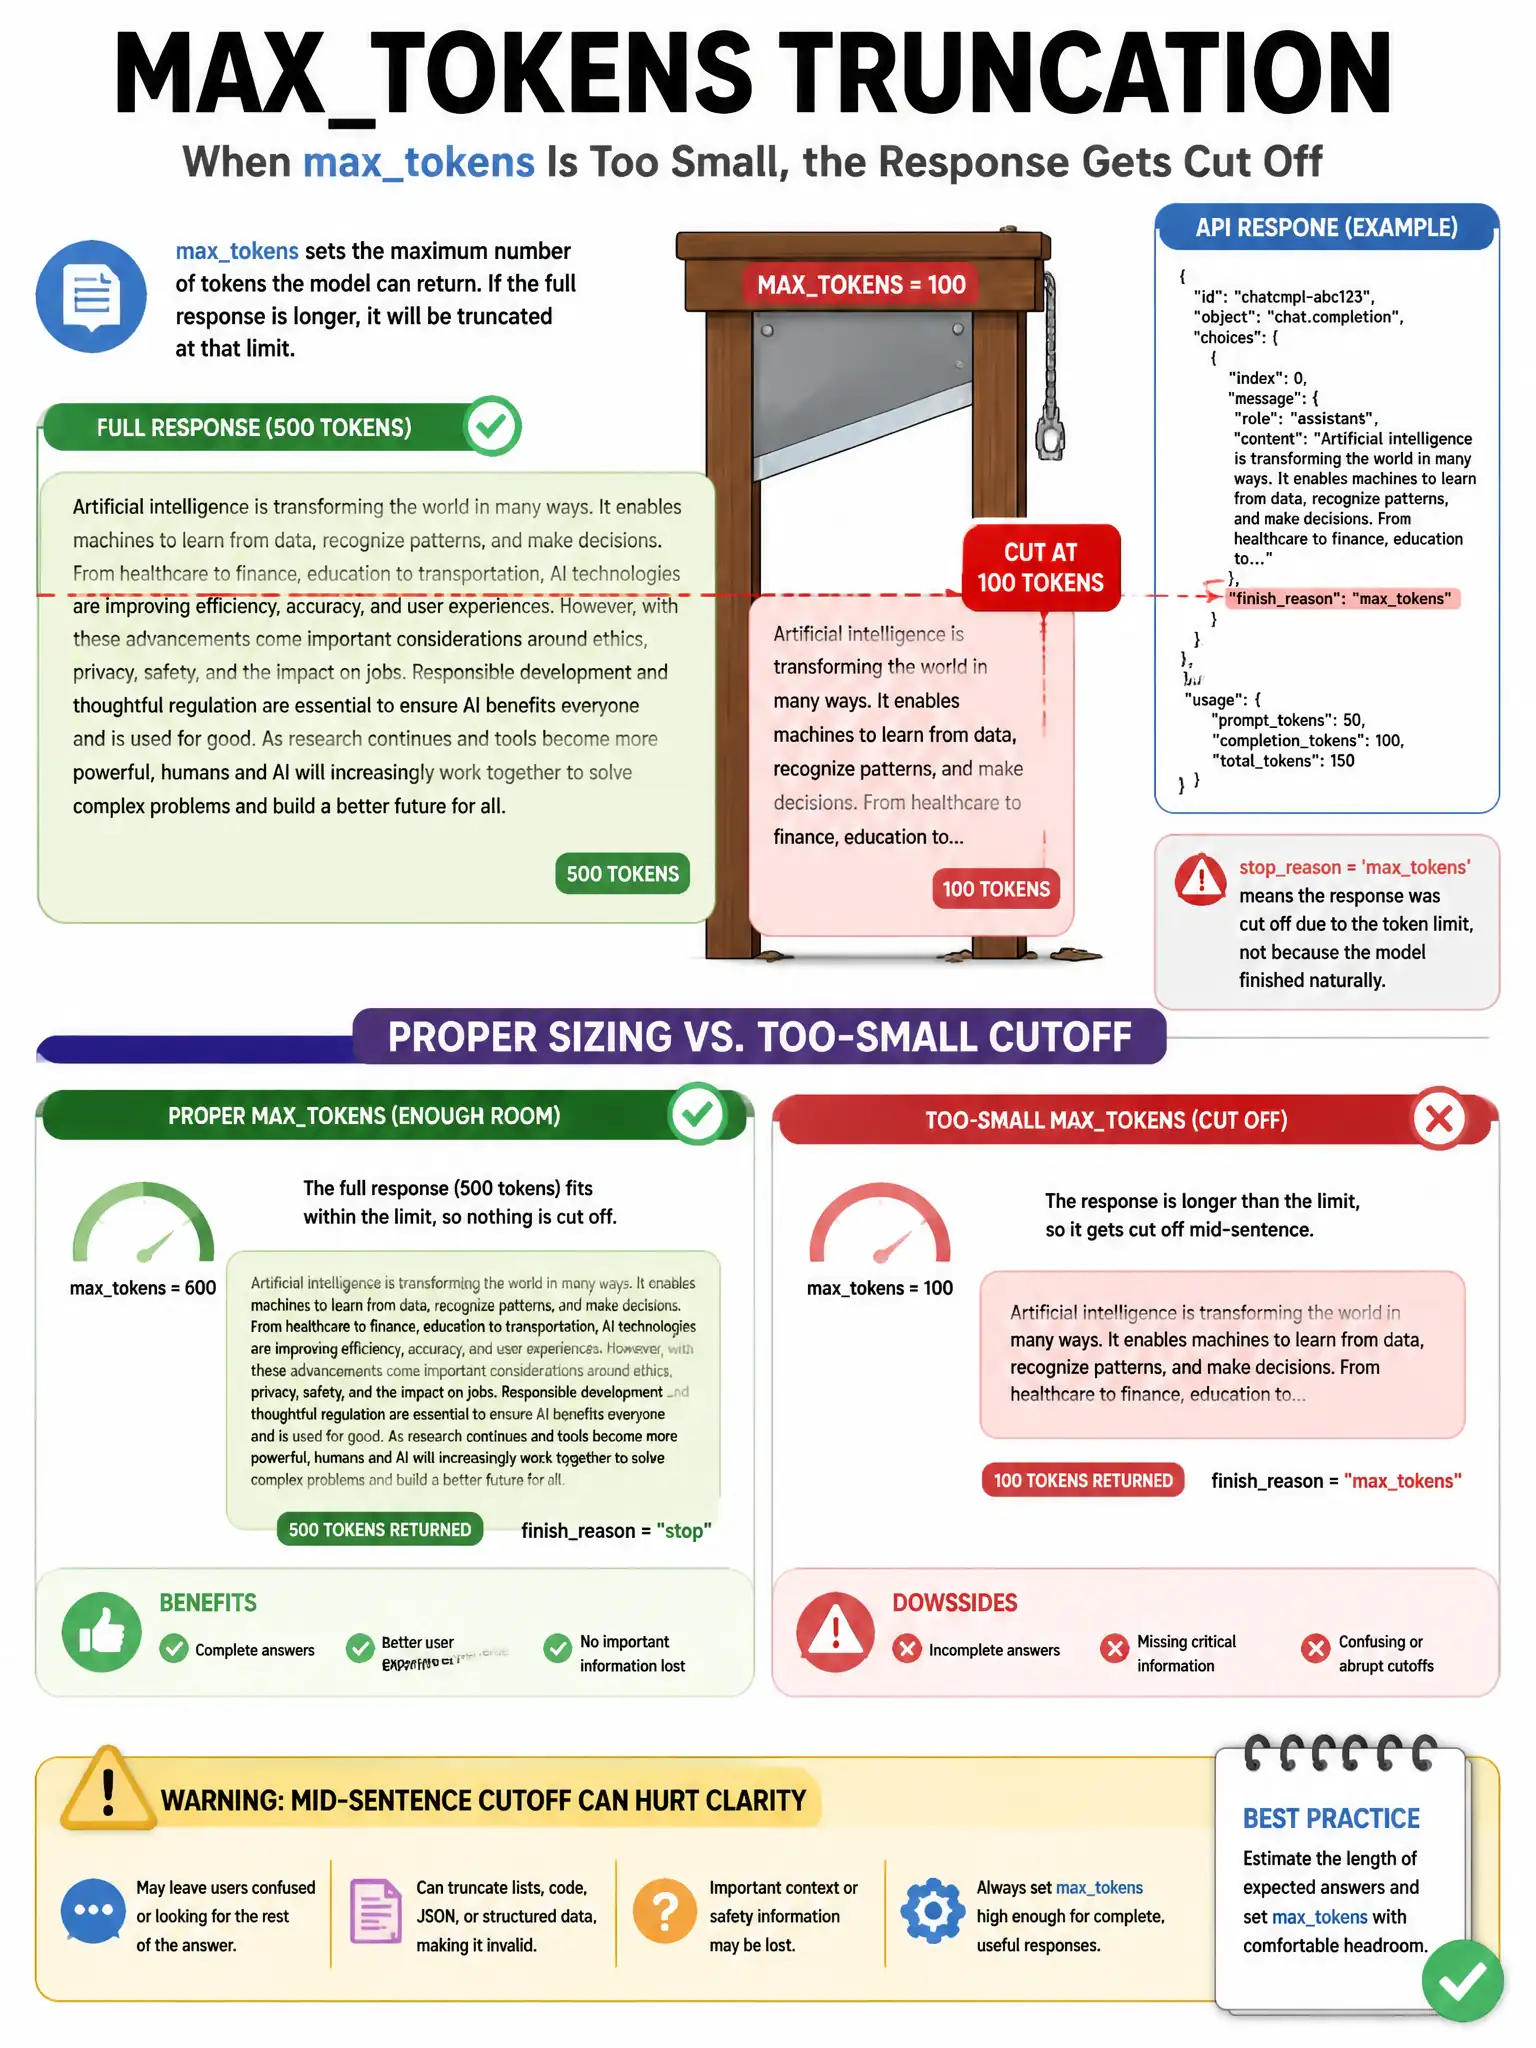
If you set max_tokens=100 and Claude's natural response would be 500 tokens, what happens?
Select an answer to reveal the explanation.
Short Explanation
You're setting a hard ceiling with max_tokens, so when Claude hits it, generation stops wherever it is, even mid-word. It doesn't gracefully summarize; it just stops.
Full Explanation
The correct behavior is that Claude's response is truncated at 100 tokens, potentially mid-sentence. The max_tokens parameter is a hard limit. When Claude reaches that token count, generation stops immediately — the response may be cut off mid-sentence, mid-word, or mid-thought. The API returns a stop_reason of 'max_tokens' rather than 'end_turn' to indicate the response was cut short. This means developers should set max_tokens high enough for their expected use case, or handle the 'max_tokens' stop reason to notify users the response was truncated. The option saying the API returns an error because the response exceeds the limit is wrong — no error is returned. The option saying Claude automatically summarizes its response to fit within 100 tokens is wrong — Claude doesn't auto-summarize. The option saying Claude ignores max_tokens if it determines more tokens are needed for a complete response is wrong — Claude strictly respects the limit.