
When Claude is described as 'multimodal,' what does this mean?
Select an answer to reveal the explanation.
Short Explanation
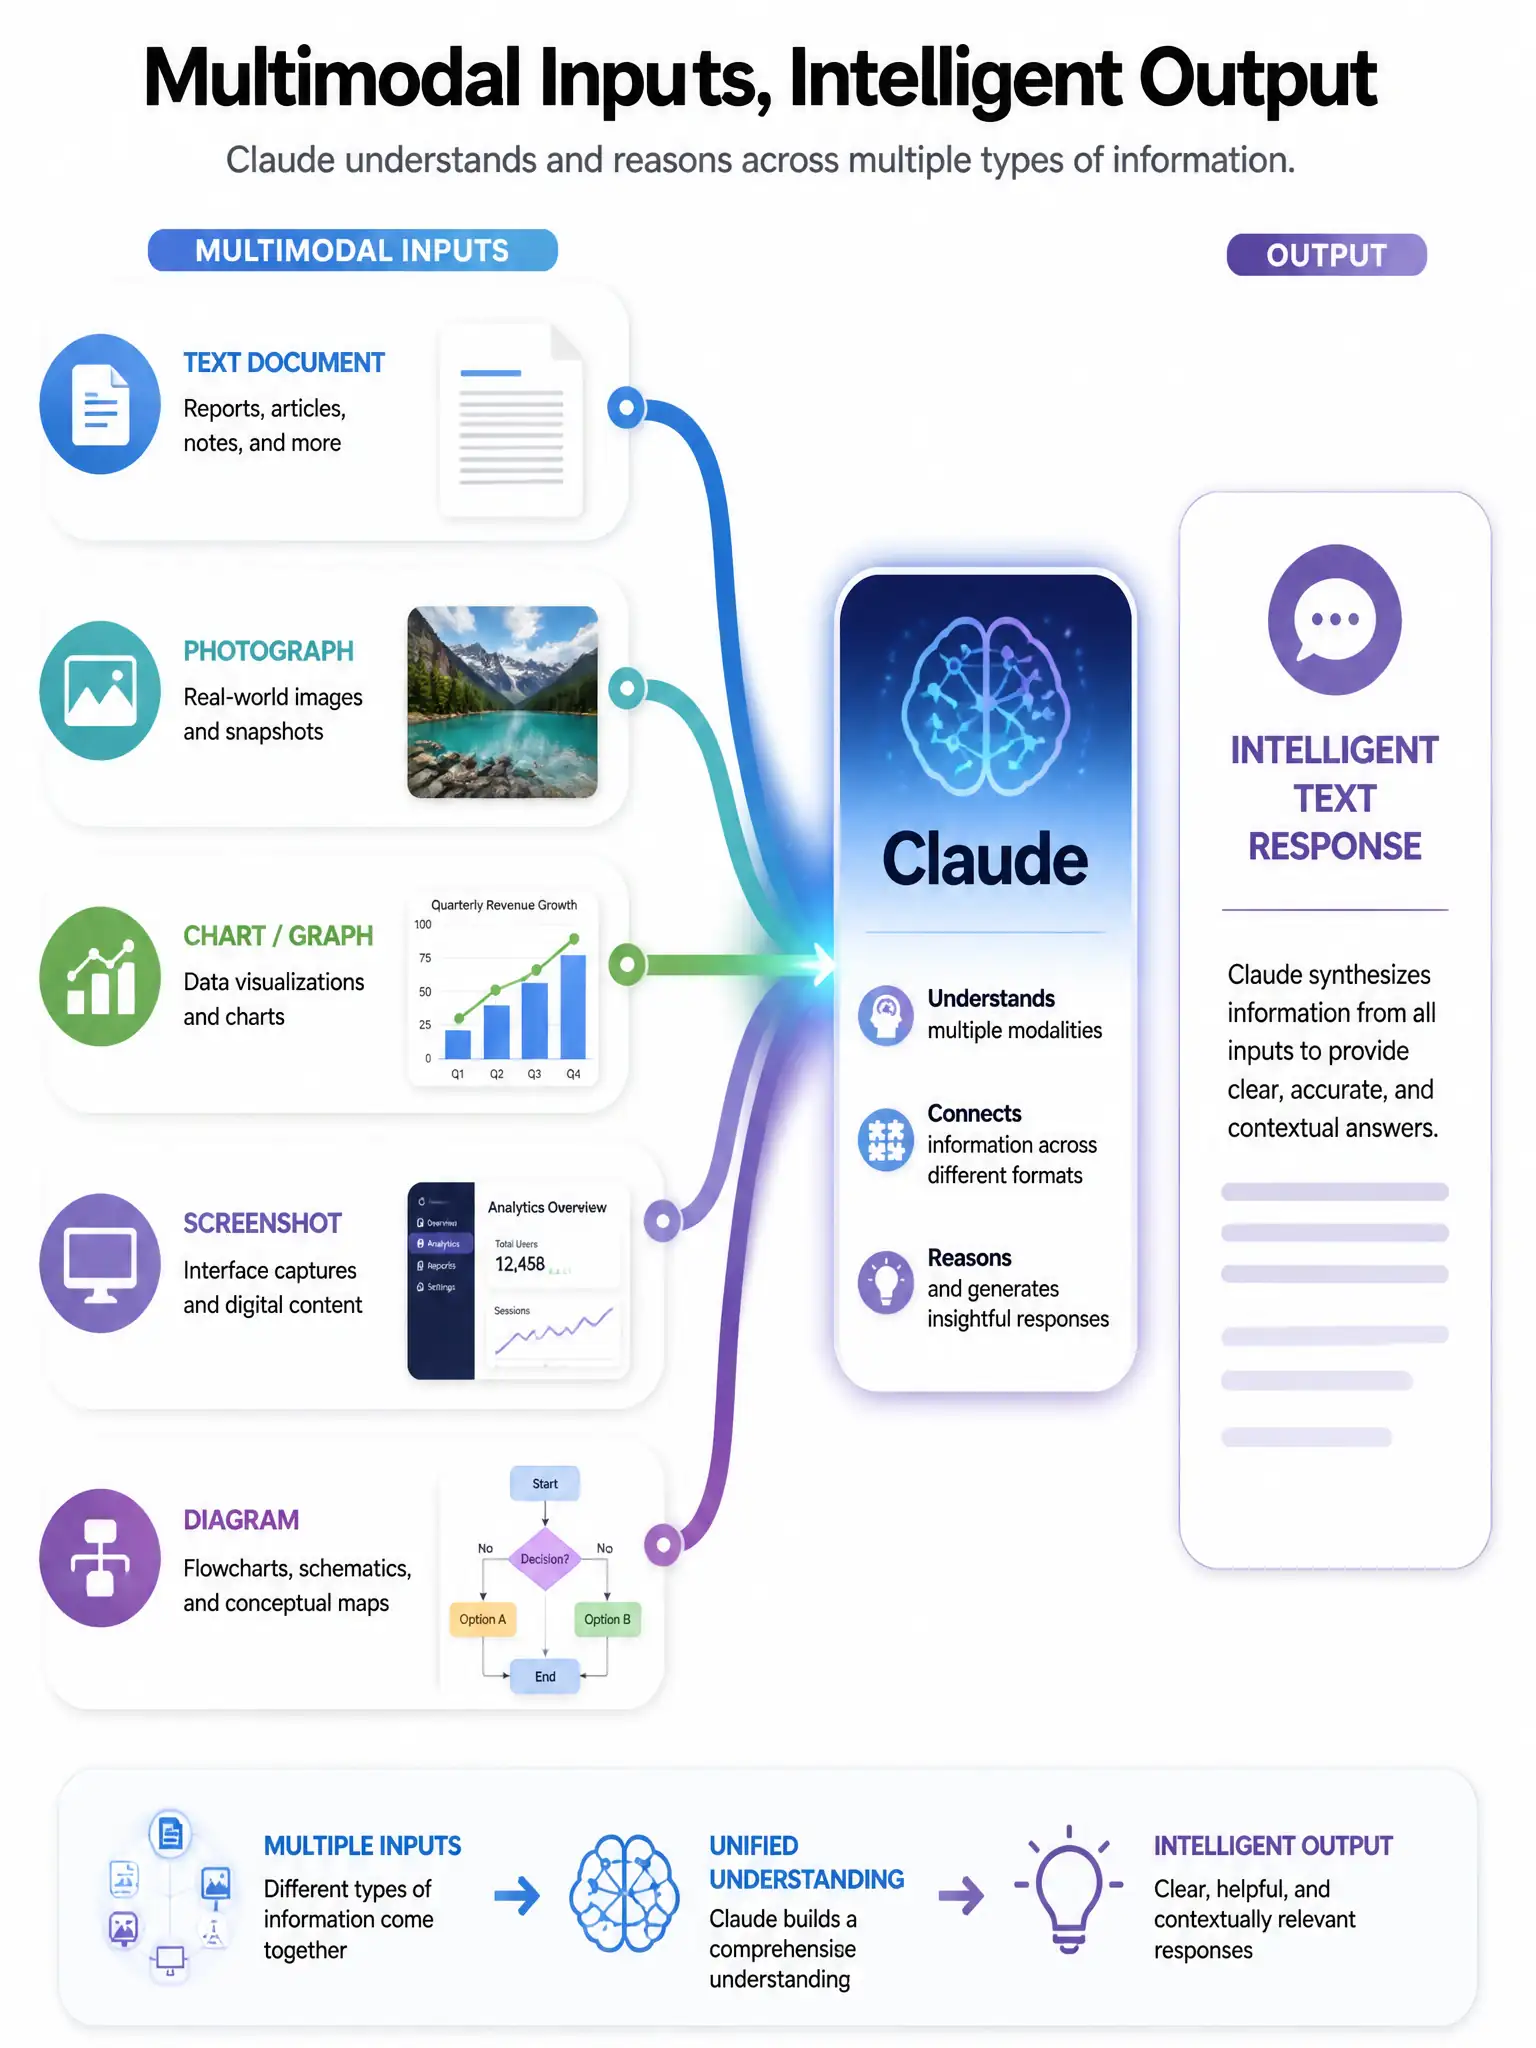
When Claude is called multimodal, you're saying it can handle more than text. Show it a diagram, chart, photo, or screenshot, and it can reason about what it sees alongside what you type.
Full Explanation
Multimodal refers to a model's ability to process and reason about multiple types of data modalities. The correct meaning here is that Claude can process multiple types of input data, such as text and images. Claude's vision capability allows it to accept both text and images as input, and future capabilities may include audio or video. This enables use cases like analyzing charts from screenshots, reading text in images, interpreting diagrams, and checking UI designs. The description about speaking multiple human languages refers to multilingual capability, which Claude also has, but that is not what multimodal means. The description about being deployed across multiple cloud providers simultaneously refers to deployment architecture. The description about running across multiple GPUs for distributed processing refers to distributed computing infrastructure, which is separate from the model's input capabilities.